35 min read
TPU Inference Externalization Full Steam Ahead
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
- benchmark
- inference
- tpu
- +7
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
10 articles
35 min read
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
2 min read
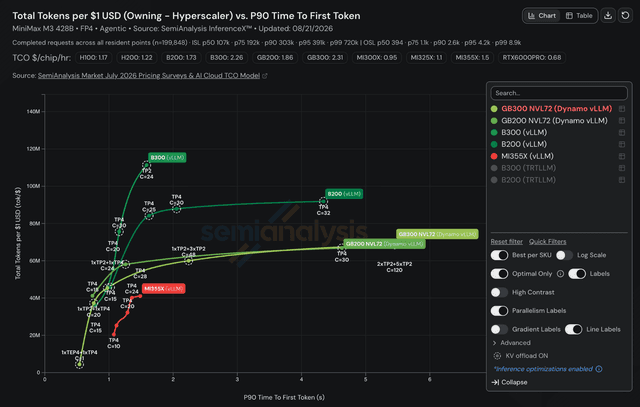
NVIDIA sweeps the 432B model, and the missing DP-attention points explain why cache locality became a routing constraint
17 min read
Can TileRT software on NVIDIA GPUs compete with Cerebras, Groq LPU, and SambaNova? Batch size 1, disaggregated engine, high-throughput prefill engine, high-interactivity decode engine
23 min read
Kimi K3's architecture: compressed memory, attention across depth, latent expert routing, and serving performance
29 min read
Day 0 Inference Performance, InferenceX, 100x performance improvement in 26 Days, Cost per Million Tokens, Huawei 950DT Inference Trace Analysis

10 min read
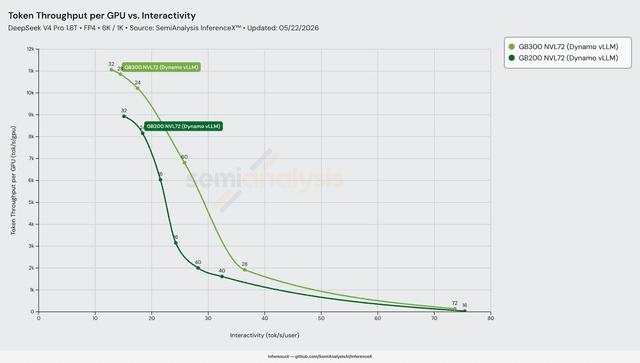
DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

12 min read
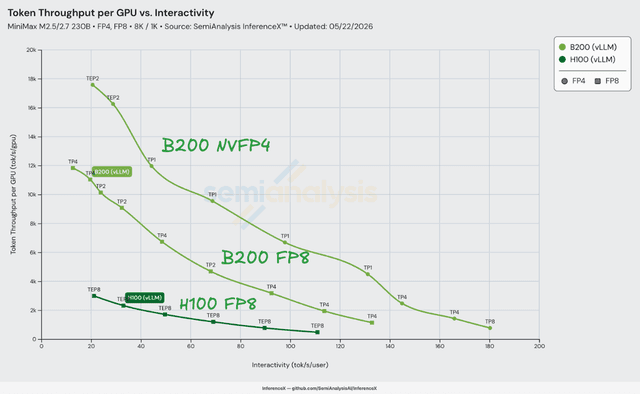
vLLM PR #36307 unlocks the trtllm-gen FP8 MoE kernel for MiniMax on B200; combined with NVFP4, perf/$ scales from 4.0x at 22 tok/s/user to 8.2x at 110 on 8K/1K

11 min read
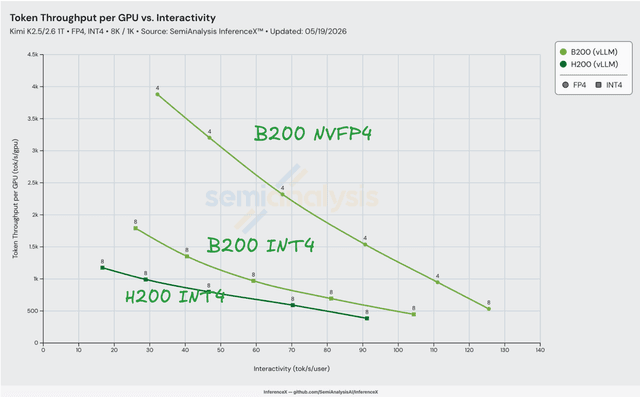
On vLLM 8K/1K the NVFP4 path on B200 is 2.71x–2.95x cheaper per million tokens than H200 INT4 across the entire 30–90 tok/s/user serving band, and 2.45x–2.74x cheaper than B200 INT4 on the same silicon. Both factors decompose cleanly into B200's HBM bandwidth, HBM capacity, and NVFP4 tensor cores

6 min read
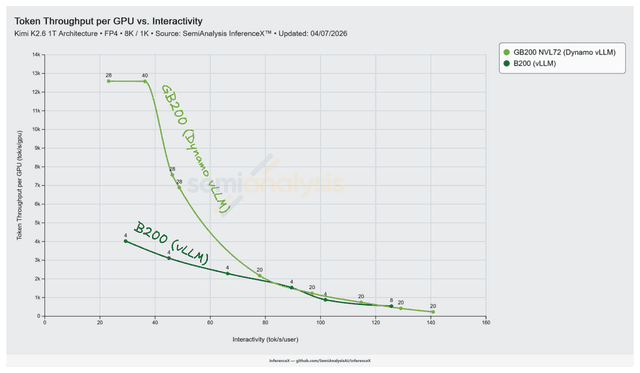
Rack scale NVLink on NVL72 lets Dynamo vLLM run Kimi K2.5 wide EP up to Decode EP 16, taking peak throughput from 4,021 to 12,587 tok/s/GPU on 8k/1k NVFP4

6 min read
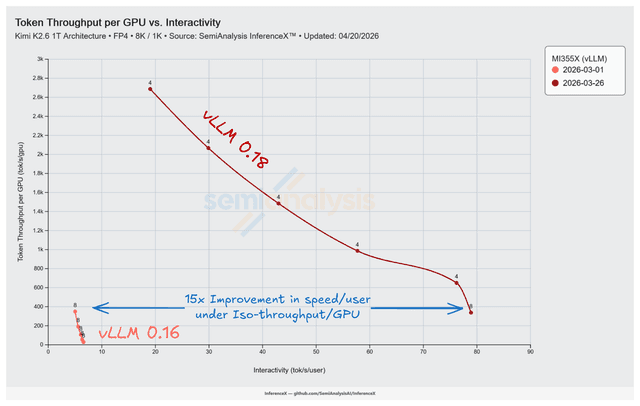
vLLM PR #35850 Fixed AITER MLA Dispatch on MI355X CDNA4, Unlocking Kimi K2.5 Inference Performance at TP=8, Shipped in vLLM 0.18