3 min read
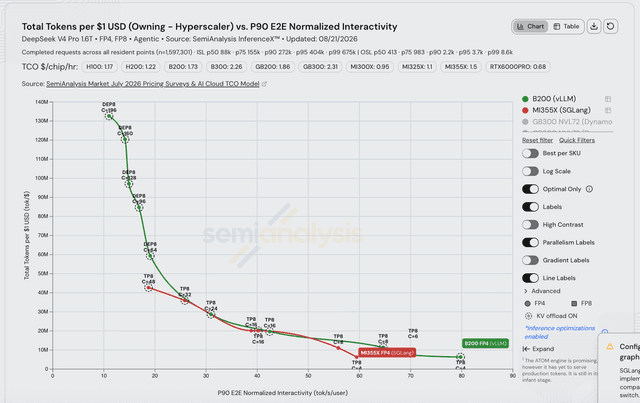
DeepSeek V4 Pro on AgentX: MI355X vs B200, and the August 21 Flip
AMD matched B200 vLLM on performance per dollar for end-to-end latency, then upstream vLLM work moved the line
- agentx
- agentic
- benchmark
- +6
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
9 articles
3 min read
AMD matched B200 vLLM on performance per dollar for end-to-end latency, then upstream vLLM work moved the line
2 min read
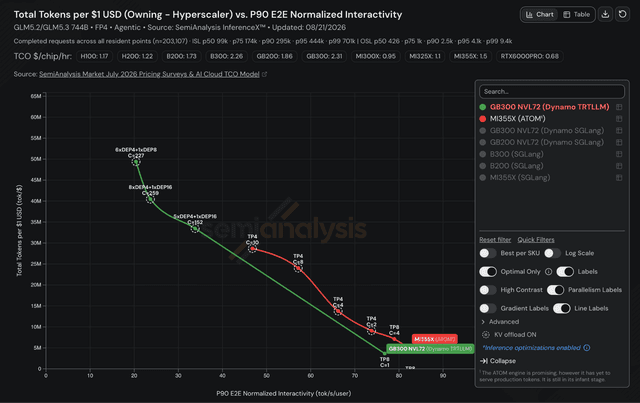
Where AMD’s vendor engine wins on performance per dollar, and what E2E Normalized Interactivity actually measures
2 min read
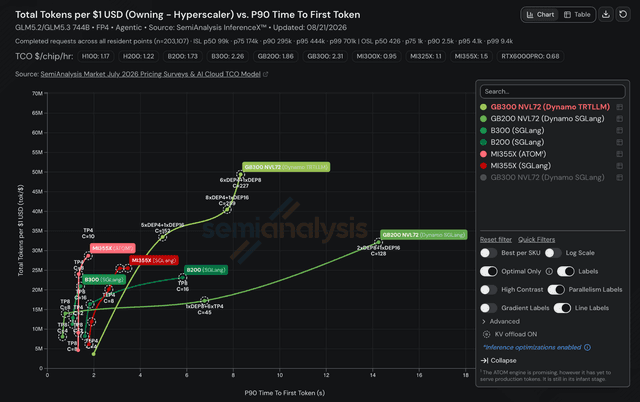
At this operating point, free AMD silicon would still not close the gap
2 min read
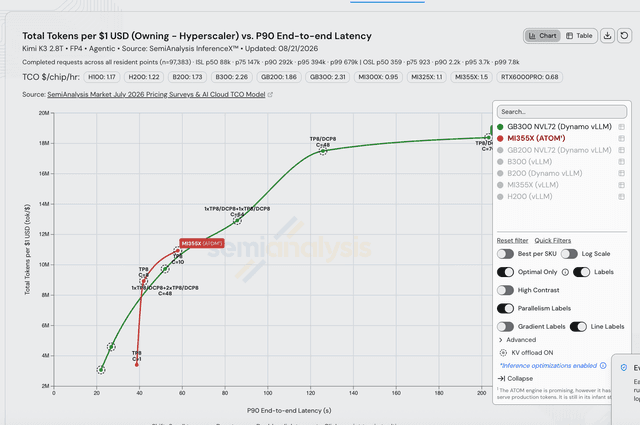
AMD’s vendor engine wins a real slice of the performance per dollar frontier, while Hopper struggles to serve K3 at all
29 min read
Day 0 Inference Performance, InferenceX, 100x performance improvement in 26 Days, Cost per Million Tokens, Huawei 950DT Inference Trace Analysis

13 min read
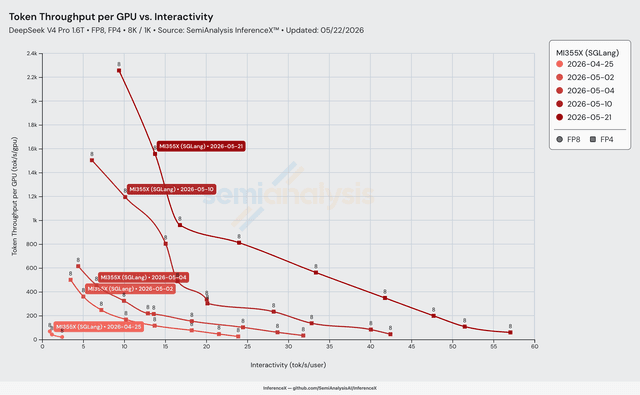
The amd/deepseek_v4 side branch shipped TileLang attention indexer, Triton sparse MLA, fused RoPE/Hadamard, FlyDSL MoE, and FP4 weights across 31 performance optimizations PRs — lifting first-light 20 tok/s/GPU at 2.4 tok/s/user into 2,256 tok/s/GPU at 9.4 tok/s/user on 8K/1K, with both throughput and interactivity climbing together

7 min read
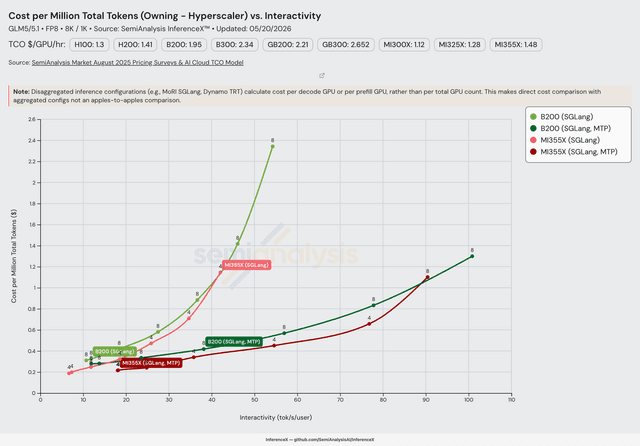
14 weeks after GLM-5 launched, AMD landed both MTP and non-MTP SGLang FP8 recipes on MI355X — fused MLA + FP8 KV cache via TileLang flips the single-node FP8 cost curve in AMD favor across most of the performance Pareto

6 min read
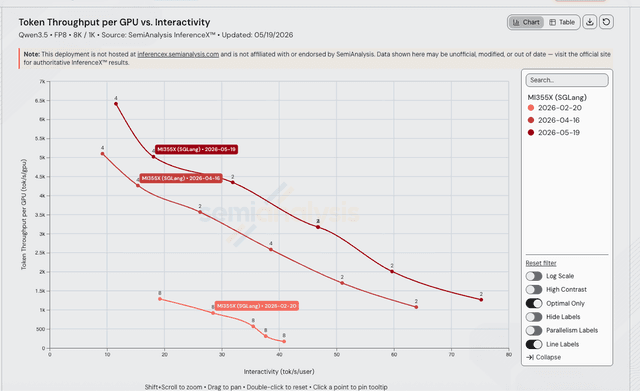
From v0.5.8 (Feb) → v0.5.10rc0 (Apr) → v0.5.12 (May), three AITER kernel landings on MI355X plus a TP=8 → TP=2/TP=4 retune push Qwen3.5 8k/1k peak from 1.3k to 6.4k tok/s/GPU and extend the curve out to 75 tok/s/user

6 min read
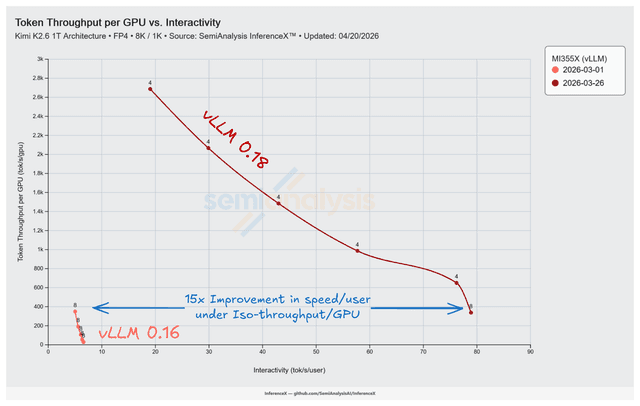
vLLM PR #35850 Fixed AITER MLA Dispatch on MI355X CDNA4, Unlocking Kimi K2.5 Inference Performance at TP=8, Shipped in vLLM 0.18