2 min read
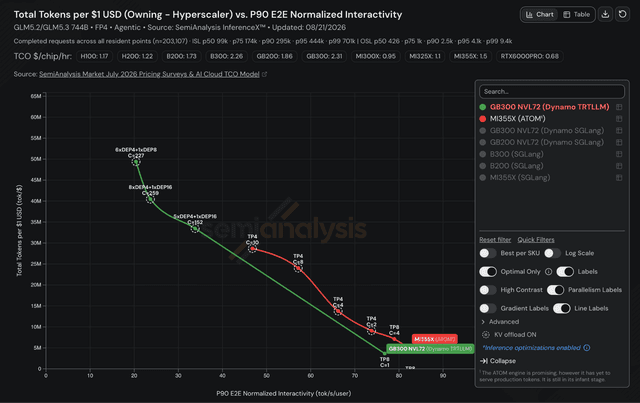
GLM 5.3 on AgentX: MI355X ATOM Beats GB300 NVL72 on Part of the Curve
Where AMD’s vendor engine wins on performance per dollar, and what E2E Normalized Interactivity actually measures
- agentx
- agentic
- benchmark
- +9
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
5 articles
2 min read
Where AMD’s vendor engine wins on performance per dollar, and what E2E Normalized Interactivity actually measures
2 min read
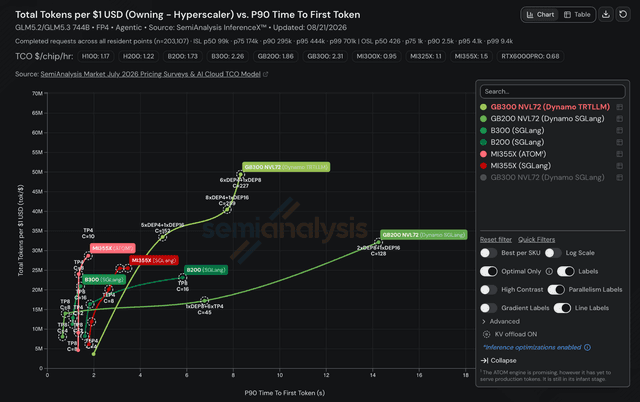
At this operating point, free AMD silicon would still not close the gap
17 min read
Can TileRT software on NVIDIA GPUs compete with Cerebras, Groq LPU, and SambaNova? Batch size 1, disaggregated engine, high-throughput prefill engine, high-interactivity decode engine

10 min read
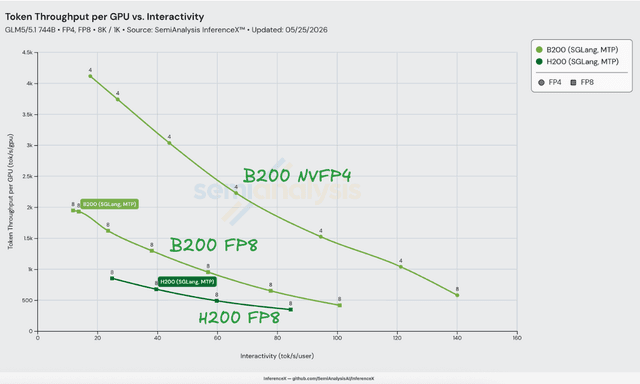
Both SKUs run SGLang EAGLE MTP; the Blackwell generation lifts perf/$ by ~1.2x at the peak and the NVIDIA GLM-5-NVFP4 checkpoint on FlashInfer TRT-LLM sparse MLA stacks another ~2.4–3.0x on 8K/1K

7 min read
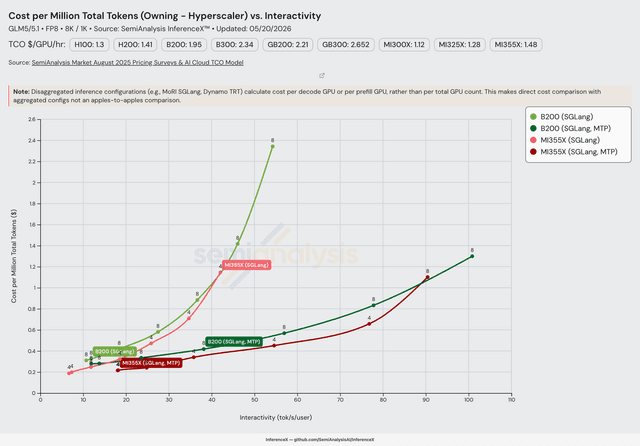
14 weeks after GLM-5 launched, AMD landed both MTP and non-MTP SGLang FP8 recipes on MI355X — fused MLA + FP8 KV cache via TileLang flips the single-node FP8 cost curve in AMD favor across most of the performance Pareto