8 min read
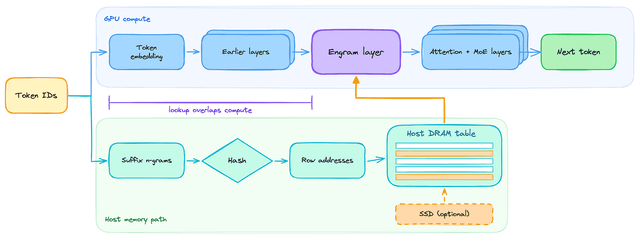
Engrams Embedding Entendre: Codesign for Efficient DRAM/SSD Offloading
New Model Architecture Implications for TAM of DRAM/NVMe, DeepSeek V4.1 Flash, AgentX, InferenceX, NVMe experiments
- inference
- agentx
- deepseek
- +3
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
11 articles
8 min read
New Model Architecture Implications for TAM of DRAM/NVMe, DeepSeek V4.1 Flash, AgentX, InferenceX, NVMe experiments
10 min read
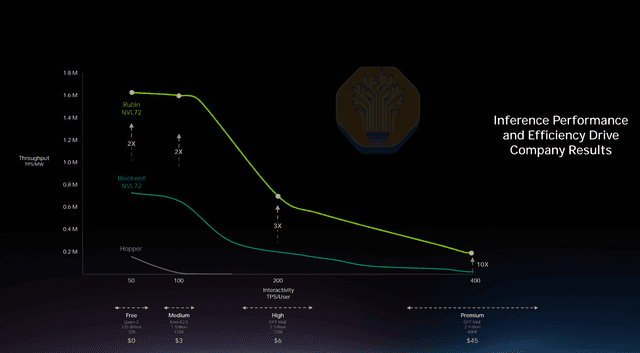
Jensen Sandbagging Performance Again, 2x more Annual Profit Per GigaWatt, The More you Buy, The More you Earn, AgentX, InferenceX, Extreme Co-Design
3 min read
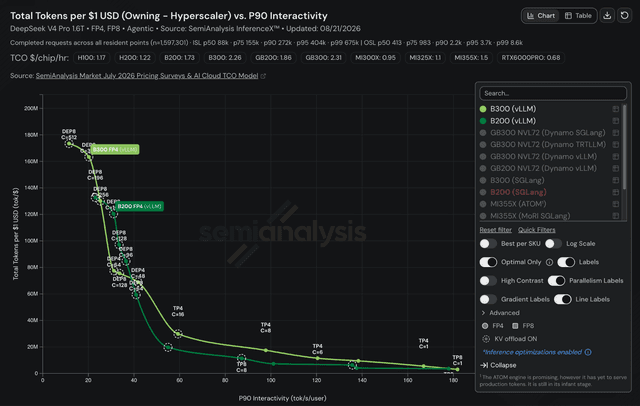
50% more HBM squeezes out extra throughput, and the per-point telemetry shows exactly where it comes from
2 min read
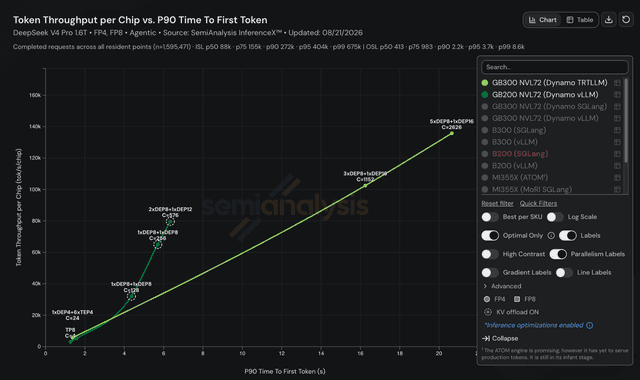
Both lean on PD disagg, GB300 adds DEP32 wide-EP decode, and the gap shows up in first-token latency rather than token rate
3 min read
AMD matched B200 vLLM on performance per dollar for end-to-end latency, then upstream vLLM work moved the line
20 min read
Rubin LUT Based Tensor Core, Feynman, Rack Scale, Perf Per MegaWatt, Perf Per Dollar, Software Improvements, Public Rubin Software, PyTorch, vLLM, OpenAI Triton
29 min read
Day 0 Inference Performance, InferenceX, 100x performance improvement in 26 Days, Cost per Million Tokens, Huawei 950DT Inference Trace Analysis

10 min read
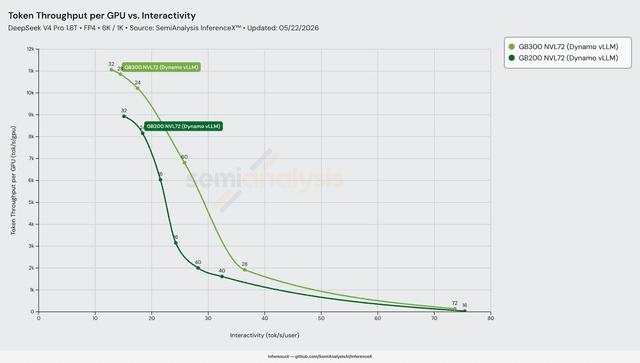
DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

13 min read
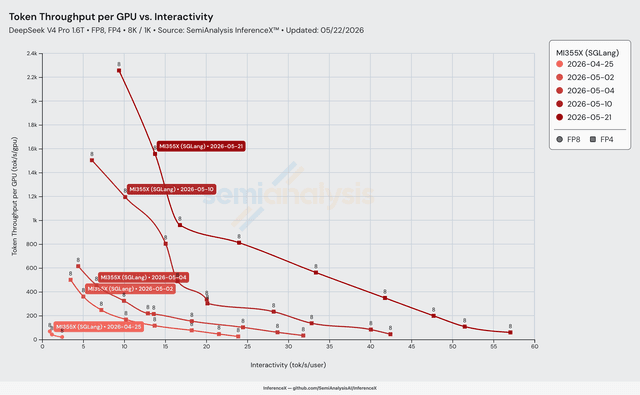
The amd/deepseek_v4 side branch shipped TileLang attention indexer, Triton sparse MLA, fused RoPE/Hadamard, FlyDSL MoE, and FP4 weights across 31 performance optimizations PRs — lifting first-light 20 tok/s/GPU at 2.4 tok/s/user into 2,256 tok/s/GPU at 9.4 tok/s/user on 8K/1K, with both throughput and interactivity climbing together

8 min read
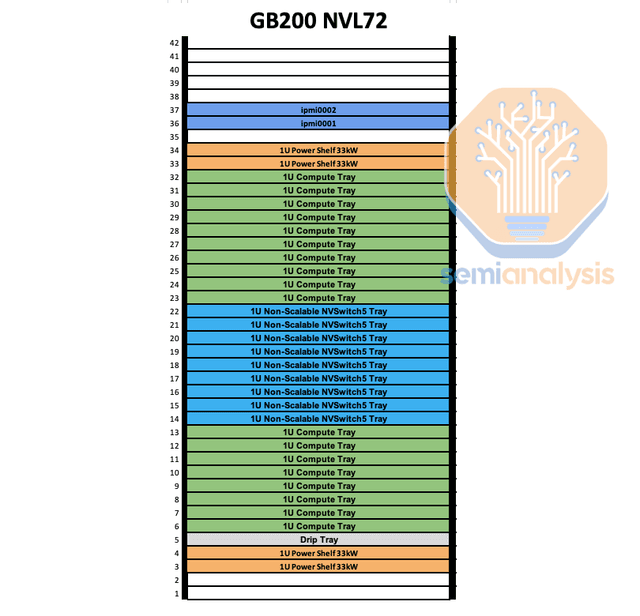
DeepSeek R1 FP4 1k/1k. NVL72's 72-GPU NVLink scale-up fabric lets decode run wide EP up to EP=32, where B200's 8-GPU NVLink island caps out at EP=8 over RoCEv2

5 min read
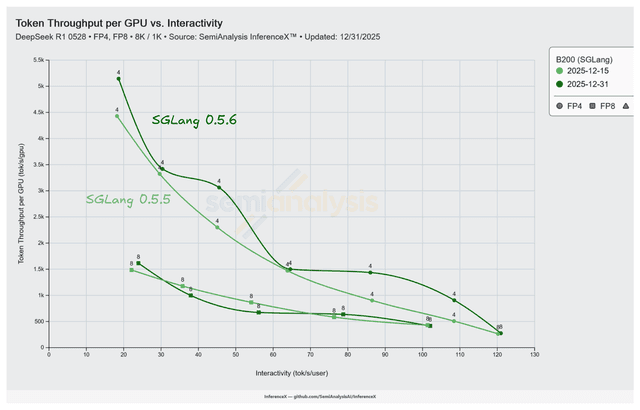
Piecewise CUDA graphs for DeepSeek V3, a unified event loop, and JIT kernels push 8k/1k throughput from 508 to 907 tok/s/GPU on the same 16 GPU B200 pool