
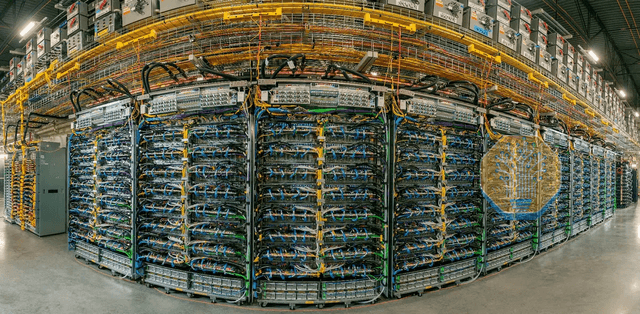
35 min read
TPU Inference Externalization Full Steam Ahead
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
- benchmark
- inference
- tpu
- +7
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
8 articles
35 min read
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
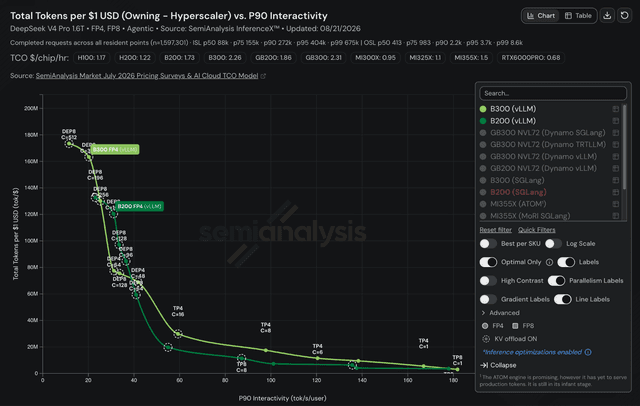
3 min read
50% more HBM squeezes out extra throughput, and the per-point telemetry shows exactly where it comes from
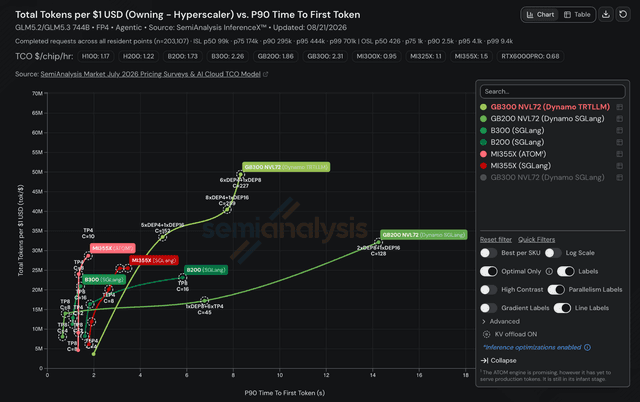
2 min read
At this operating point, free AMD silicon would still not close the gap
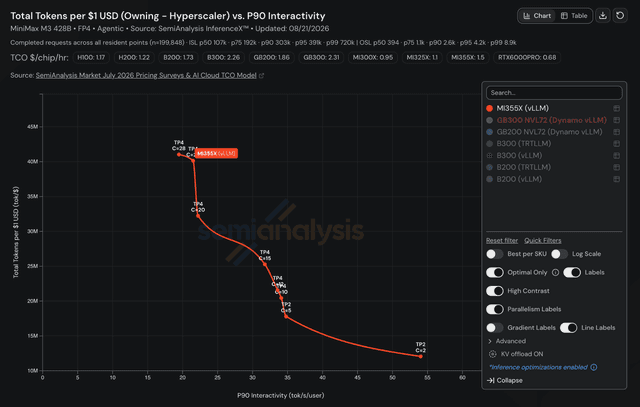
3 min read
The Dynamo router becomes the bottleneck, no submission runs context parallelism, and AMD leaves KV offload on the table
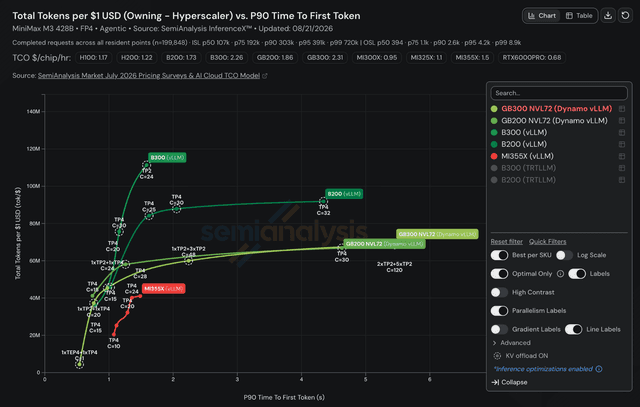
2 min read
NVIDIA sweeps the 432B model, and the missing DP-attention points explain why cache locality became a routing constraint
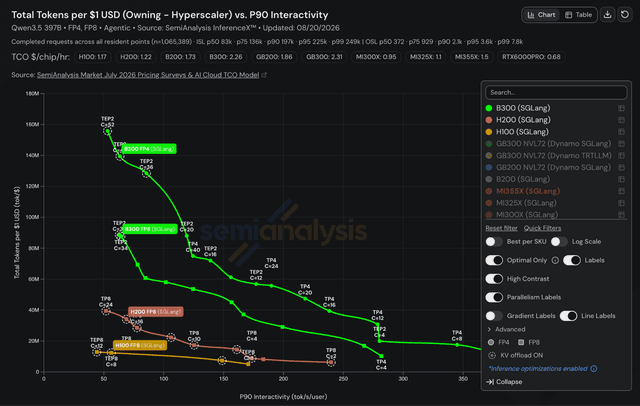
2 min read
What four years of hardware and a 4-bit format buy on a long-context agentic workload
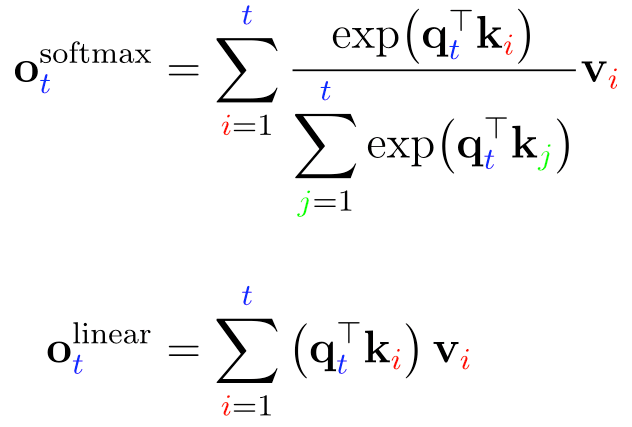
23 min read
Kimi K3's architecture: compressed memory, attention across depth, latent expert routing, and serving performance
29 min read
Day 0 Inference Performance, InferenceX, 100x performance improvement in 26 Days, Cost per Million Tokens, Huawei 950DT Inference Trace Analysis