2 min read
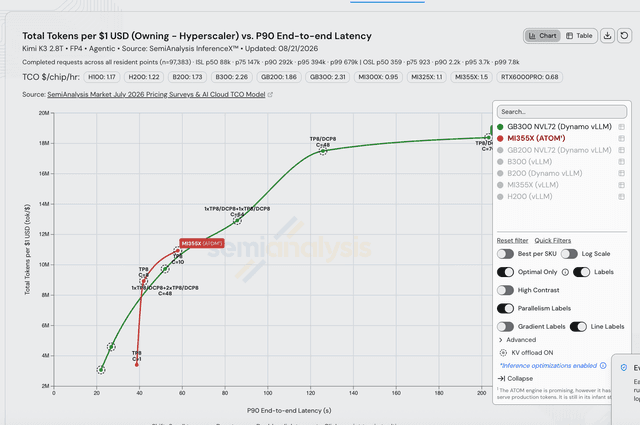
Kimi K3 on AgentX: MI355X ATOM Beats GB300 NVL72 on Part of the Curve
AMD’s vendor engine wins a real slice of the performance per dollar frontier, while Hopper struggles to serve K3 at all
- agentx
- agentic
- benchmark
- +8
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
5 articles
2 min read
AMD’s vendor engine wins a real slice of the performance per dollar frontier, while Hopper struggles to serve K3 at all
23 min read
Kimi K3's architecture: compressed memory, attention across depth, latent expert routing, and serving performance

11 min read
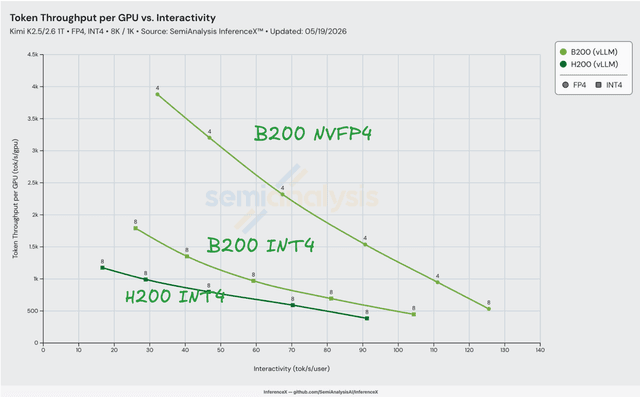
On vLLM 8K/1K the NVFP4 path on B200 is 2.71x–2.95x cheaper per million tokens than H200 INT4 across the entire 30–90 tok/s/user serving band, and 2.45x–2.74x cheaper than B200 INT4 on the same silicon. Both factors decompose cleanly into B200's HBM bandwidth, HBM capacity, and NVFP4 tensor cores

6 min read
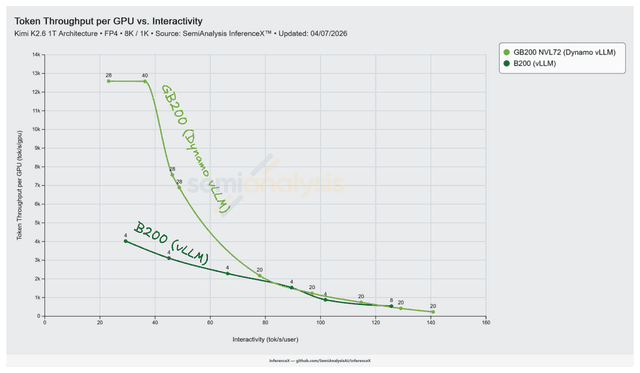
Rack scale NVLink on NVL72 lets Dynamo vLLM run Kimi K2.5 wide EP up to Decode EP 16, taking peak throughput from 4,021 to 12,587 tok/s/GPU on 8k/1k NVFP4

6 min read
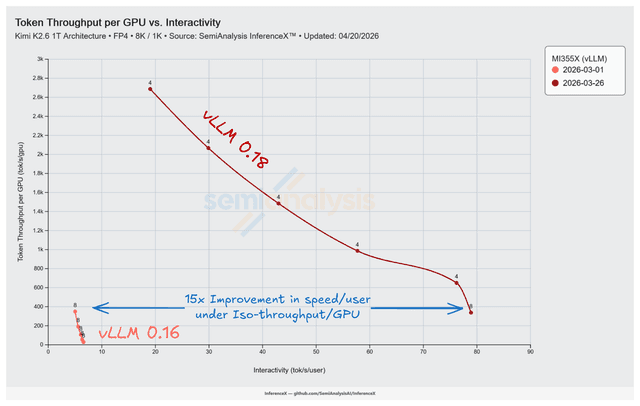
vLLM PR #35850 Fixed AITER MLA Dispatch on MI355X CDNA4, Unlocking Kimi K2.5 Inference Performance at TP=8, Shipped in vLLM 0.18