InferenceX Research

Articles

Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.

New to the terminology? Browse the AI inference glossary.

35 min read

TPU Inference Externalization Full Steam Ahead

InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat

  • benchmark
  • inference
  • tpu
  • +7

10 min read

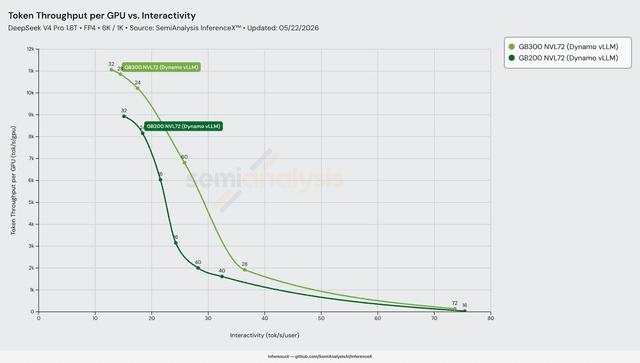
GB300 NVL72 vs GB200 NVL72 Inference Performance & Perf per Dollar - on DeepSeek-V4-Pro 1.6T: Up to 2.83x Throughput

DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

  • benchmark
  • gpu
  • inference
  • +9

10 min read

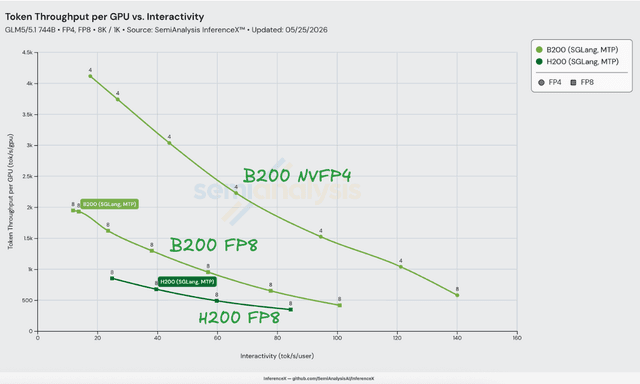
B200 NVFP4 vs H200 FP8 on GLM-5: Up to 3.65x Better Performance per Dollar with SGLang MTP

Both SKUs run SGLang EAGLE MTP; the Blackwell generation lifts perf/$ by ~1.2x at the peak and the NVIDIA GLM-5-NVFP4 checkpoint on FlashInfer TRT-LLM sparse MLA stacks another ~2.4–3.0x on 8K/1K

  • benchmark
  • gpu
  • inference
  • +6

12 min read

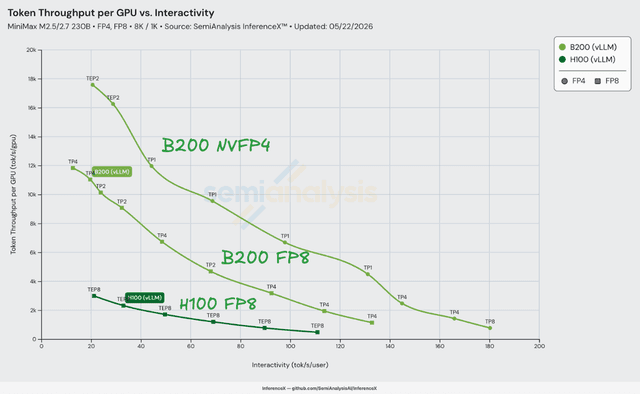
B200 NVFP4 vs H100 FP8 on MiniMax-M2.5: Up to 8.2x Better Performance per Dollar with vLLM

vLLM PR #36307 unlocks the trtllm-gen FP8 MoE kernel for MiniMax on B200; combined with NVFP4, perf/$ scales from 4.0x at 22 tok/s/user to 8.2x at 110 on 8K/1K

  • benchmark
  • gpu
  • inference
  • +6

11 min read

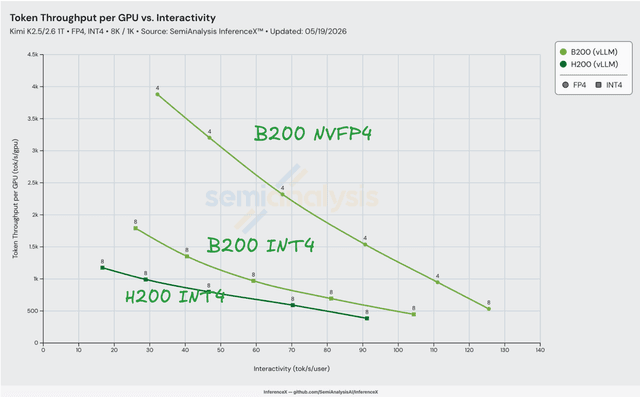
B200 NVFP4 vs H200 INT4 on Kimi K2.5/K2.6: Up to 2.95x Better Performance per Dollar

On vLLM 8K/1K the NVFP4 path on B200 is 2.71x–2.95x cheaper per million tokens than H200 INT4 across the entire 30–90 tok/s/user serving band, and 2.45x–2.74x cheaper than B200 INT4 on the same silicon. Both factors decompose cleanly into B200's HBM bandwidth, HBM capacity, and NVFP4 tensor cores

  • benchmark
  • gpu
  • inference
  • +6

13 min read

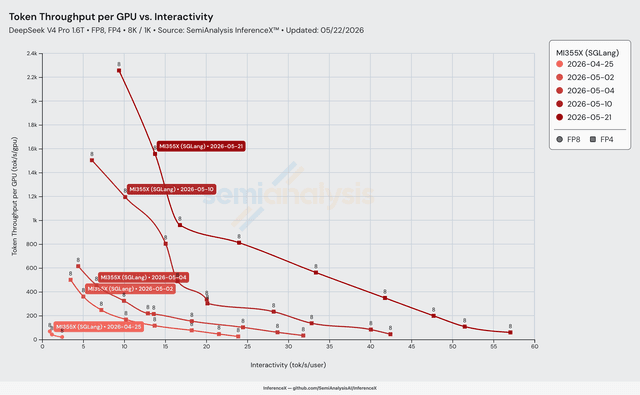
MI355X DeepSeek-V4-Pro on SGLang: 110.5x Throughput per GPU in 26 Days

The amd/deepseek_v4 side branch shipped TileLang attention indexer, Triton sparse MLA, fused RoPE/Hadamard, FlyDSL MoE, and FP4 weights across 31 performance optimizations PRs — lifting first-light 20 tok/s/GPU at 2.4 tok/s/user into 2,256 tok/s/GPU at 9.4 tok/s/user on 8K/1K, with both throughput and interactivity climbing together

  • benchmark
  • gpu
  • inference
  • +6

7 min read

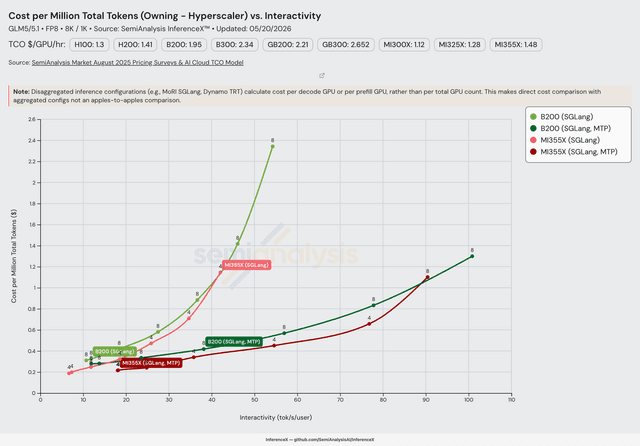
AMD MI355X GLM-5 Inference: Up to 40% Cheaper per Million Tokens than B200 on SGLang FP8

14 weeks after GLM-5 launched, AMD landed both MTP and non-MTP SGLang FP8 recipes on MI355X — fused MLA + FP8 KV cache via TileLang flips the single-node FP8 cost curve in AMD favor across most of the performance Pareto

  • benchmark
  • gpu
  • inference
  • +7

6 min read

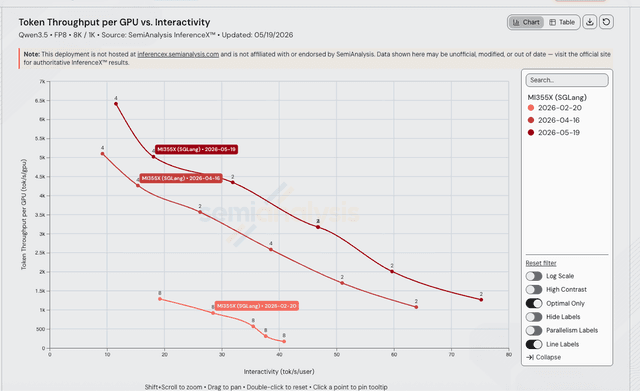
AMD MI355X Qwen3.5 397B-A17B Inference: Up to 19x Throughput per GPU in 3 Months on SGLang FP8

From v0.5.8 (Feb) → v0.5.10rc0 (Apr) → v0.5.12 (May), three AITER kernel landings on MI355X plus a TP=8 → TP=2/TP=4 retune push Qwen3.5 8k/1k peak from 1.3k to 6.4k tok/s/GPU and extend the curve out to 75 tok/s/user

  • benchmark
  • gpu
  • inference
  • +5

8 min read

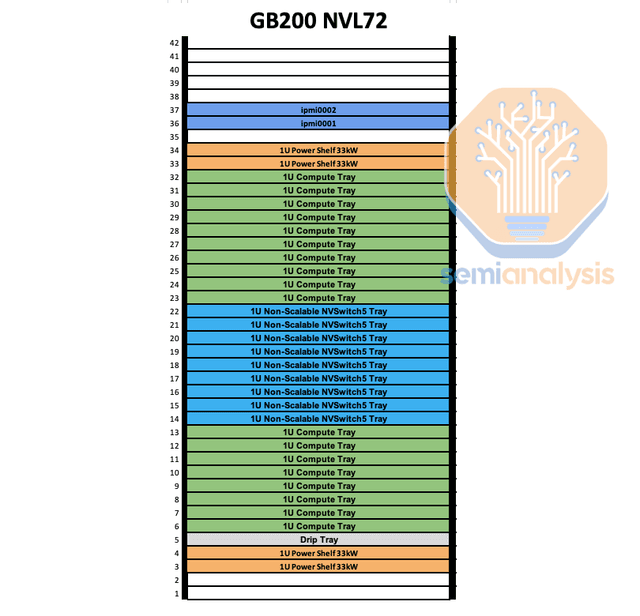
GB200 NVL72 vs B200 on DeepSeek R1 670B: Up to 4.4x Throughput per GPU at 125 tok/s/user

DeepSeek R1 FP4 1k/1k. NVL72's 72-GPU NVLink scale-up fabric lets decode run wide EP up to EP=32, where B200's 8-GPU NVLink island caps out at EP=8 over RoCEv2

  • benchmark
  • gpu
  • inference
  • +9

5 min read

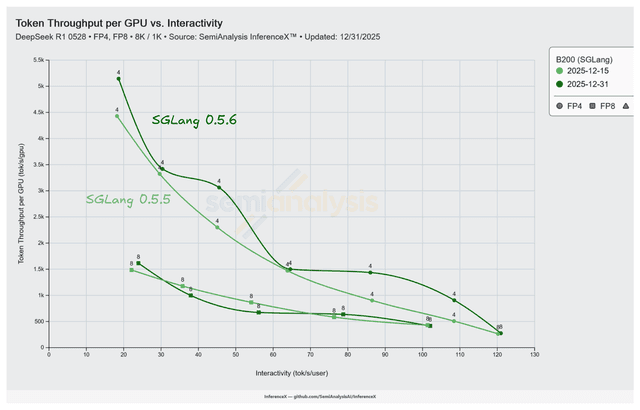
SGLang 0.5.6 on B200 DeepSeek R1 FP4: Up to 1.8x at Low Concurrency

Piecewise CUDA graphs for DeepSeek V3, a unified event loop, and JIT kernels push 8k/1k throughput from 508 to 907 tok/s/GPU on the same 16 GPU B200 pool

  • benchmark
  • inference
  • gpu
  • +5

6 min read

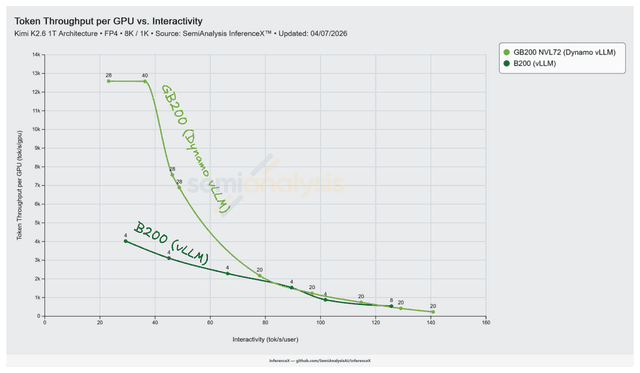
GB200 NVL72 vs B200 on Kimi K2.5: 3.1x from Wide EP vLLM

Rack scale NVLink on NVL72 lets Dynamo vLLM run Kimi K2.5 wide EP up to Decode EP 16, taking peak throughput from 4,021 to 12,587 tok/s/GPU on 8k/1k NVFP4

  • benchmark
  • gpu
  • inference
  • +7

6 min read

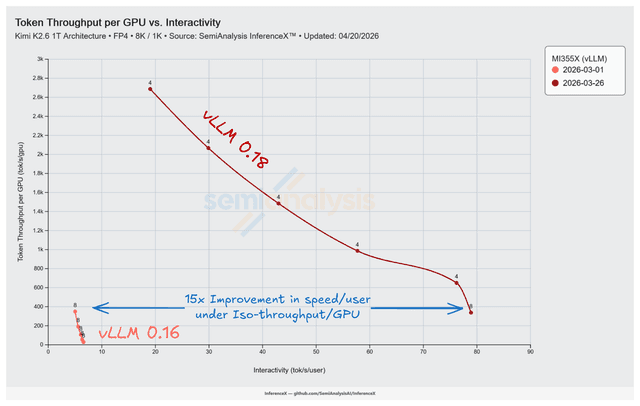
AMD MI355X Kimi K2.5 Inference: 7.7x Throughput, Up To 15x Interactivity in 25 Days on vLLM

vLLM PR #35850 Fixed AITER MLA Dispatch on MI355X CDNA4, Unlocking Kimi K2.5 Inference Performance at TP=8, Shipped in vLLM 0.18

  • benchmark
  • gpu
  • inference
  • +5

37 min read

InferenceMAX: Open Source Inference Benchmarking

NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Cost per Million Tokens, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B

  • benchmark
  • gpu
  • inference
  • +1