2 min read
DeepSeek V4 Pro on AgentX: GB200 vs GB300 Rack-Scale Disaggregation
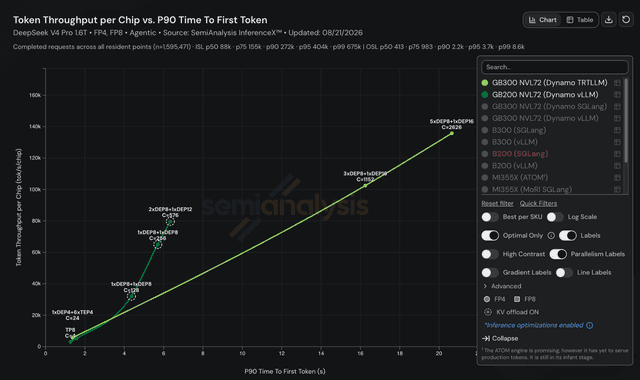
Both lean on PD disagg, GB300 adds DEP32 wide-EP decode, and the gap shows up in first-token latency rather than token rate
- agentx
- agentic
- benchmark
- +8
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
7 articles
2 min read
Both lean on PD disagg, GB300 adds DEP32 wide-EP decode, and the gap shows up in first-token latency rather than token rate
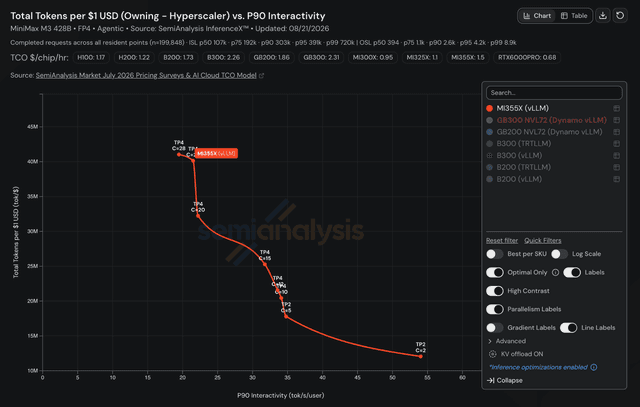
3 min read
The Dynamo router becomes the bottleneck, no submission runs context parallelism, and AMD leaves KV offload on the table
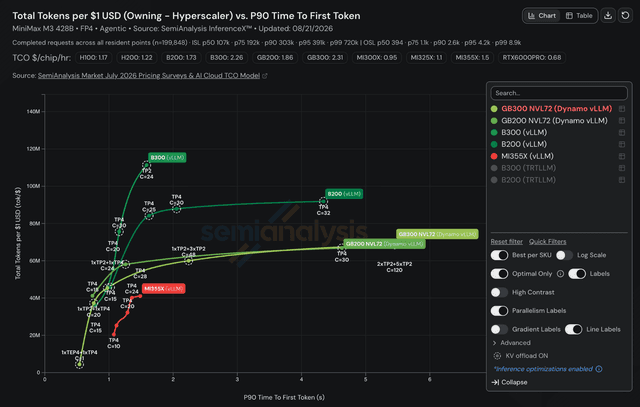
2 min read
NVIDIA sweeps the 432B model, and the missing DP-attention points explain why cache locality became a routing constraint
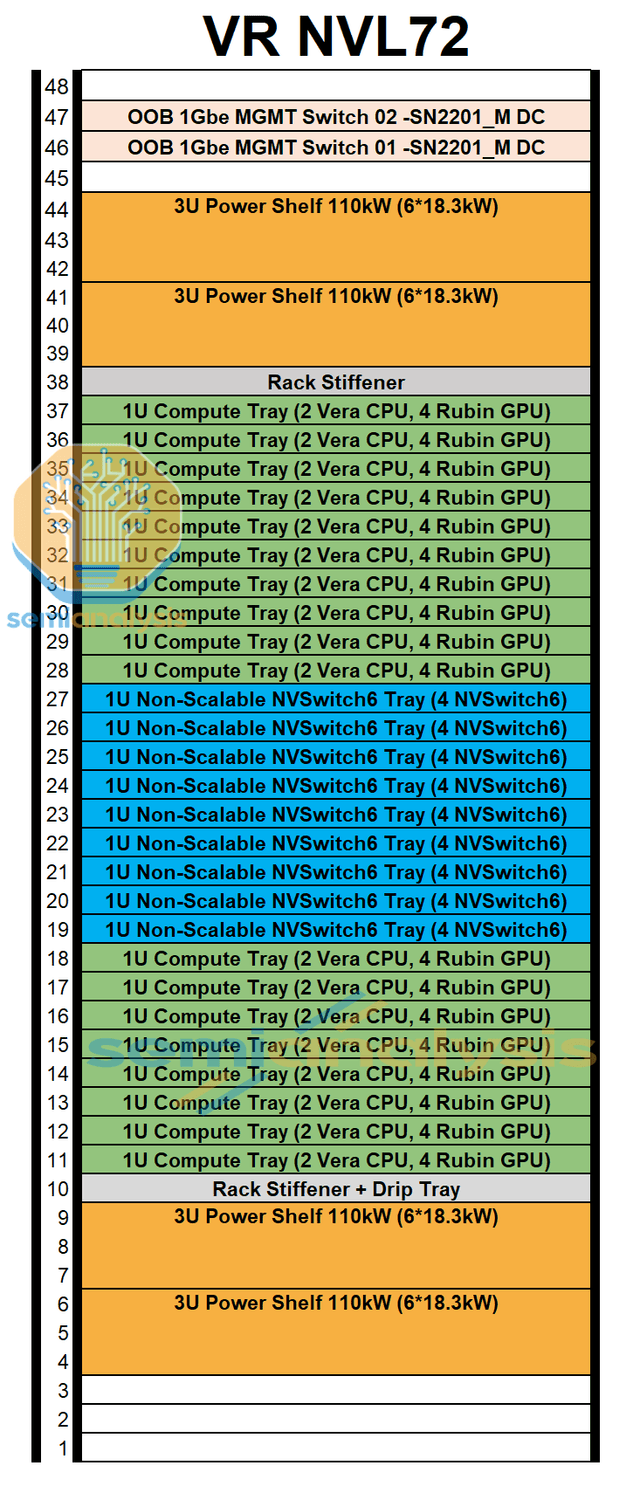
20 min read
Rubin LUT Based Tensor Core, Feynman, Rack Scale, Perf Per MegaWatt, Perf Per Dollar, Software Improvements, Public Rubin Software, PyTorch, vLLM, OpenAI Triton

10 min read
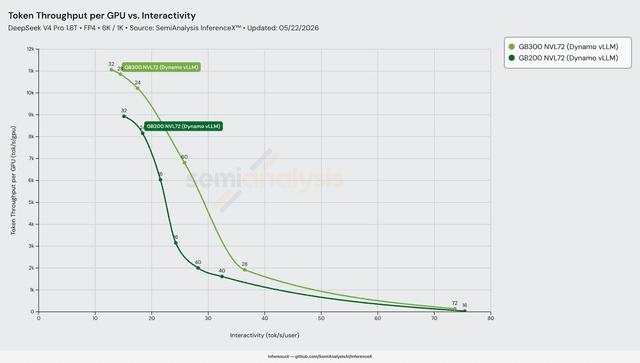
DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

8 min read
DeepSeek R1 FP4 1k/1k. NVL72's 72-GPU NVLink scale-up fabric lets decode run wide EP up to EP=32, where B200's 8-GPU NVLink island caps out at EP=8 over RoCEv2

6 min read
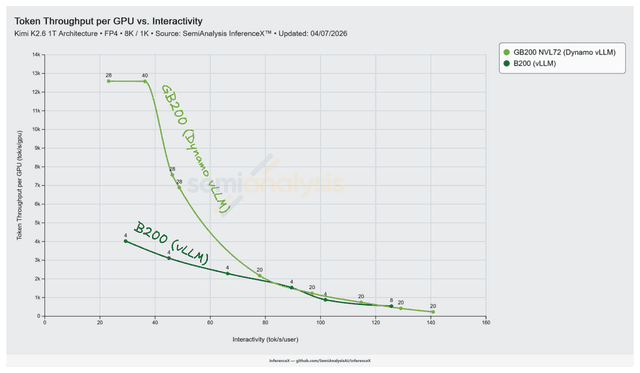
Rack scale NVLink on NVL72 lets Dynamo vLLM run Kimi K2.5 wide EP up to Decode EP 16, taking peak throughput from 4,021 to 12,587 tok/s/GPU on 8k/1k NVFP4