8 min read
Engrams Embedding Entendre: Codesign for Efficient DRAM/SSD Offloading
New Model Architecture Implications for TAM of DRAM/NVMe, DeepSeek V4.1 Flash, AgentX, InferenceX, NVMe experiments
- inference
- agentx
- deepseek
- +3
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
34 articles
8 min read
New Model Architecture Implications for TAM of DRAM/NVMe, DeepSeek V4.1 Flash, AgentX, InferenceX, NVMe experiments
10 min read
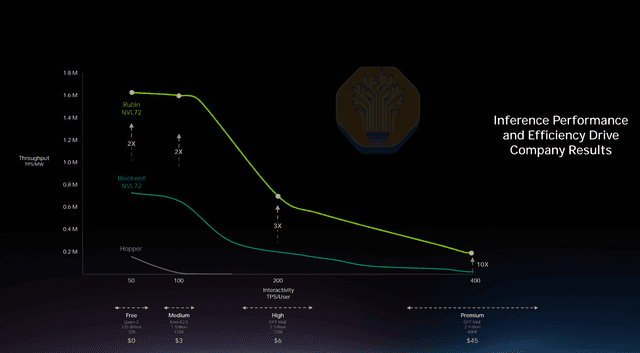
Jensen Sandbagging Performance Again, 2x more Annual Profit Per GigaWatt, The More you Buy, The More you Earn, AgentX, InferenceX, Extreme Co-Design
35 min read
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
3 min read
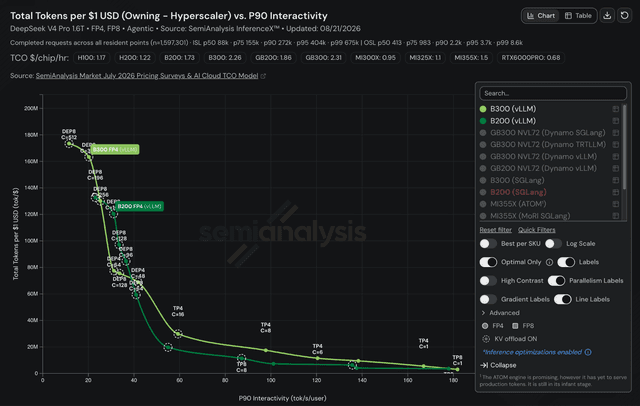
50% more HBM squeezes out extra throughput, and the per-point telemetry shows exactly where it comes from
2 min read
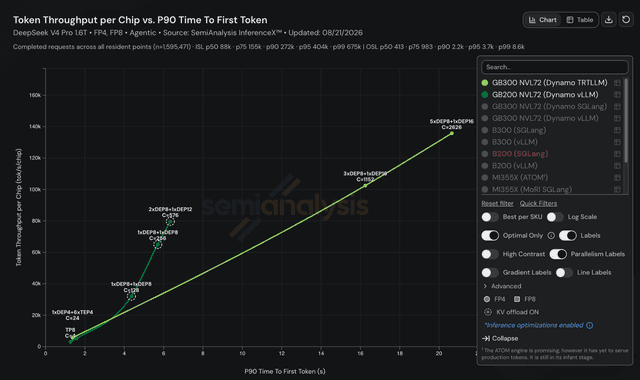
Both lean on PD disagg, GB300 adds DEP32 wide-EP decode, and the gap shows up in first-token latency rather than token rate
3 min read
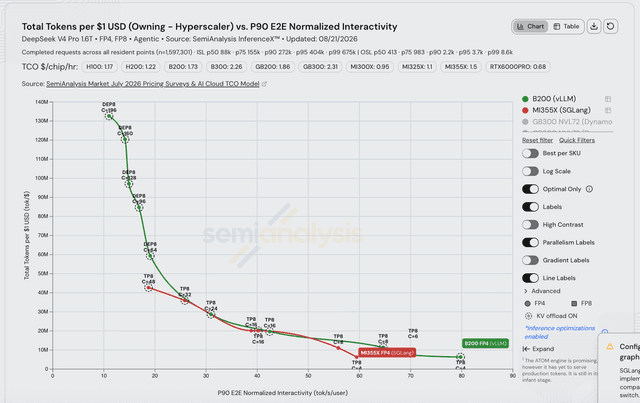
AMD matched B200 vLLM on performance per dollar for end-to-end latency, then upstream vLLM work moved the line
2 min read
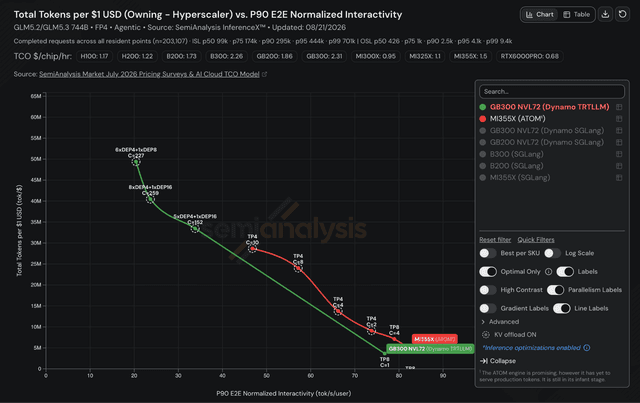
Where AMD’s vendor engine wins on performance per dollar, and what E2E Normalized Interactivity actually measures
2 min read
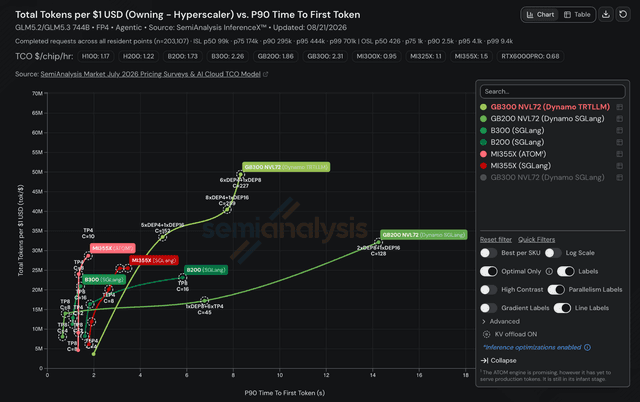
At this operating point, free AMD silicon would still not close the gap
2 min read
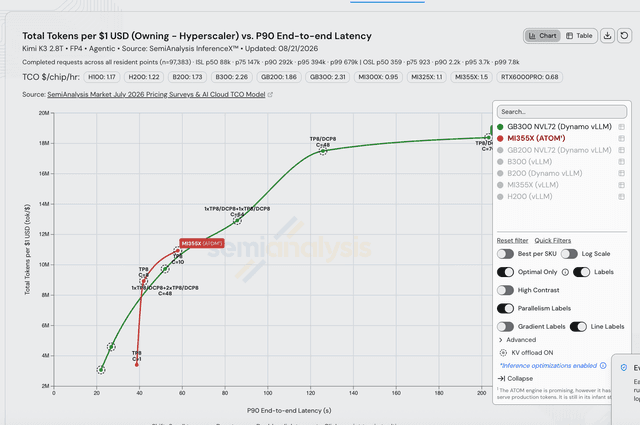
AMD’s vendor engine wins a real slice of the performance per dollar frontier, while Hopper struggles to serve K3 at all
3 min read
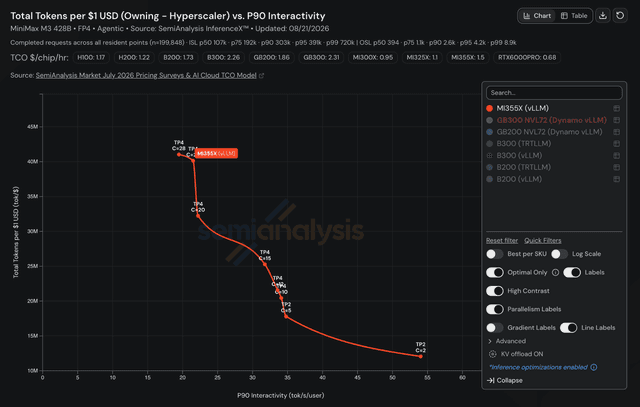
The Dynamo router becomes the bottleneck, no submission runs context parallelism, and AMD leaves KV offload on the table
2 min read
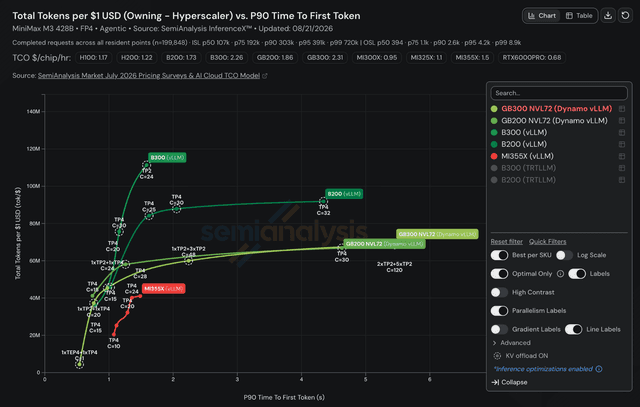
NVIDIA sweeps the 432B model, and the missing DP-attention points explain why cache locality became a routing constraint
23 min read
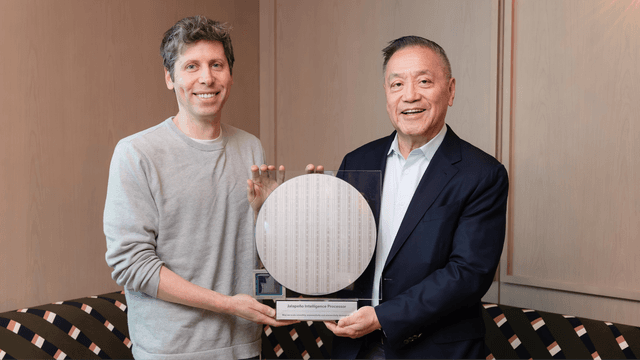
OpenAI’s self-designed ASIC compared with Rubin, Jalapeño’s TCO, throughput per MW, and spicy deets
2 min read
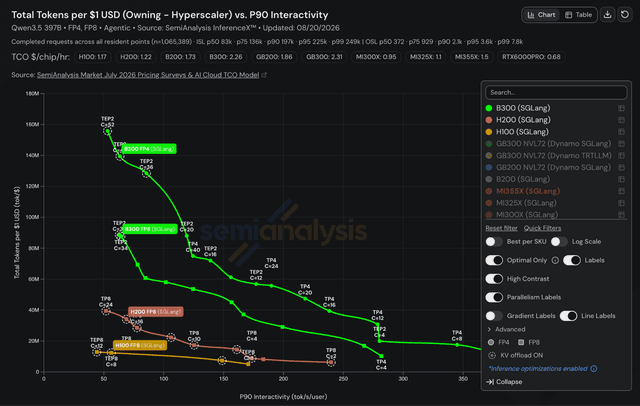
What four years of hardware and a 4-bit format buy on a long-context agentic workload
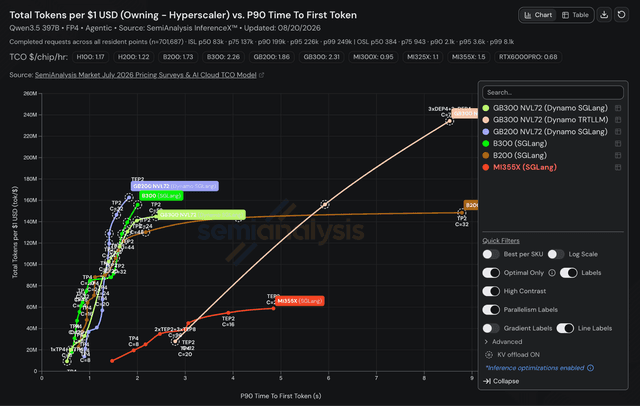
2 min read
GatedDeltaNet, a 262k native context, and no AMD competition at all on the same engine
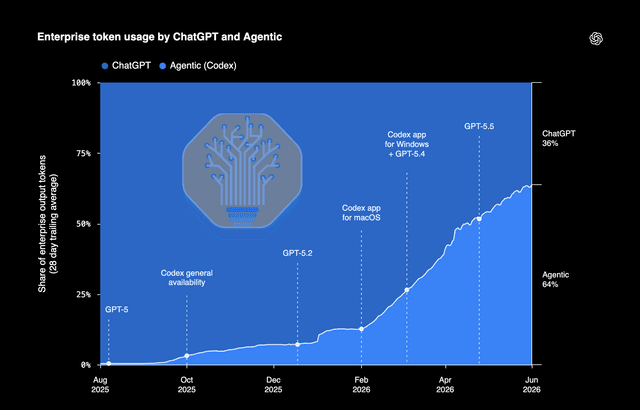
64 min read
$3 Million USD dataset open sourced, 1 Mil+ Context Length, Multiturn, Sub Agents 95%+ KVCache HitRate, GB300 NVL72, MI355X, B200
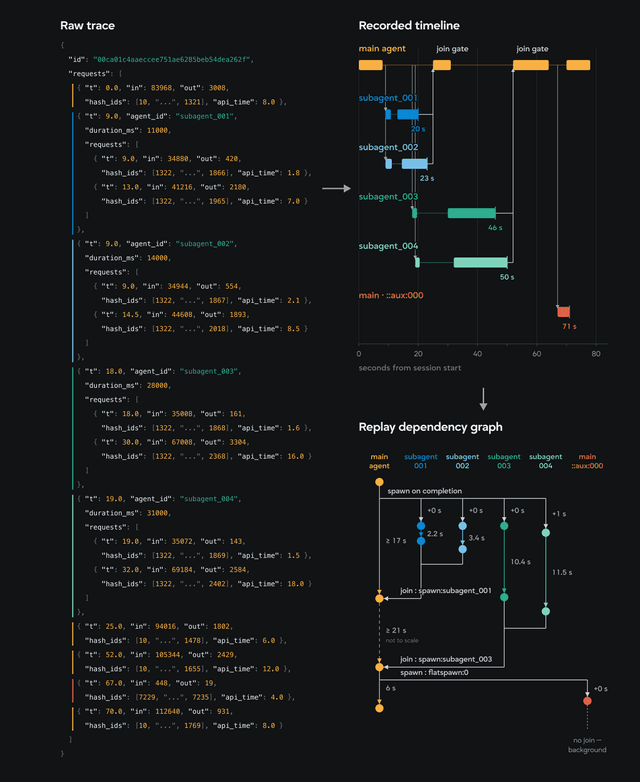
10 min read
How an agent benchmark replays long-context, multi-turn workloads to measure latency, throughput, cache behavior, and serving cost
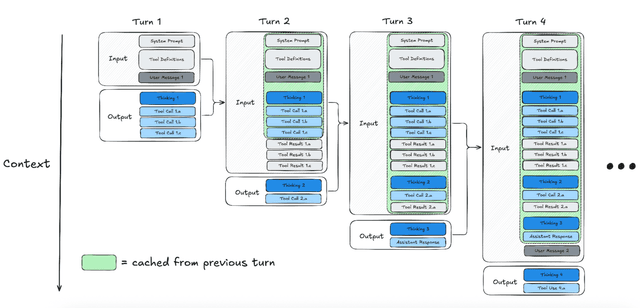
6 min read
Multi-turn sessions, long contexts, and near-total prefix reuse make agentic inference a systems problem, and change what a benchmark has to measure
17 min read
Can TileRT software on NVIDIA GPUs compete with Cerebras, Groq LPU, and SambaNova? Batch size 1, disaggregated engine, high-throughput prefill engine, high-interactivity decode engine
23 min read
Kimi K3's architecture: compressed memory, attention across depth, latent expert routing, and serving performance
20 min read
Rubin LUT Based Tensor Core, Feynman, Rack Scale, Perf Per MegaWatt, Perf Per Dollar, Software Improvements, Public Rubin Software, PyTorch, vLLM, OpenAI Triton
29 min read
Day 0 Inference Performance, InferenceX, 100x performance improvement in 26 Days, Cost per Million Tokens, Huawei 950DT Inference Trace Analysis

10 min read
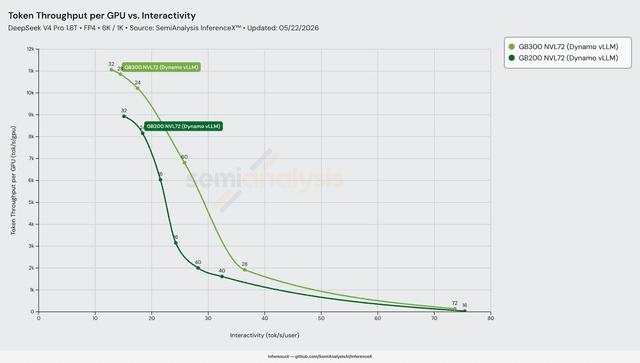
DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

10 min read
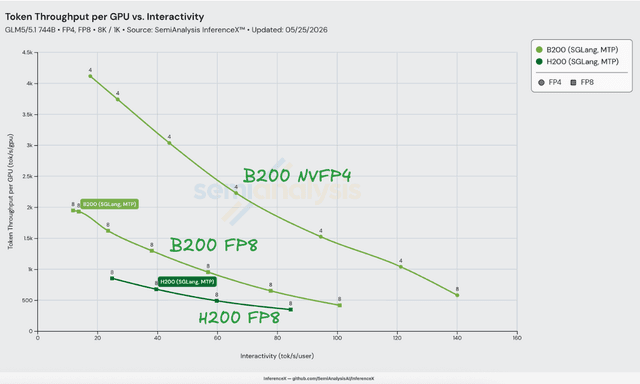
Both SKUs run SGLang EAGLE MTP; the Blackwell generation lifts perf/$ by ~1.2x at the peak and the NVIDIA GLM-5-NVFP4 checkpoint on FlashInfer TRT-LLM sparse MLA stacks another ~2.4–3.0x on 8K/1K

12 min read
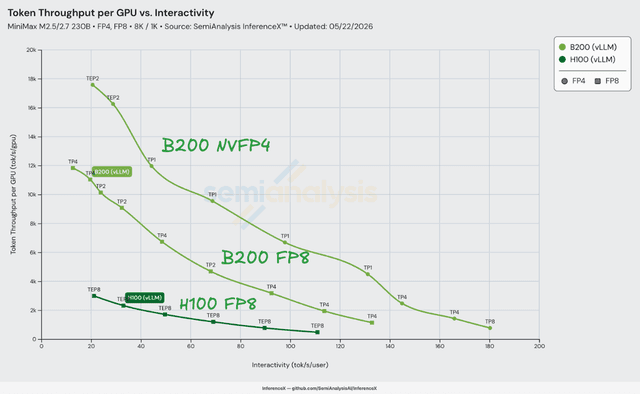
vLLM PR #36307 unlocks the trtllm-gen FP8 MoE kernel for MiniMax on B200; combined with NVFP4, perf/$ scales from 4.0x at 22 tok/s/user to 8.2x at 110 on 8K/1K

11 min read
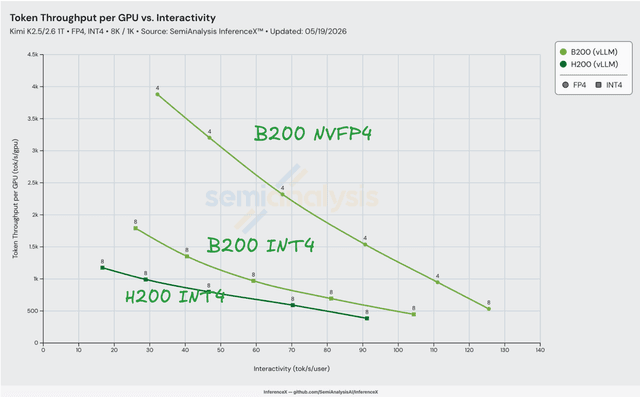
On vLLM 8K/1K the NVFP4 path on B200 is 2.71x–2.95x cheaper per million tokens than H200 INT4 across the entire 30–90 tok/s/user serving band, and 2.45x–2.74x cheaper than B200 INT4 on the same silicon. Both factors decompose cleanly into B200's HBM bandwidth, HBM capacity, and NVFP4 tensor cores

13 min read
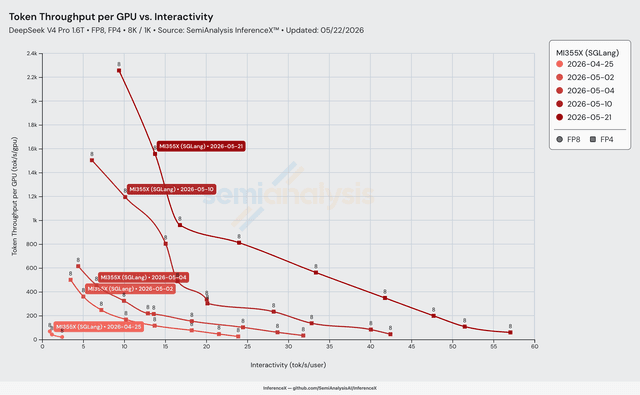
The amd/deepseek_v4 side branch shipped TileLang attention indexer, Triton sparse MLA, fused RoPE/Hadamard, FlyDSL MoE, and FP4 weights across 31 performance optimizations PRs — lifting first-light 20 tok/s/GPU at 2.4 tok/s/user into 2,256 tok/s/GPU at 9.4 tok/s/user on 8K/1K, with both throughput and interactivity climbing together

7 min read
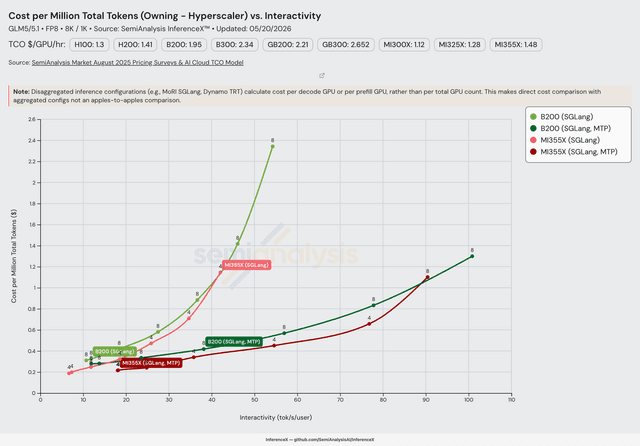
14 weeks after GLM-5 launched, AMD landed both MTP and non-MTP SGLang FP8 recipes on MI355X — fused MLA + FP8 KV cache via TileLang flips the single-node FP8 cost curve in AMD favor across most of the performance Pareto

6 min read
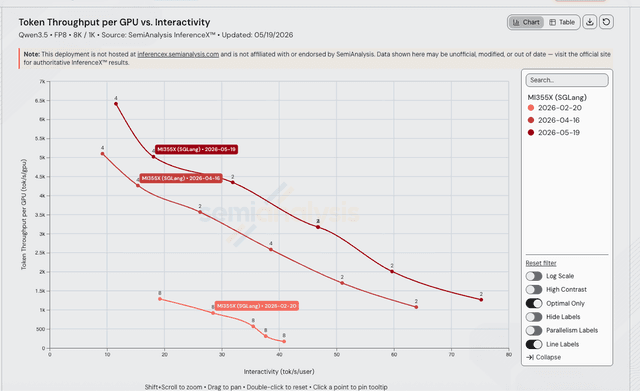
From v0.5.8 (Feb) → v0.5.10rc0 (Apr) → v0.5.12 (May), three AITER kernel landings on MI355X plus a TP=8 → TP=2/TP=4 retune push Qwen3.5 8k/1k peak from 1.3k to 6.4k tok/s/GPU and extend the curve out to 75 tok/s/user

8 min read
DeepSeek R1 FP4 1k/1k. NVL72's 72-GPU NVLink scale-up fabric lets decode run wide EP up to EP=32, where B200's 8-GPU NVLink island caps out at EP=8 over RoCEv2

5 min read
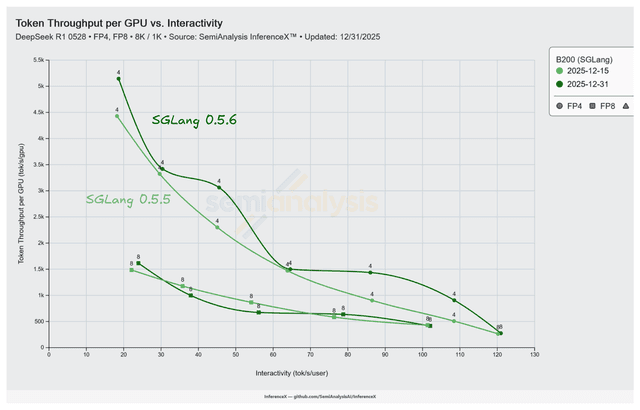
Piecewise CUDA graphs for DeepSeek V3, a unified event loop, and JIT kernels push 8k/1k throughput from 508 to 907 tok/s/GPU on the same 16 GPU B200 pool

6 min read
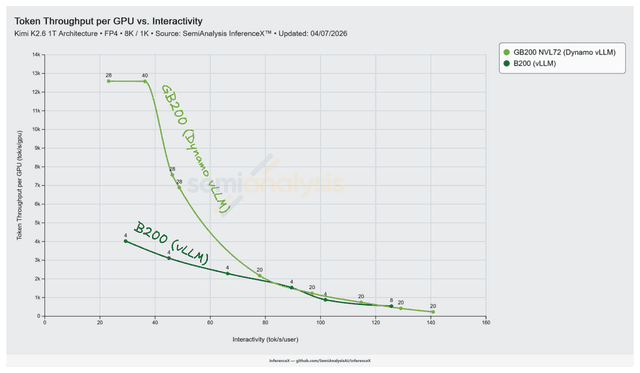
Rack scale NVLink on NVL72 lets Dynamo vLLM run Kimi K2.5 wide EP up to Decode EP 16, taking peak throughput from 4,021 to 12,587 tok/s/GPU on 8k/1k NVFP4

6 min read
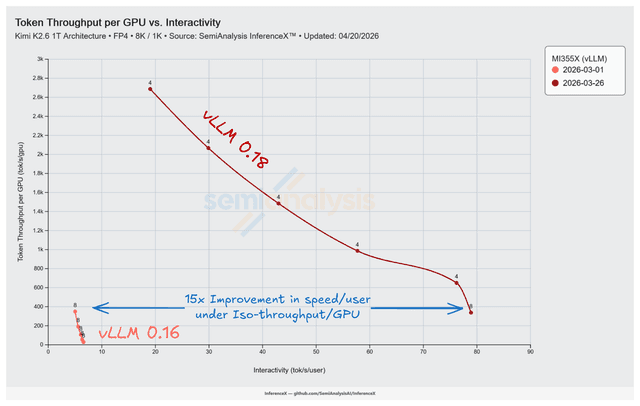
vLLM PR #35850 Fixed AITER MLA Dispatch on MI355X CDNA4, Unlocking Kimi K2.5 Inference Performance at TP=8, Shipped in vLLM 0.18
47 min read
GB300 NVL72, MI355X, B200, H100, Disaggregated Serving, Wide Expert Parallelism, Large Mixture of Experts, SGLang, vLLM, TRTLLM
37 min read
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Cost per Million Tokens, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B