InferenceX Research

Articles

Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.

New to the terminology? Browse the AI inference glossary.

10 min read

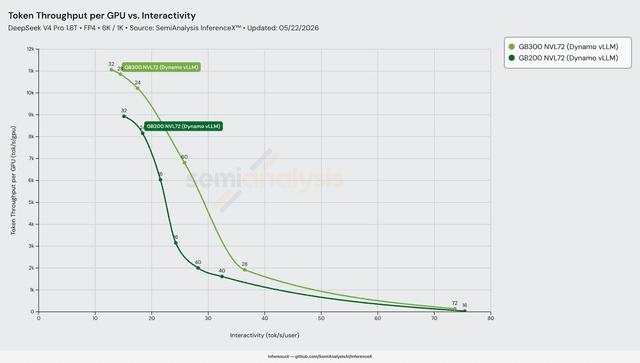
GB300 NVL72 vs GB200 NVL72 Inference Performance & Perf per Dollar - on DeepSeek-V4-Pro 1.6T: Up to 2.83x Throughput

DSv4-Pro FP4 8K/1K, Dynamo+vLLM, disaggregated on both racks. GB300's 50% extra HBM (288 vs 192 GB/GPU) unlocks a wider prefill+decode recipe GB200 can't fit — lifting middle-of-curve perf/$ by 2.31x despite a 20% per-GPU TCO premium.

  • benchmark
  • gpu
  • inference
  • +9

8 min read

GB200 NVL72 vs B200 on DeepSeek R1 670B: Up to 4.4x Throughput per GPU at 125 tok/s/user

DeepSeek R1 FP4 1k/1k. NVL72's 72-GPU NVLink scale-up fabric lets decode run wide EP up to EP=32, where B200's 8-GPU NVLink island caps out at EP=8 over RoCEv2

  • benchmark
  • gpu
  • inference
  • +9