3 min read
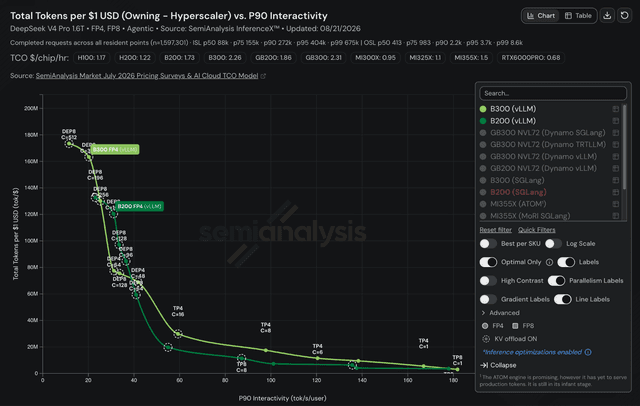
DeepSeek V4 Pro on AgentX: B200 vs B300 and the KV Cache Working Set
50% more HBM squeezes out extra throughput, and the per-point telemetry shows exactly where it comes from
- agentx
- agentic
- benchmark
- +6
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
14 articles
3 min read
50% more HBM squeezes out extra throughput, and the per-point telemetry shows exactly where it comes from
2 min read
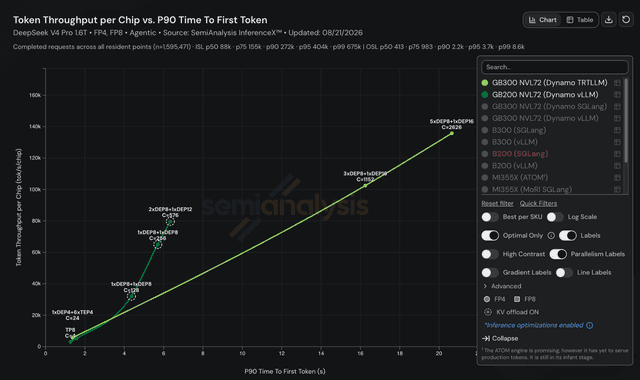
Both lean on PD disagg, GB300 adds DEP32 wide-EP decode, and the gap shows up in first-token latency rather than token rate
3 min read
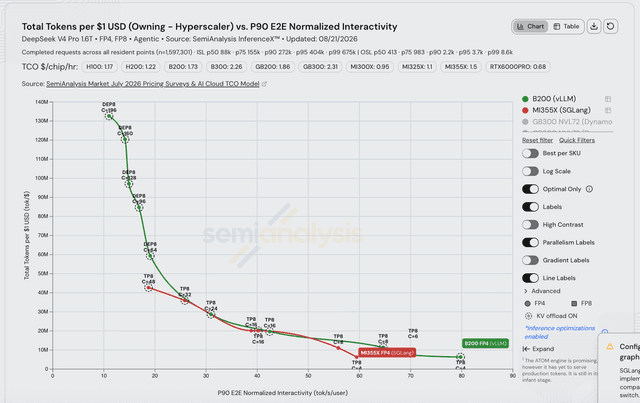
AMD matched B200 vLLM on performance per dollar for end-to-end latency, then upstream vLLM work moved the line
2 min read
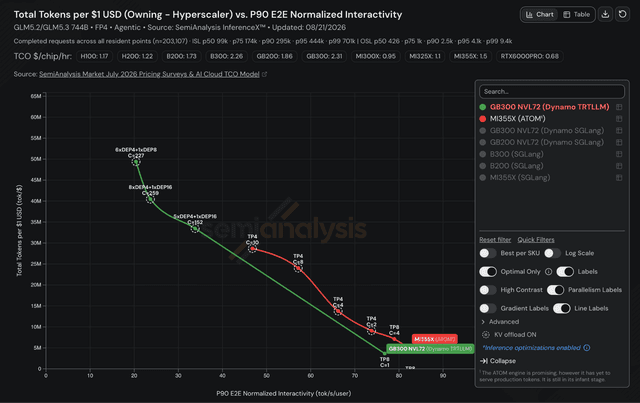
Where AMD’s vendor engine wins on performance per dollar, and what E2E Normalized Interactivity actually measures
2 min read
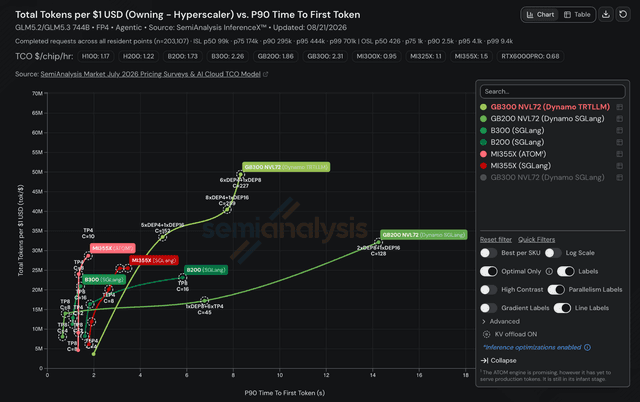
At this operating point, free AMD silicon would still not close the gap
2 min read
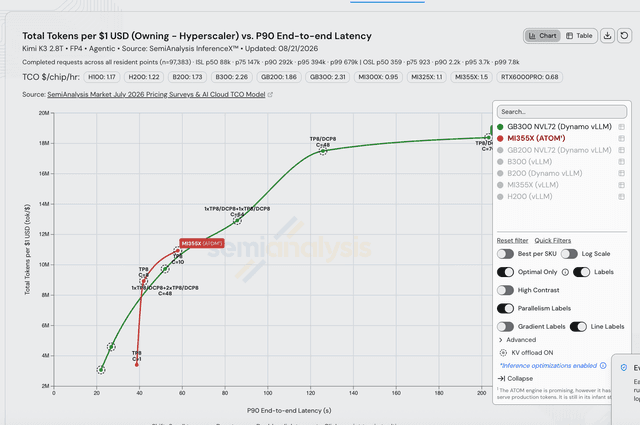
AMD’s vendor engine wins a real slice of the performance per dollar frontier, while Hopper struggles to serve K3 at all
3 min read
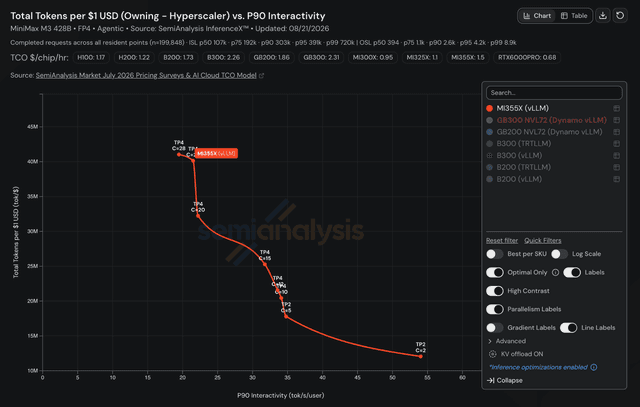
The Dynamo router becomes the bottleneck, no submission runs context parallelism, and AMD leaves KV offload on the table
2 min read
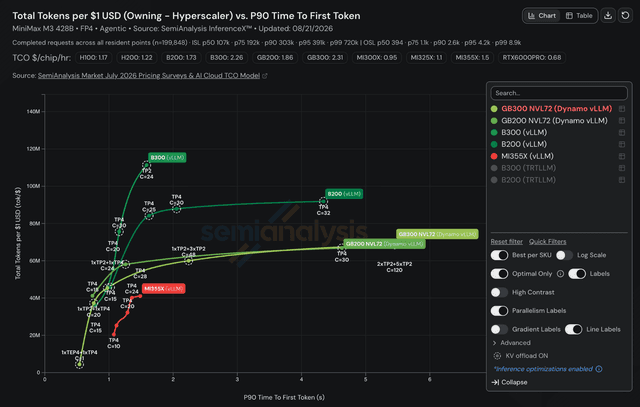
NVIDIA sweeps the 432B model, and the missing DP-attention points explain why cache locality became a routing constraint
2 min read
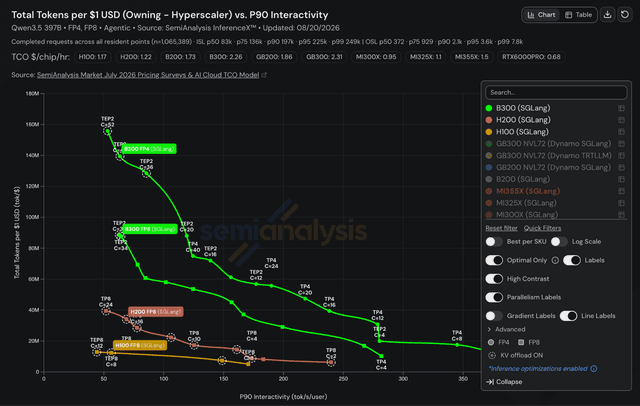
What four years of hardware and a 4-bit format buy on a long-context agentic workload
2 min read
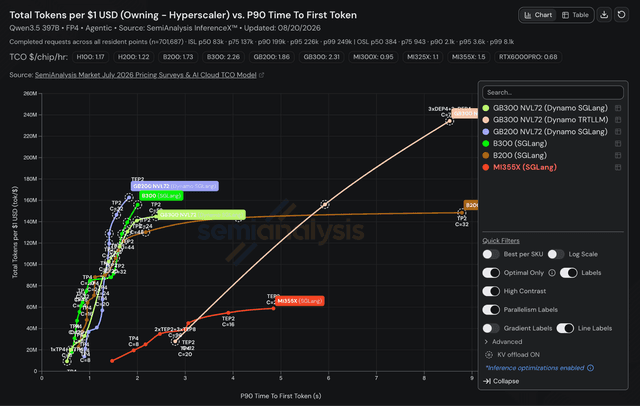
GatedDeltaNet, a 262k native context, and no AMD competition at all on the same engine
64 min read
$3 Million USD dataset open sourced, 1 Mil+ Context Length, Multiturn, Sub Agents 95%+ KVCache HitRate, GB300 NVL72, MI355X, B200
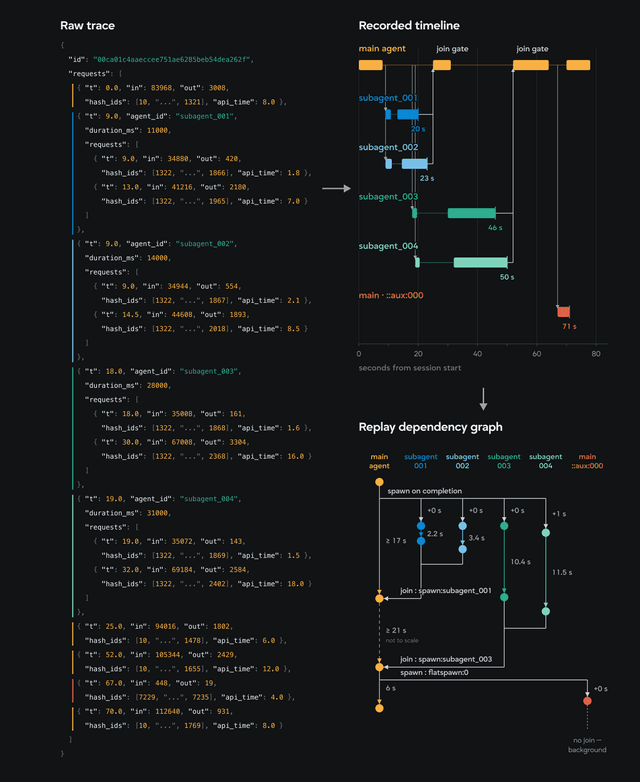
10 min read
How an agent benchmark replays long-context, multi-turn workloads to measure latency, throughput, cache behavior, and serving cost
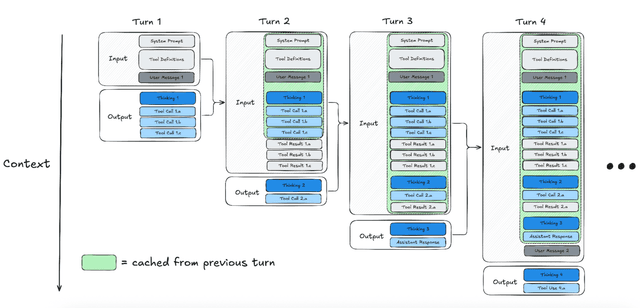
6 min read
Multi-turn sessions, long contexts, and near-total prefix reuse make agentic inference a systems problem, and change what a benchmark has to measure
17 min read
Can TileRT software on NVIDIA GPUs compete with Cerebras, Groq LPU, and SambaNova? Batch size 1, disaggregated engine, high-throughput prefill engine, high-interactivity decode engine