35 min read
TPU Inference Externalization Full Steam Ahead
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
- benchmark
- inference
- tpu
- +7
InferenceX Research
Benchmark write-ups on agentic inference, AgentX results, and chip and serving-stack economics.
New to the terminology? Browse the AI inference glossary.
4 articles
35 min read
InferenceX, Up to 50% Better Performance per Dollar, Rapid Externalization of TPU stack, Growing Customer Base, Ironwood, TPUv8i, Reducing CUDA Moat
2 min read
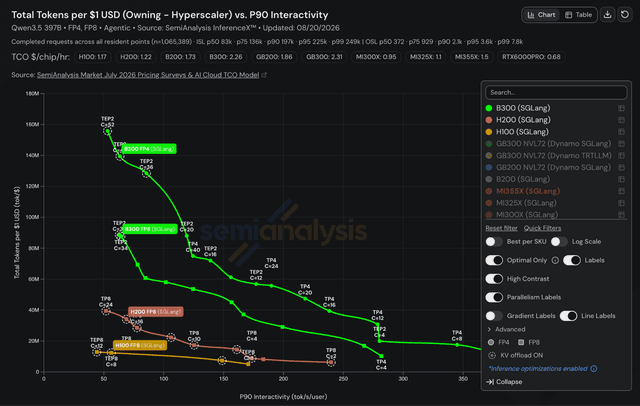
What four years of hardware and a 4-bit format buy on a long-context agentic workload
2 min read
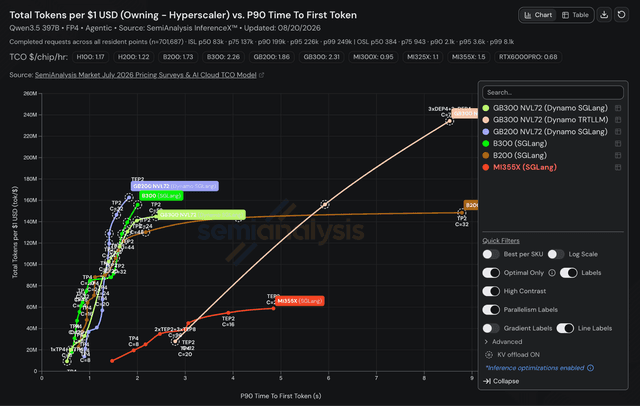
GatedDeltaNet, a 262k native context, and no AMD competition at all on the same engine

6 min read
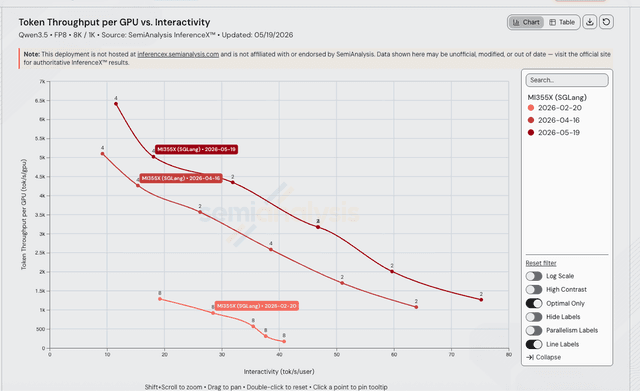
From v0.5.8 (Feb) → v0.5.10rc0 (Apr) → v0.5.12 (May), three AITER kernel landings on MI355X plus a TP=8 → TP=2/TP=4 retune push Qwen3.5 8k/1k peak from 1.3k to 6.4k tok/s/GPU and extend the curve out to 75 tok/s/user