3 min read
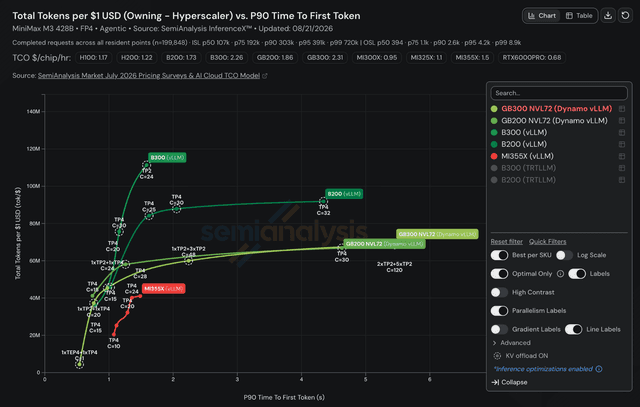
MiniMax M3 on AgentX: Why B200 and B300 Beat Their Rack-Scale GB200 NVL72 & GB300 NVL72 Counterparts
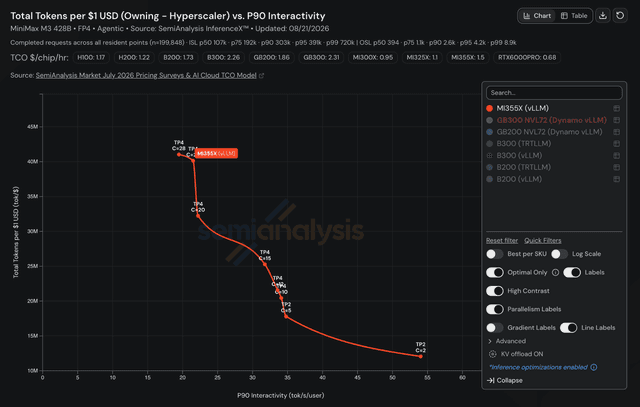
The Dynamo router becomes the bottleneck, no submission runs context parallelism, and AMD leaves KV offload on the table
- agentx
- agentic
- benchmark
- +10