
Whitepaper · Executive Summary
AMD Instinct MI355X Kimi K3 Can Generate Up to $32B of Revenue per GigaWatt per Year
Executive Summary - Agentic Inference Serving Economics Analysis
- AMD
- MI355X
- Kimi K3
- vLLM
- AgentX
- Economics
Key numbers
- Revenue per GW-year
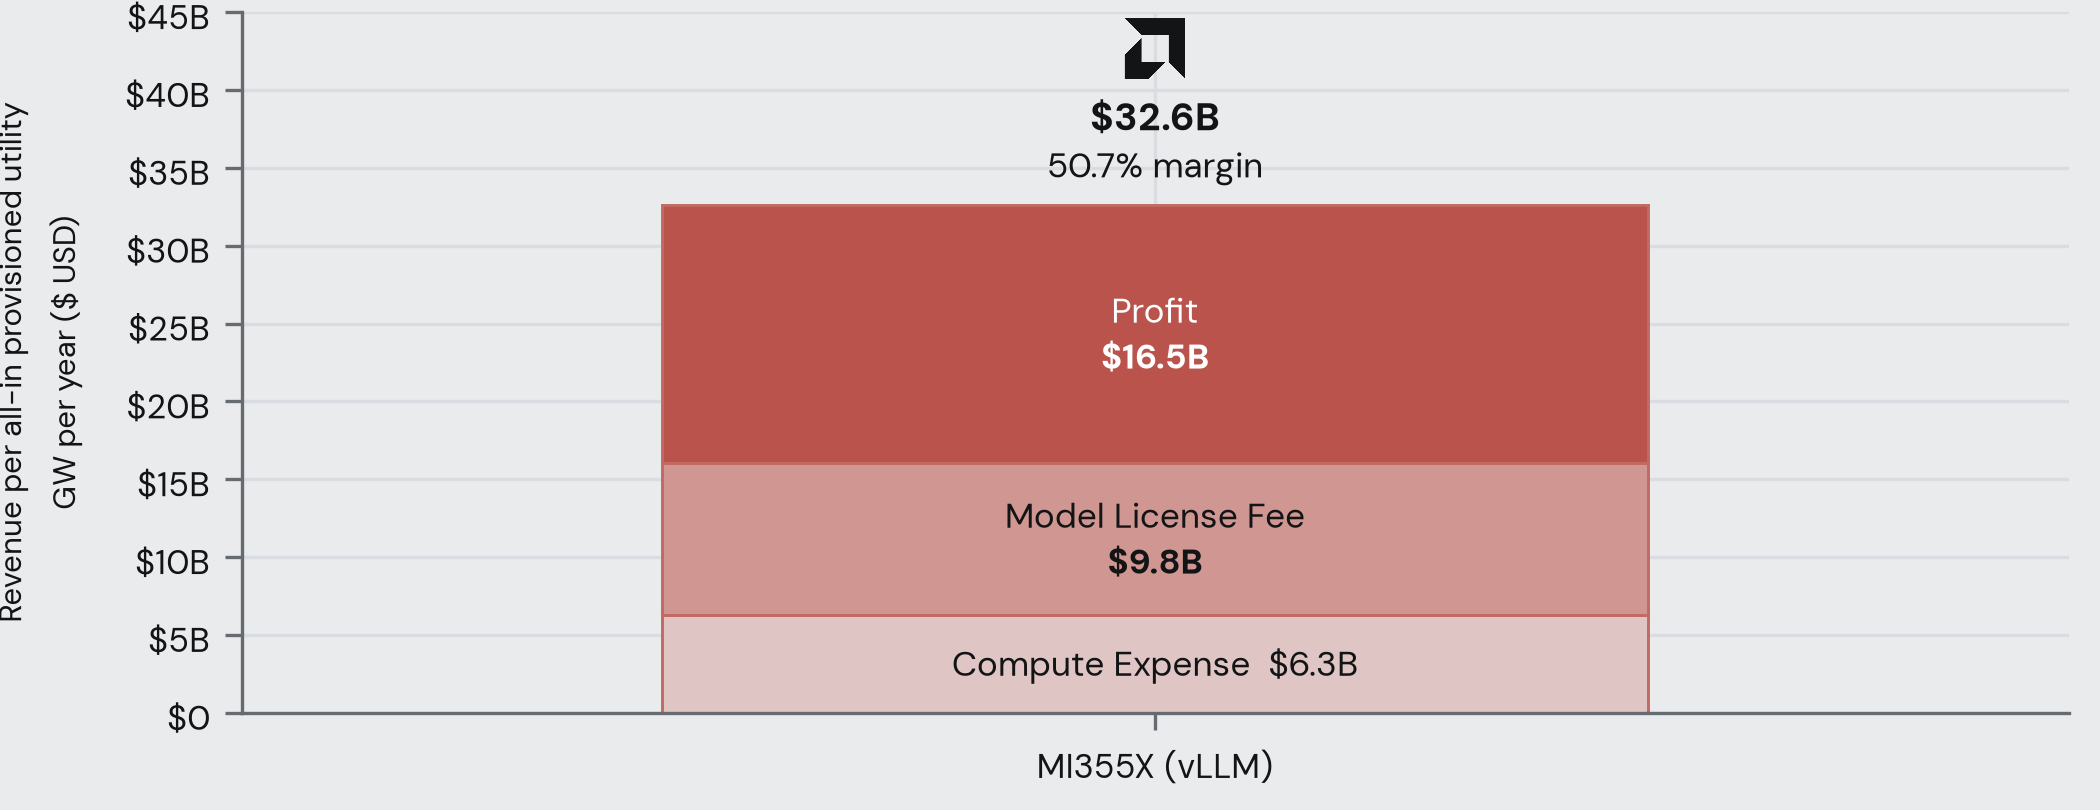
- $32.6B
- Kimi K3 at OpenRouter list price, 60% utilization
- Profit per GW-year
- $16.5B
- Owned at hyperscaler volume at $1.50/GPU/hr compute; $3.95 of profit per chip-hour
- Profit margin
- 50.7%
- After compute expense and 30% model license fee
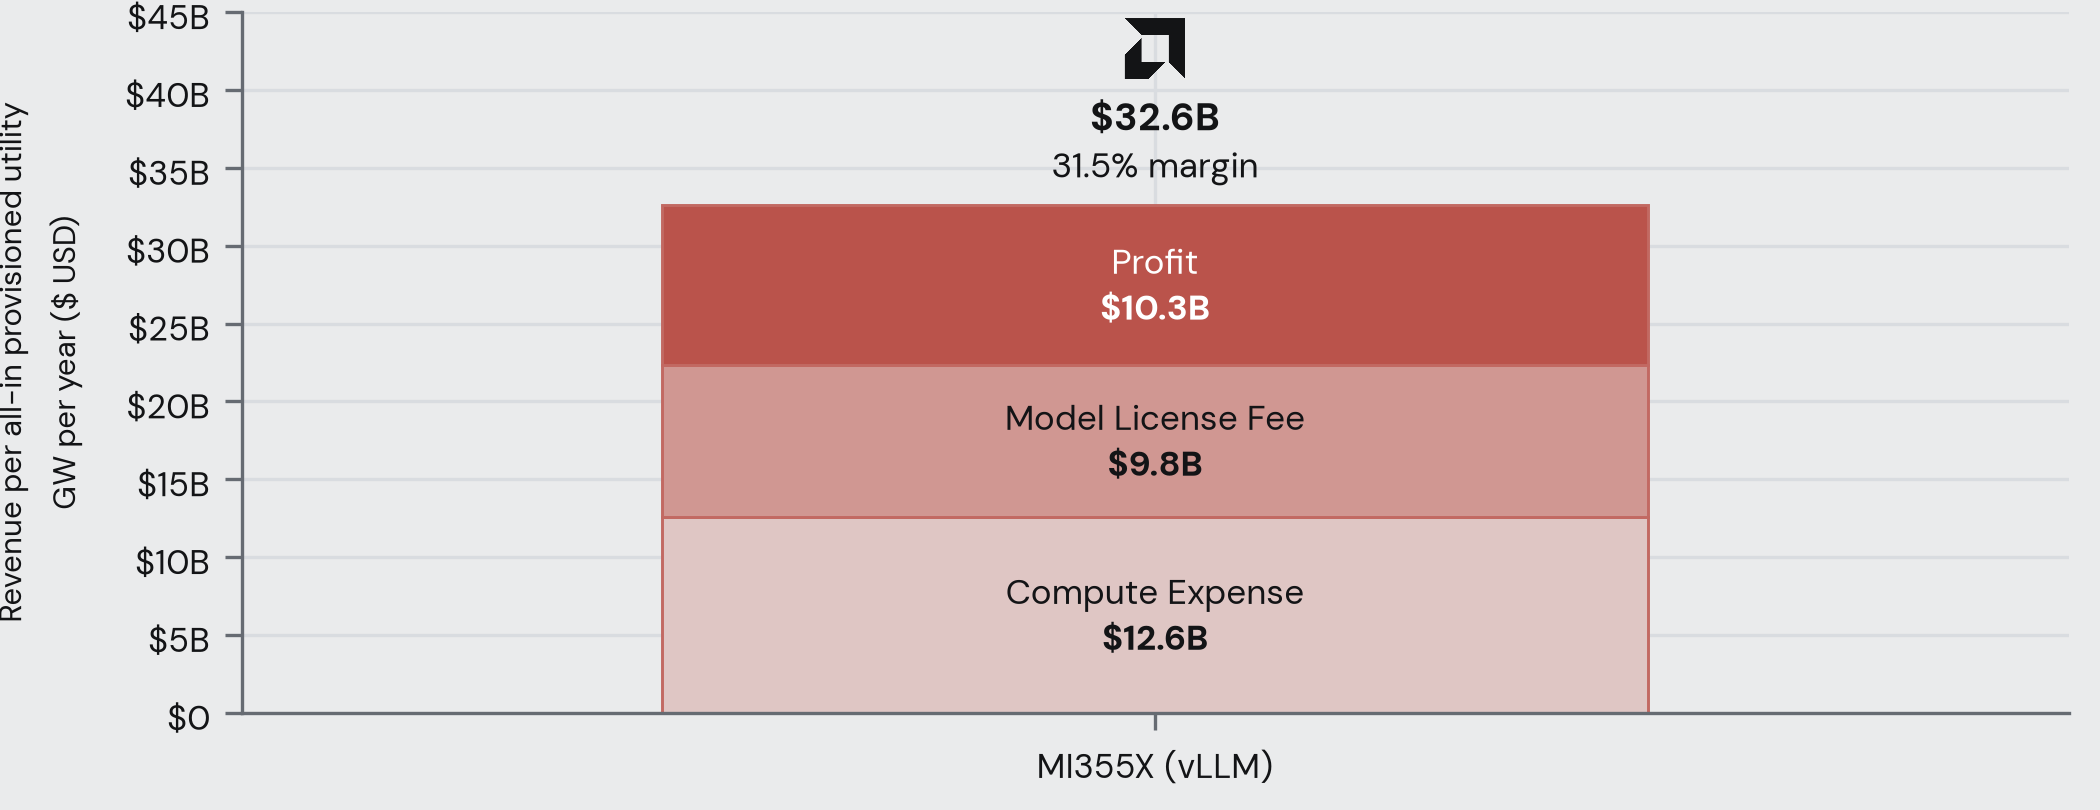
Rented at $3.00/GPU/hr (August 2026 3-year pricing):$10.3B profit31.5% margin$2.45 per chip-hour
Figures
Kimi K3 2.8T Agentic Revenue & Profit Estimates per GigaWatt Per Year at P90 45 tok/s/user Interactivity
 Kimi K3 2.8T Agentic Revenue & Profit Estimates per GigaWatt Per Year at P90 45 tok/s/user Interactivity
- Cost Tier:
- Owning at Large Hyperscaler Volume
- Utilization:
- 60%
- Model License Fee Assumption:
- 30%
- Updated:
- 2026-09-04
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr: MI355X: 1.5
Source: SemiAnalysis Market August 2026 Pricing Surveys & AI Cloud TCO Model
Selling Price per Million Tokens: Input $3 · Cached Input $0.3 · Output $15 (OpenRouter)

Kimi K3 2.8T Agentic Revenue & Profit Estimates per GigaWatt Per Year at P90 45 tok/s/user Interactivity
- Cost Tier:
- Custom $/GPU/hr (August 2026 3-Year Rental Pricing)
- Utilization:
- 60%
- Model License Fee Assumption:
- 30%
- Updated:
- 2026-09-04
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr: MI355X: 3
Source: SemiAnalysis Market August 2026 Pricing Surveys & AI Cloud TCO Model
Selling Price per Million Tokens: Input $3 · Cached Input $0.3 · Output $15 (OpenRouter)

Summary
One utility gigawatt of MI355X capacity running Kimi K3 2.8T on vLLM generates up to $32.6 billion of token revenue per year at the 45 tok/s/user operating point InferenceX uses for agentic workloads. The figure comes from measured AgentX trace replays on an 8-GPU MI355X node (FP4 weights, MTP speculative decoding, TP8), priced at Kimi K3's OpenRouter rates ($3.00 input, $0.30 cached input, $15.00 output per million tokens) and sold at 60% utilization. Two cost profiles bracket the operator's outcome. Owning the fleet at hyperscaler volume costs $1.50 per GPU-hour all-in and leaves $16.5 billion of profit after a 30% model license fee, a 50.7% margin. Renting the same fleet at $3.00 per GPU-hour, the August 2026 price for a 3-year MI355X contract, leaves $10.3 billion, a 31.5% margin.
Key findings
$32.6B of revenue per GW-year. 478,469 MI355X GPUs fit in one all-in utility gigawatt at 2.09 kW per GPU (chip plus its share of node, network, and cooling). Each GPU produces 6,115 tok/s at the P90 45 tok/s/user point, which prices at $12.97 per GPU-hour gross and $7.78 after the 60% utilization haircut.
Compute is the smaller cost. At $1.50/GPU/hr the fleet costs $6.3B per year, less than the $9.8B paid to the model lab as a 30% license fee. Doubling the compute cost to $3.00/GPU/hr adds $6.3B of expense and cuts profit from $16.5B to $10.3B; the operator still keeps 31.5% of revenue.
The 45 tok/s/user point is the middle of the measured curve, not its peak. The MI355X vLLM frontier spans P90 interactivity from 10 to 116 tok/s/user. Loosening the target to 30 tok/s/user raises revenue to $42.8B per GW-year; tightening it to 60 tok/s/user drops revenue to $17.3B and pushes the rental profile to break-even.
Utilization break-even is low. The owned fleet covers compute at 16.5% utilization and the rented fleet at 33.0%. Every 10 points of utilization adds $5.4B of revenue and $3.8B of profit per GW-year under either cost profile.
Prefix caching carries the workload. The agentic traces are 99.2% input tokens and the vLLM server hits its GPU prefix cache 93.7% of the time at this point, so the blended sale price is $0.59 per million tokens even though output tokens list at $15.
Method
GPU-hours per GW-year = 1,000,000 kW / 2.09 kW per GPU x 8,760 h = 4.19 billion GPU-hours.
Revenue = $/GPU/hr gross x GPU-hours x utilization.
Compute expense = cost tier $/GPU/hr x GPU-hours, paid whether or not the fleet is busy.
Model license fee = revenue x 30%.
Profit = revenue - compute expense - license fee.
$/GPU/hr gross = tok/s/GPU x 3,600 x blended $/M tok, where the blended price weights input share (99.2%), cache hit rate (93.7%, cached input billed at $0.30) and output share (0.8%) at the interpolated point.
Interpolation: upper-left Pareto frontier on (P90 interactivity, tok/s/GPU), monotone cubic Hermite spline (Steffen 1990), no extrapolation.
Assumptions
| Item | Value |
|---|---|
| Model | Kimi K3 2.8T (moonshotai/Kimi-K3), FP4 weights |
| Hardware | AMD Instinct MI355X, 8 GPUs, TP8, single node |
| Framework | vLLM, ROCm nightly image vllm/vllm-openai-rocm:nightly-7c5dc571 |
| Speculative decoding | MTP |
| Workload | InferenceX AgentX agentic trace replay |
| Operating point | P90 interactivity 45 tok/s/user |
| Token prices | $3.00 input, $0.30 cached input, $15.00 output per M tokens (OpenRouter, moonshotai/kimi-k3) |
| Utilization | 60% of benchmarked throughput sold |
| Model license fee | 30% of revenue |
| All-in power | 2.09 kW per GPU (SemiAnalysis AI Cloud TCO Model) |
| Cost profile A | $1.50 per GPU-hour, owning at hyperscaler volume (SemiAnalysis AI Cloud TCO Model) |
| Cost profile B | $3.00 per GPU-hour, August 2026 3-year MI355X rental pricing |
| Hours per year | 8,760 |
| Data date | 2026-09-04 |
Sources
- InferenceX profit estimator per gigawatthttps://inferencex.semianalysis.com/profit-estimator-per-gigawatt
- InferenceX AgentX dashboardhttps://inferencex.semianalysis.com/agentx
- OpenRouter Kimi K3 pricinghttps://openrouter.ai/moonshotai/kimi-k3
- SemiAnalysis AI Cloud TCO Modelhttps://semianalysis.com/ai-cloud-tco-model/
Get the full executive summary
The two-page PDF includes both figures, the assumptions table, and source links.