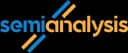
GB200 NVL72 FP8: MTP vs Off Speculative Decoding
Speculative decoding comparison of MTP versus Off on GB200 NVL72 FP8 (NVIDIA Blackwell) running Qwen 3.5 397B-A17B. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
At 87 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72 FP8), MTP delivers 9674 tok/s/chip at $0.05 per million tokens; Off delivers 3576 tok/s/chip at $0.14. MTP is 170% cheaper per token; MTP delivers 170% more tok/s/chip. Speculative decoding accepts draft tokens to reduce per-token latency — gains vary by workload and prompt distribution.
MTP posts 6569 tok/s/chip for $0.08 per million tokens at 129 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72 FP8); Off posts 1882 tok/s/chip for $0.27. MTP is 249% cheaper per token; MTP delivers 249% more tok/s/chip. Draft-token acceptance rates determine whether speculative decoding helps or hurts at a given concurrency level.
Throughput at 171 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72 FP8): MTP hits 3525 tok/s/chip, Off hits 957. Per-million costs land at $0.15 and $0.54 respectively. MTP is 268% cheaper per token; MTP delivers 268% more tok/s/chip. Speculative decoding trades extra compute on draft tokens for fewer decoding steps — the payoff depends on sequence length and batch size. (Numbers reflect this URL's pinned 8k/1k · fp8 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP:9673.9Off:3576.3 | MTP:6569.0Off:1882.3 | MTP:3524.6Off:957.5 |
| Cost ($/M tok) | MTP:$0.053Off:$0.144 | MTP:$0.079Off:$0.274 | MTP:$0.147Off:$0.540 |
| tok/s/MW | MTP:5173206Off:1912467 | MTP:3512833Off:1006594 | MTP:1884826Off:512024 |
| Concurrency | MTP:~1079Off:~40 | MTP:~339Off:~14 | MTP:~48Off:~5 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.