
Qwen 3.8 Flash Next 176B-A6B — B200 vs B300 Performance per Dollar
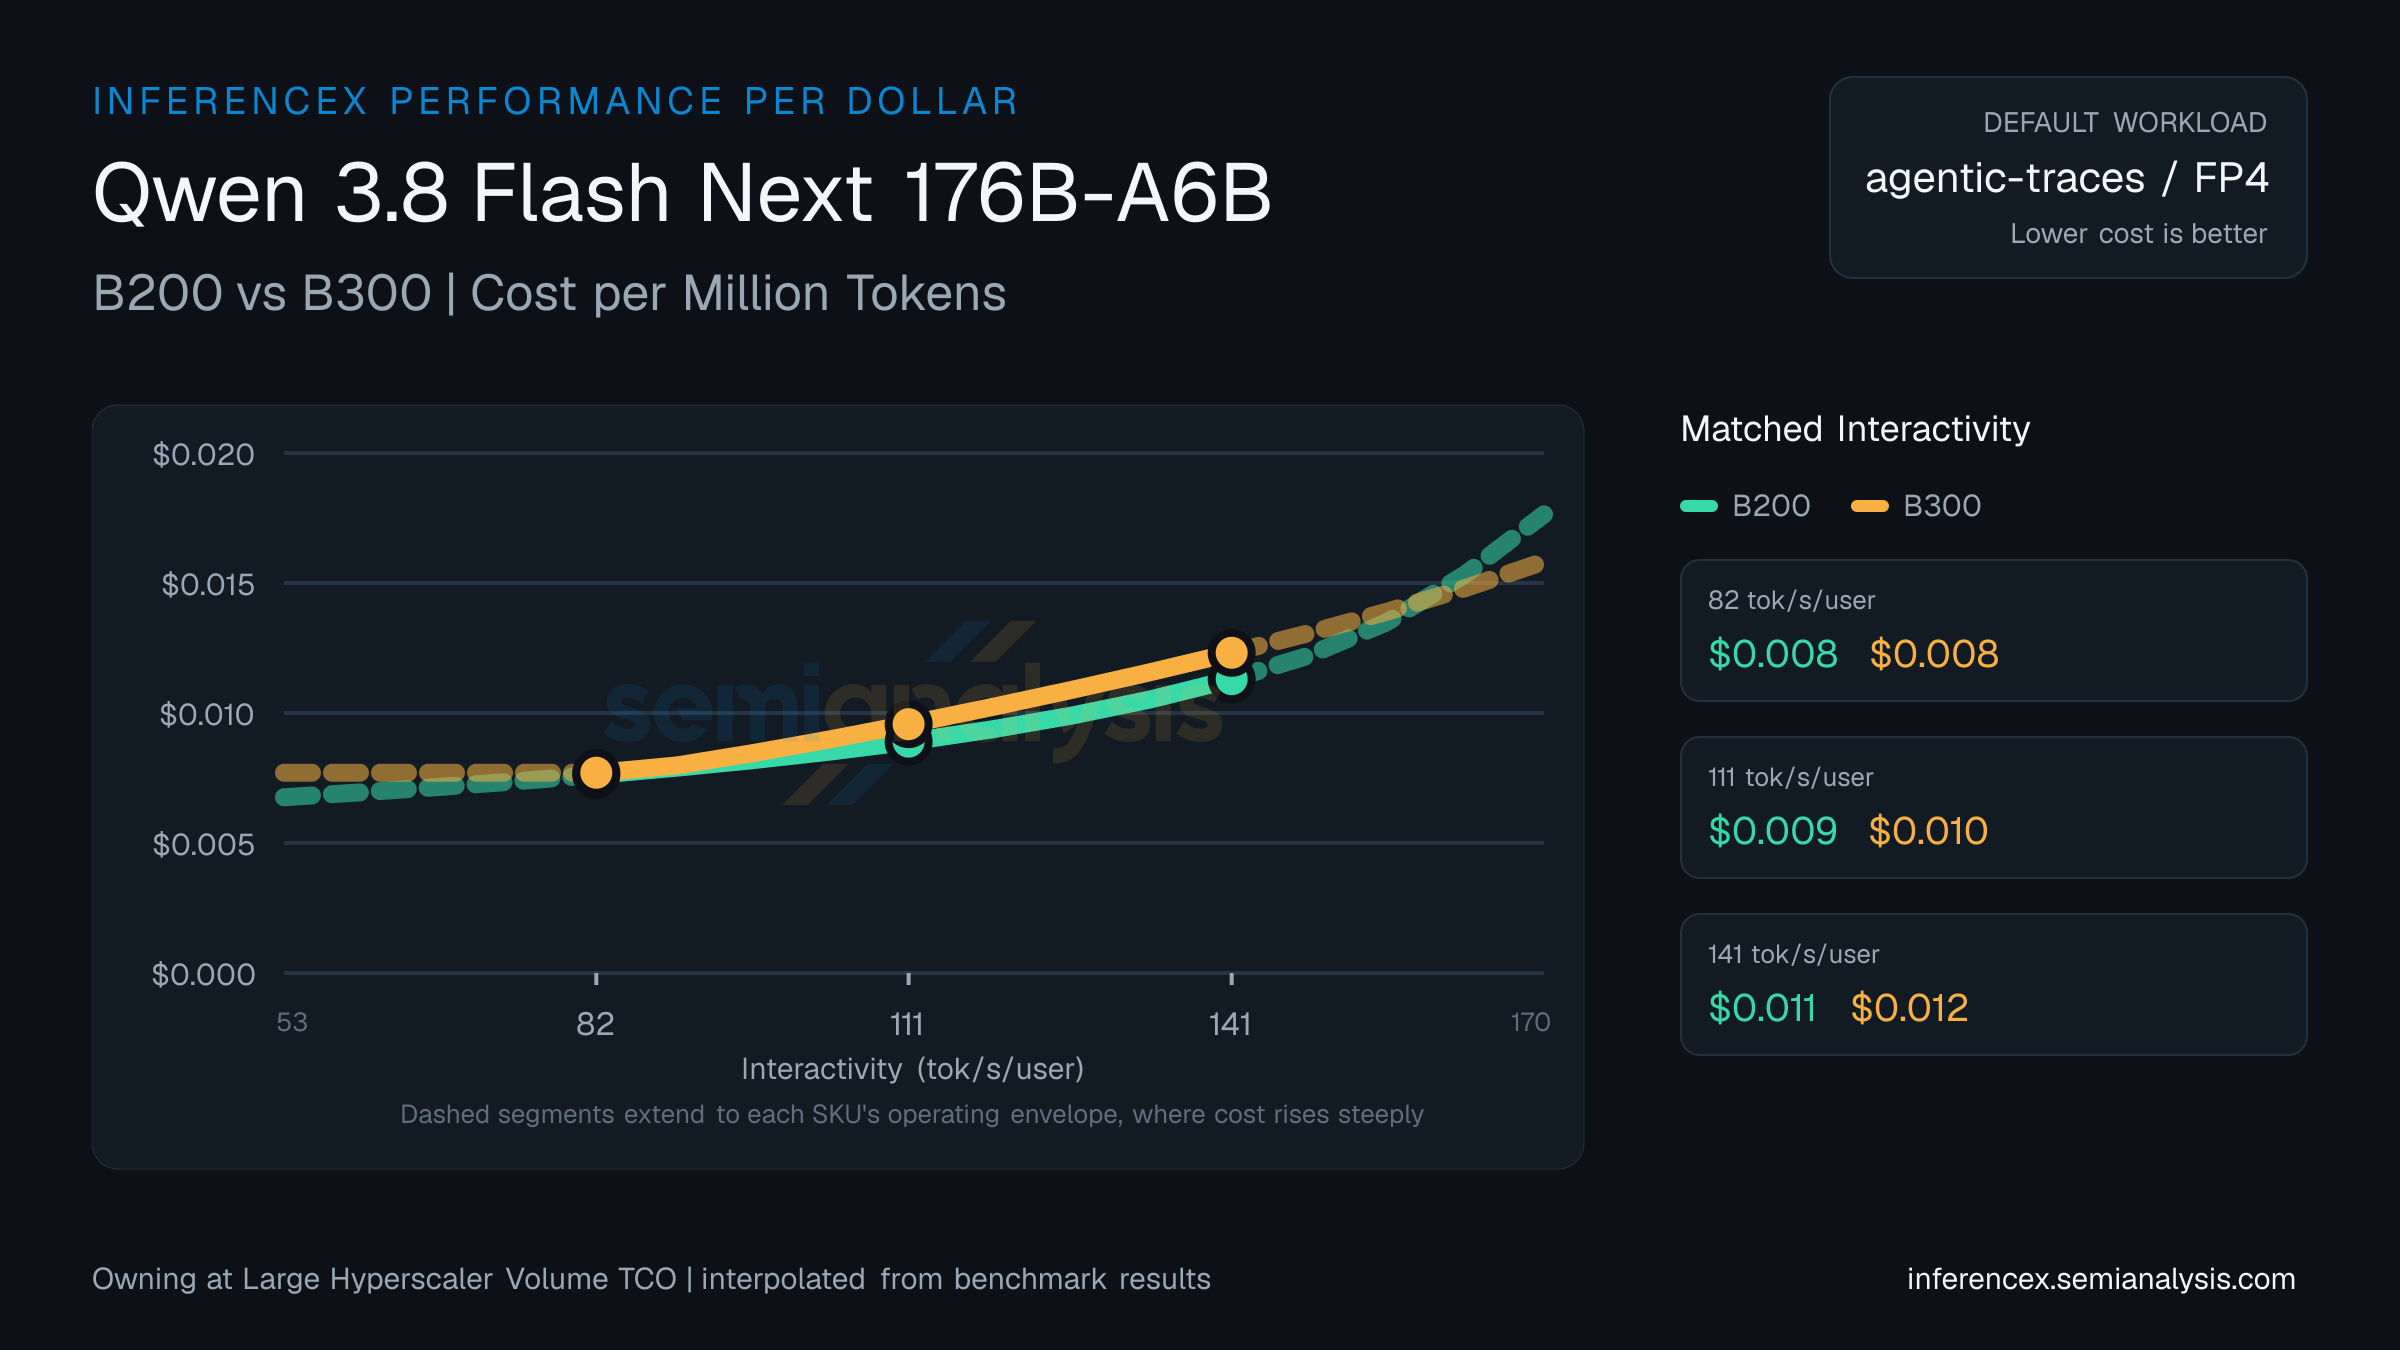
Cost per million tokens of B200 (NVIDIA Blackwell) versus B300 (NVIDIA Blackwell) on Qwen 3.8 Flash Next 176B-A6B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
Push Qwen 3.8 Flash Next 176B-A6B to 82 tok/s/user and B200 lands at $0.01 per million tokens against B300's $0.01 — B200 pulls ahead by 1%.
B200: $0.01 per million tokens. B300: $0.01. Both at 111 tok/s/user on Qwen 3.8 Flash Next 176B-A6B, with B200 8% cheaper.
Toward the upper edge of the 53–170 tok/s/user interactivity band — at 141 tok/s/user — B200 runs $0.01 per million tokens on Qwen 3.8 Flash Next 176B-A6B while B300 runs $0.01. B200 is the cheaper choice by 9%. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): B200 $1.73/chip/hr · B300 $2.26/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | B200:$0.008B300:$0.008 | B200:$0.009B300:$0.010 | B200:$0.011B300:$0.012 |
| Concurrency | B200:~14B300:~16 | B200:~12B300:~13 | B200:~9B300:~10 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
Qwen3.8 Flash Next 176B Cost per Million Total Tokens vs. Interactivity
 Qwen3.8 Flash Next 176B
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.