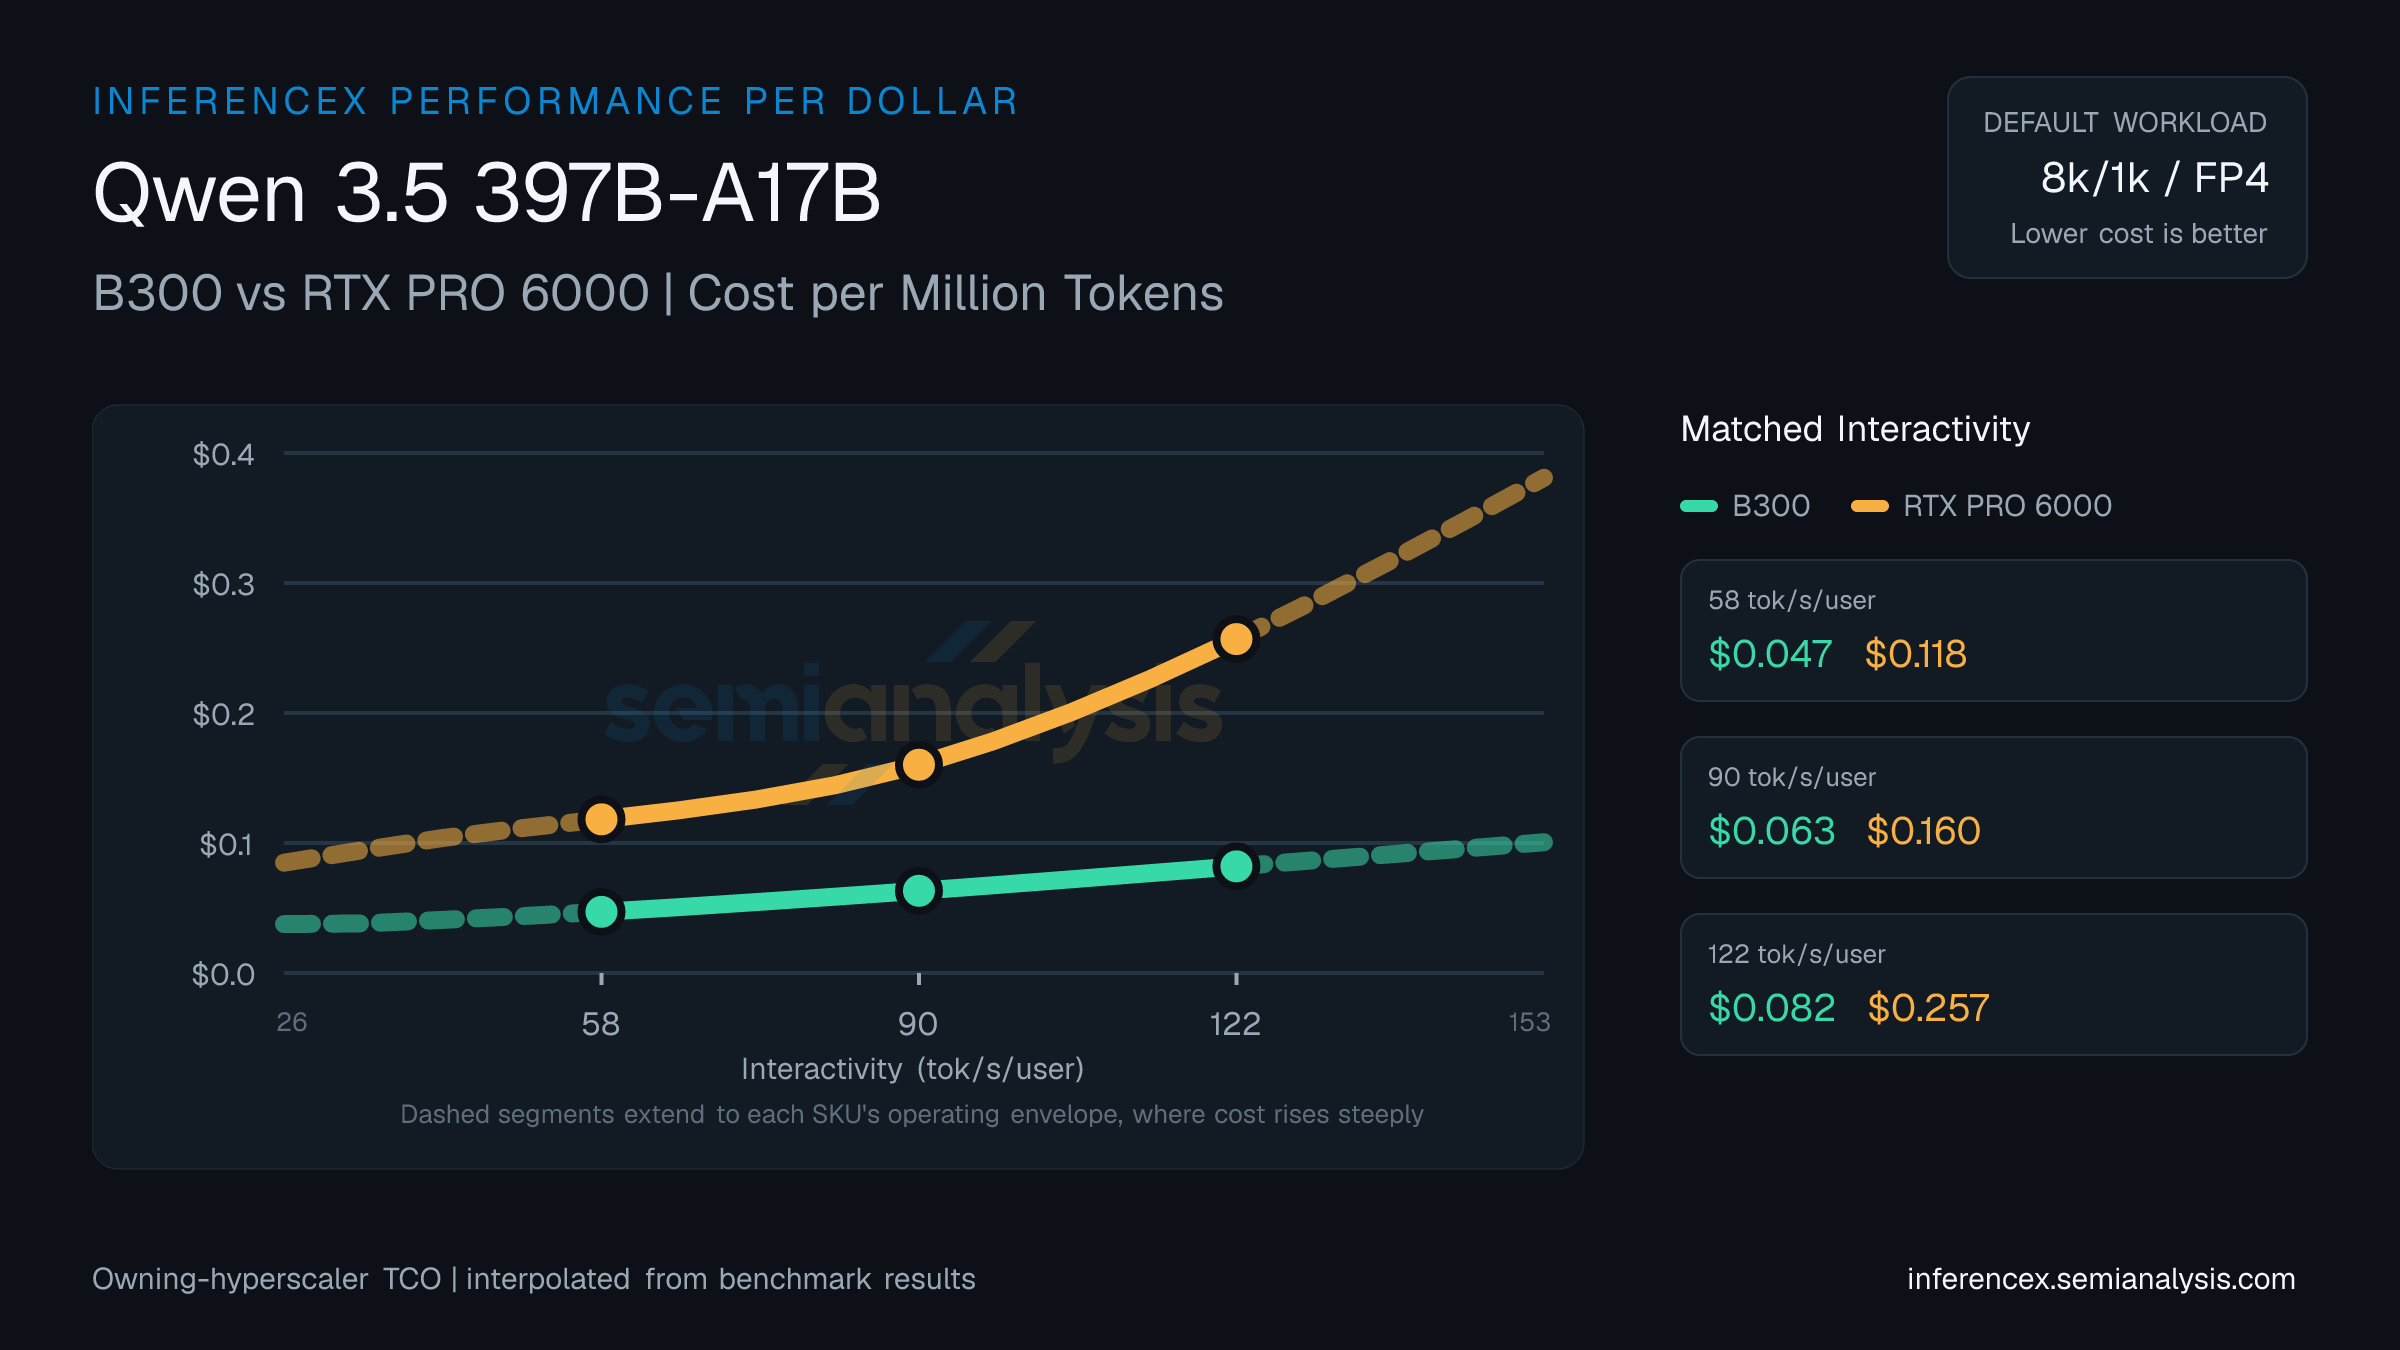
Qwen 3.5 397B-A17B — B300 vs RTX PRO 6000 Performance per Dollar
Cost per million tokens of B300 (NVIDIA Blackwell) versus RTX PRO 6000 (NVIDIA Blackwell) on Qwen 3.5 397B-A17B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
Near the low end of the 28–153 tok/s/user interactivity band — at 59 tok/s/user — B300 runs $0.04 per million tokens on Qwen 3.5 397B-A17B while RTX PRO 6000 runs $0.20. B300 is the cheaper choice by 433%.
On Qwen 3.5 397B-A17B at 91 tok/s/user, the per-million math comes out to $0.05 for B300 and $0.26 for RTX PRO 6000; B300 delivers 418% more total tokens per dollar.
At 122 tok/s/user on Qwen 3.5 397B-A17B, B300 costs $0.06 per million tokens; RTX PRO 6000 costs $0.37. B300 is 494% more cost-efficient at this operating point. (Numbers reflect the default 8k/1k · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): B300 $2.26/chip/hr · RTX PRO 6000 $0.68/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | B300:$0.037RTX PRO 6000:$0.199 | B300:$0.050RTX PRO 6000:$0.257 | B300:$0.062RTX PRO 6000:$0.369 |
| Concurrency | B300:~70RTX PRO 6000:~9 | B300:~34RTX PRO 6000:~4 | B300:~20RTX PRO 6000:~2 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
Qwen3.5 397B 8K / 1K Cost per Million Total Tokens vs. Median Interactivity
 Qwen3.5 397B 8K / 1K Cost per Million Total Tokens vs. Median Interactivity
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
Matching measurements exist, but their chip series are hidden.
Shift+Scroll to zoom • Drag to pan • Double-click to reset • Click a point to pin tooltip