GB300 NVL72 FP8: MTP vs Off Speculative Decoding
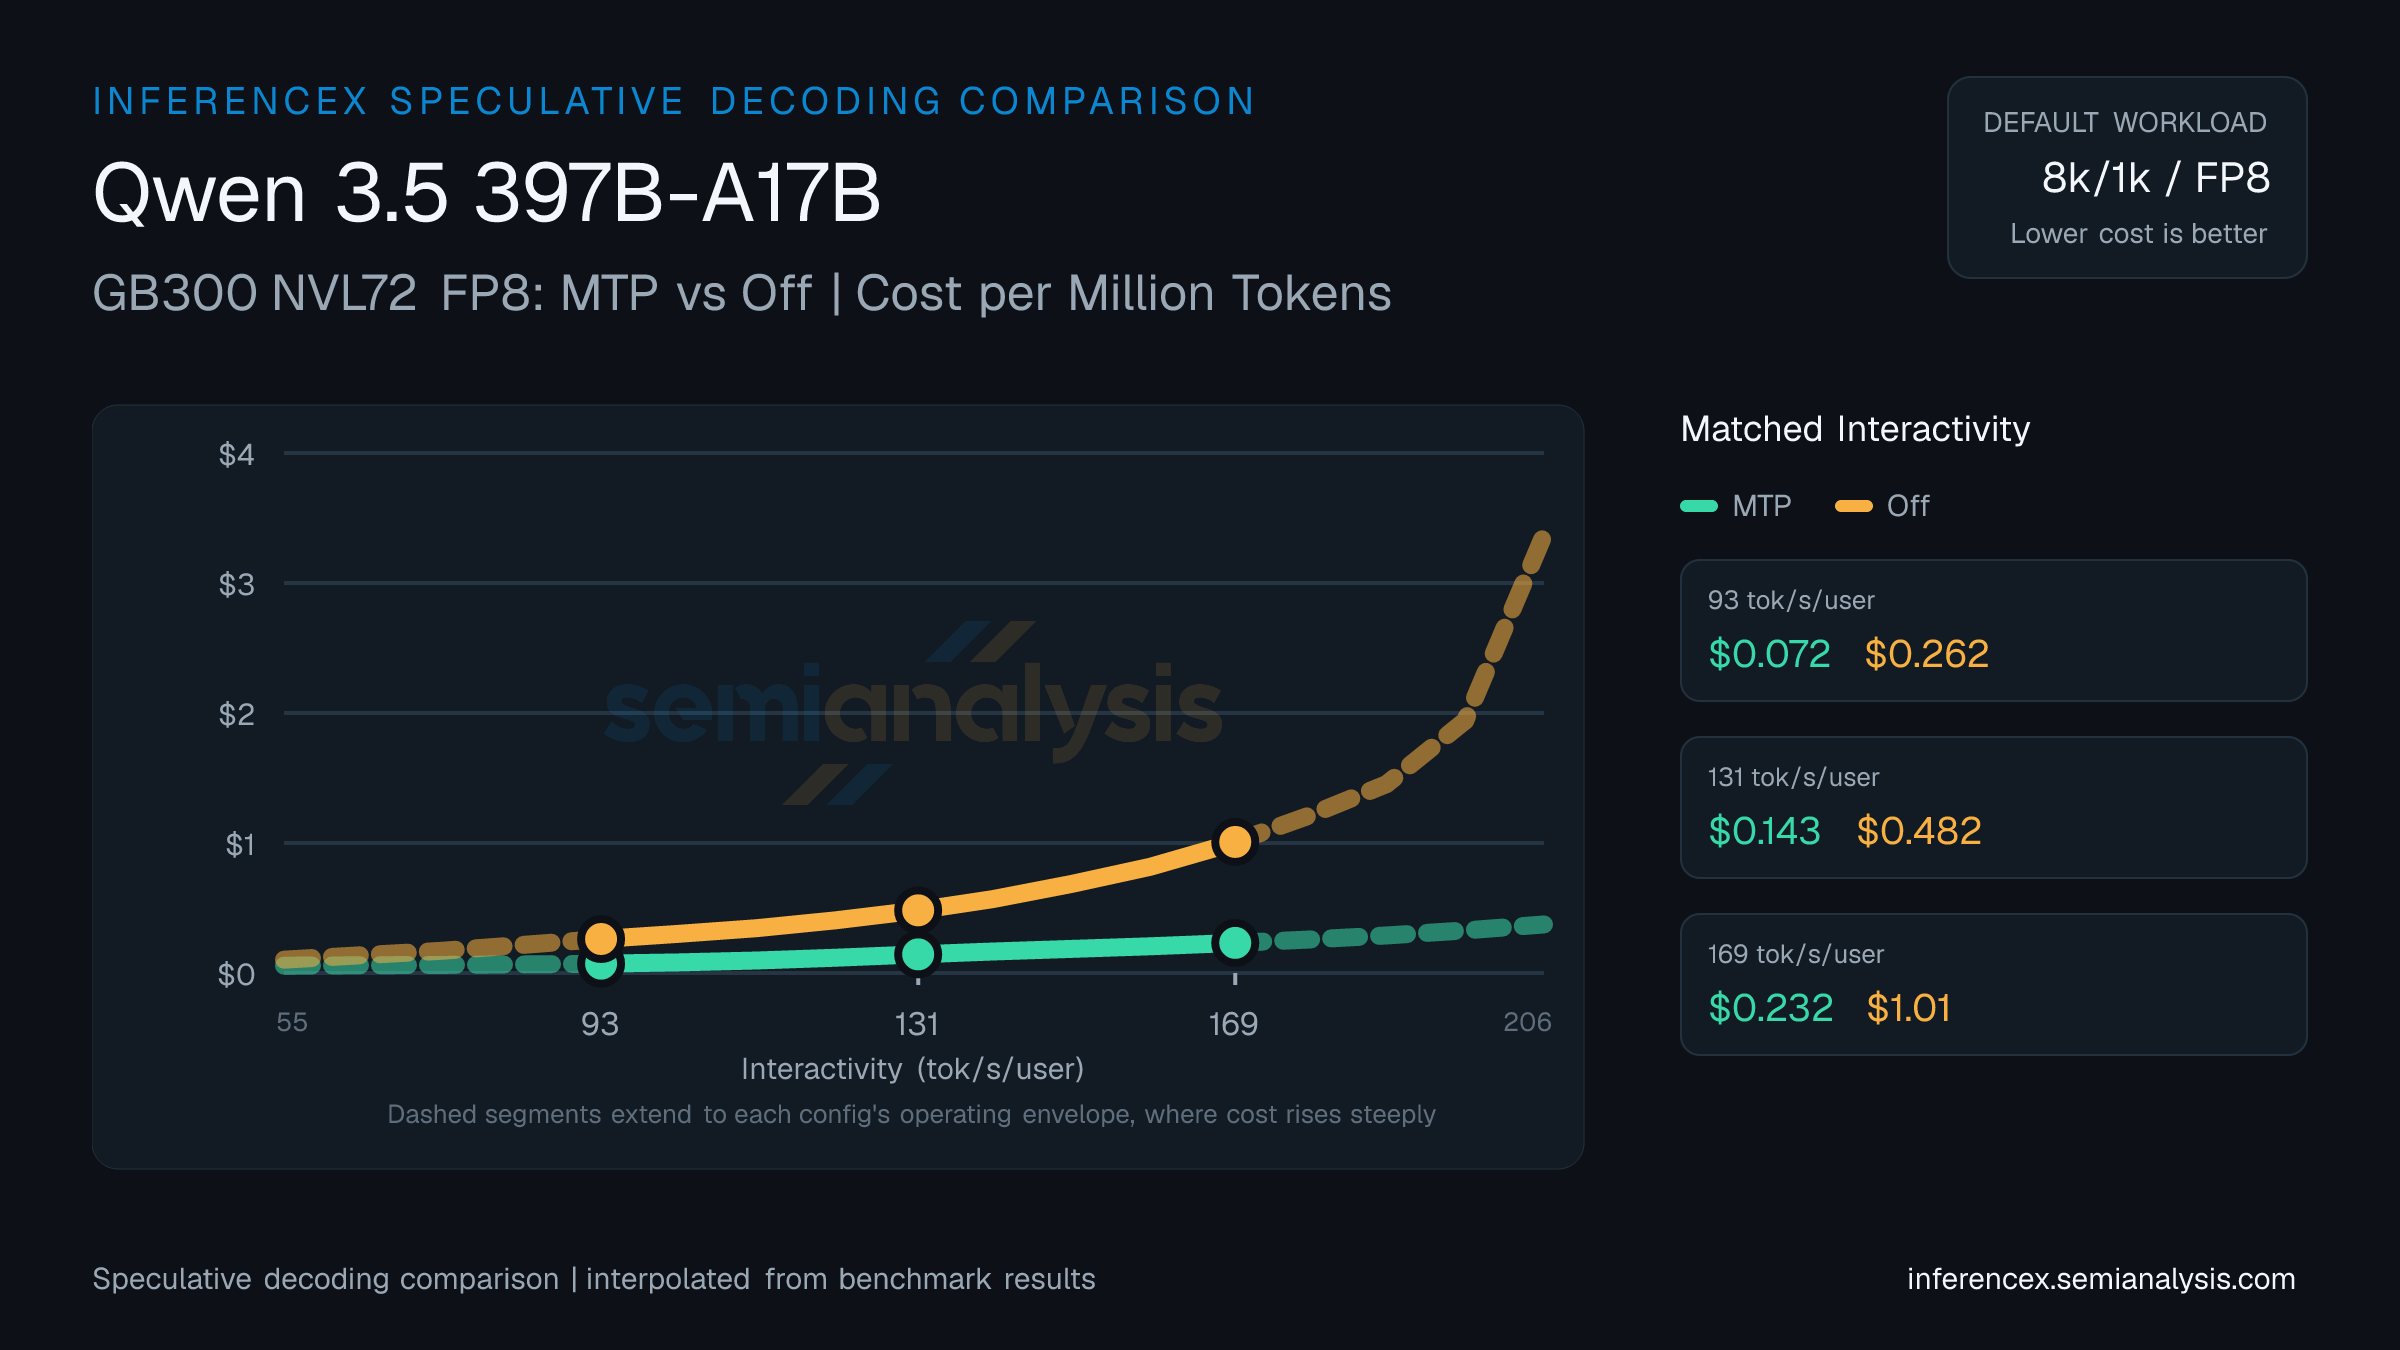
Speculative decoding comparison of MTP versus Off on GB300 NVL72 FP8 (NVIDIA Blackwell) running Qwen 3.5 397B-A17B. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
MTP posts 9759 tok/s/chip for $0.07 per million tokens at 97 tok/s/user on Qwen 3.5 397B-A17B (GB300 NVL72 FP8); Off posts 2882 tok/s/chip for $0.22. MTP is 239% cheaper per token; MTP delivers 239% more tok/s/chip. Draft-token acceptance rates determine whether speculative decoding helps or hurts at a given concurrency level.
Throughput at 139 tok/s/user on Qwen 3.5 397B-A17B (GB300 NVL72 FP8): MTP hits 4513 tok/s/chip, Off hits 1616. Per-million costs land at $0.14 and $0.40 respectively. MTP is 179% cheaper per token; MTP delivers 179% more tok/s/chip. Speculative decoding trades extra compute on draft tokens for fewer decoding steps — the payoff depends on sequence length and batch size.
Toward the upper edge of the 55–223 tok/s/user interactivity band, at 181 tok/s/user on Qwen 3.5 397B-A17B (GB300 NVL72 FP8): MTP runs 2749 tok/s/chip at $0.23/M tokens, Off runs 851 at $0.75/M. MTP is 223% cheaper per token; MTP delivers 223% more tok/s/chip. Gains from speculative decoding vary by workload; short-output prompts tend to benefit less. (Numbers reflect this URL's pinned 8k/1k · fp8 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP:9758.8Off:2881.6 | MTP:4512.8Off:1615.8 | MTP:2749.2Off:850.7 |
| Cost ($/M tok) | MTP:$0.066Off:$0.223 | MTP:$0.142Off:$0.397 | MTP:$0.233Off:$0.754 |
| tok/s/MW | MTP:4603210Off:1359245 | MTP:2128670Off:762160 | MTP:1296791Off:401264 |
| Concurrency | MTP:~784Off:~28 | MTP:~80Off:~11 | MTP:~38Off:~5 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.