B200 FP8: MTP vs Off Speculative Decoding
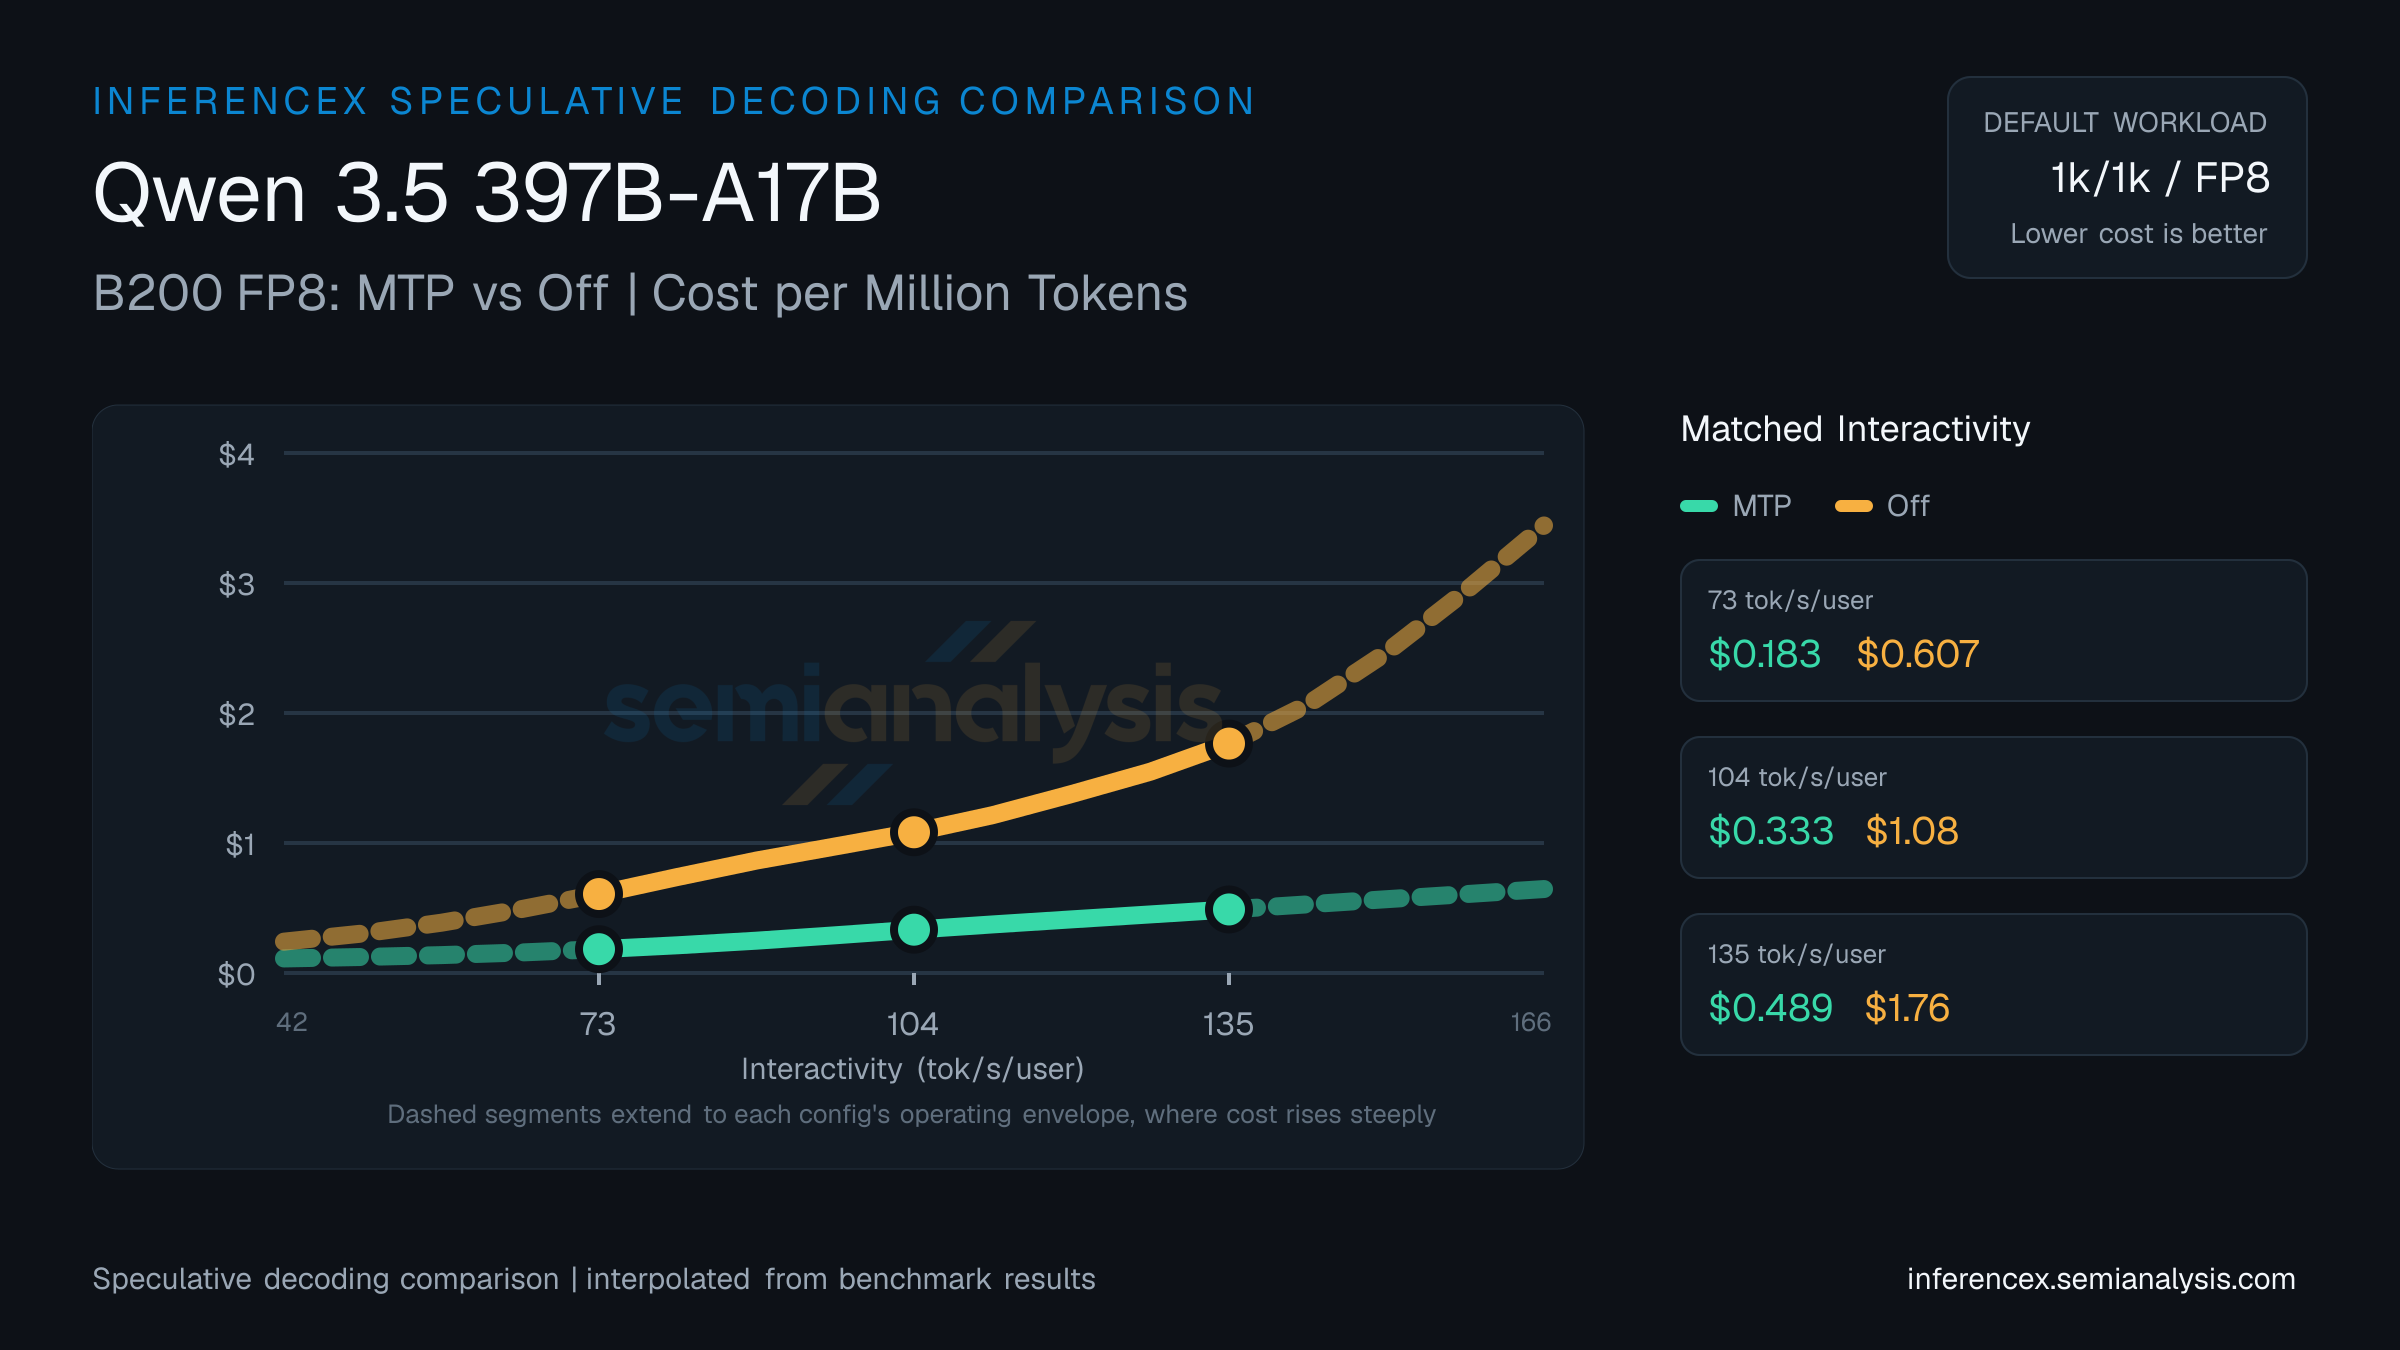
Speculative decoding comparison of MTP versus Off on B200 FP8 (NVIDIA Blackwell) running Qwen 3.5 397B-A17B. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
Throughput at 74 tok/s/user on Qwen 3.5 397B-A17B (B200 FP8): MTP hits 8147 tok/s/chip, Off hits 4542. Per-million costs land at $0.06 and $0.11 respectively. MTP is 79% cheaper per token; MTP delivers 79% more tok/s/chip. Speculative decoding trades extra compute on draft tokens for fewer decoding steps — the payoff depends on sequence length and batch size.
Around the middle of the 23–226 tok/s/user interactivity band, at 124 tok/s/user on Qwen 3.5 397B-A17B (B200 FP8): MTP runs 5867 tok/s/chip at $0.08/M tokens, Off runs 2631 at $0.18/M. MTP is 123% cheaper per token; MTP delivers 123% more tok/s/chip. Gains from speculative decoding vary by workload; short-output prompts tend to benefit less.
At 175 tok/s/user on Qwen 3.5 397B-A17B (B200 FP8), MTP delivers 4342 tok/s/chip at $0.11 per million tokens; Off delivers 1338 tok/s/chip at $0.36. MTP is 225% cheaper per token; MTP delivers 225% more tok/s/chip. Speculative decoding accepts draft tokens to reduce per-token latency — gains vary by workload and prompt distribution. (Numbers reflect this URL's pinned 8k/1k · fp8 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP:8147.0Off:4541.9 | MTP:5866.8Off:2630.6 | MTP:4342.1Off:1338.0 |
| Cost ($/M tok) | MTP:$0.059Off:$0.106 | MTP:$0.082Off:$0.183 | MTP:$0.111Off:$0.359 |
| tok/s/MW | MTP:4764309Off:2656104 | MTP:3430887Off:1538371 | MTP:2539215Off:782445 |
| Concurrency | MTP:~52Off:~29 | MTP:~23Off:~10 | MTP:~12Off:~4 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.