
GB200 NVL72: FP4 vs FP8 Precision Comparison
How FP4 and FP8 precision affect Qwen 3.5 397B-A17B inference on GB200 NVL72 (NVIDIA Blackwell). Throughput, latency, and cost across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
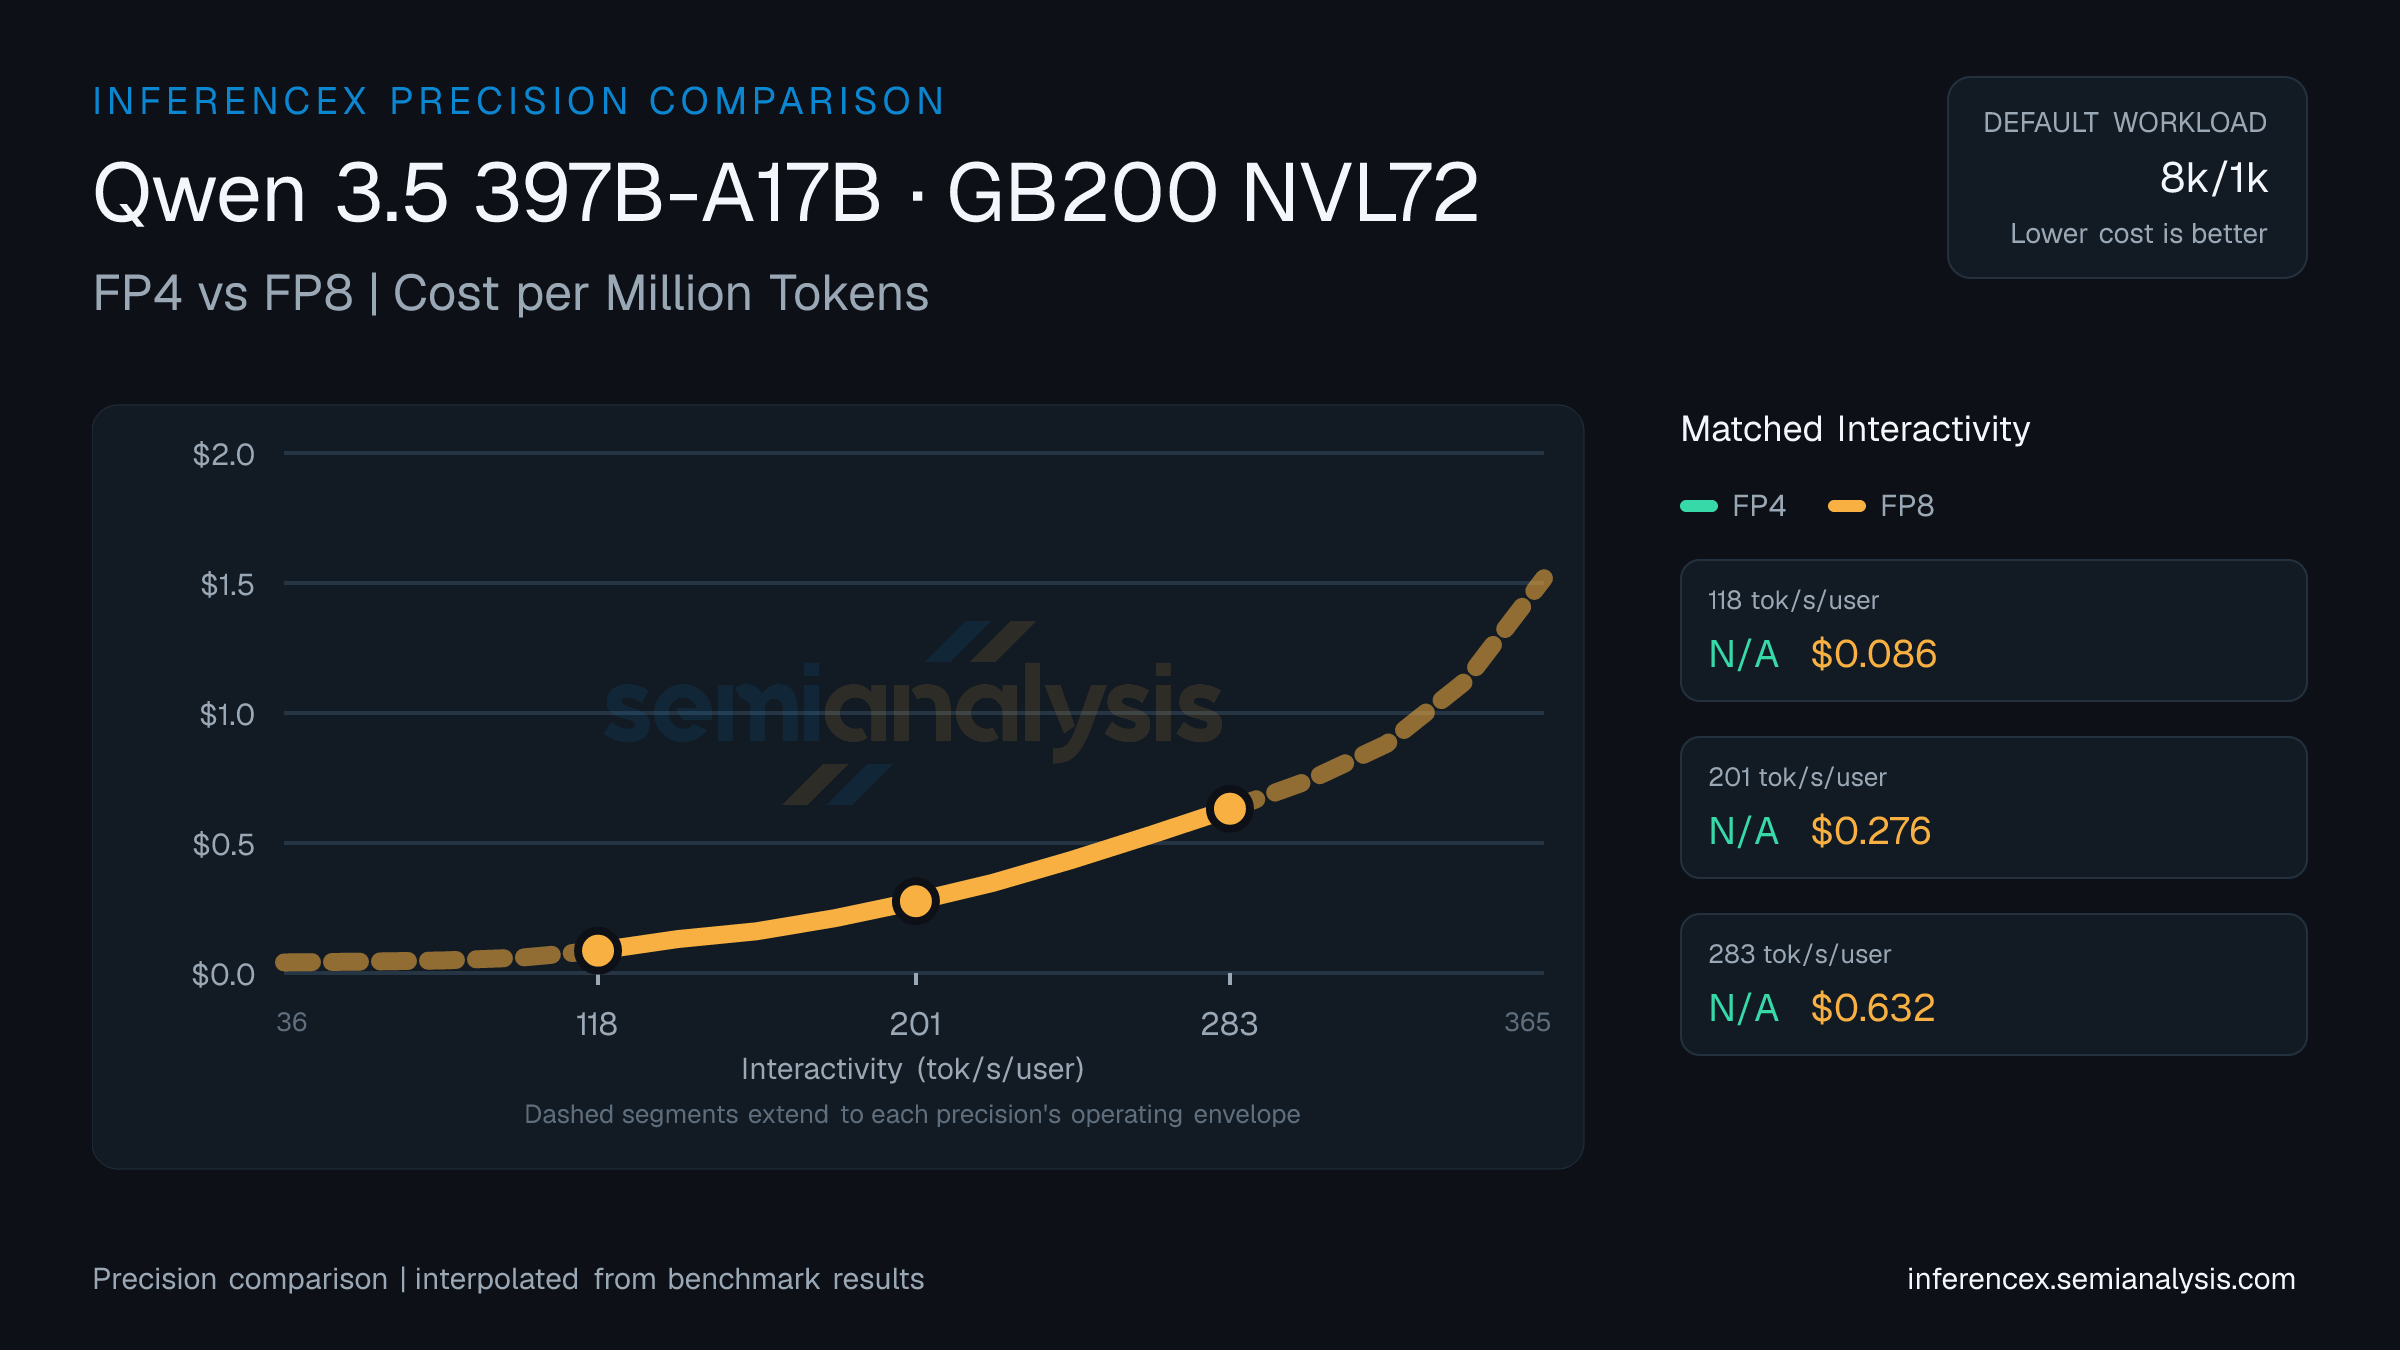
FP8: 6147 tok/s/chip, $0.08 per million tokens at 135 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72). FP4 is unmeasured here.
At 224 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72), FP8 delivers 2182 tok/s/chip at $0.24 per million tokens; FP4 hasn't been benchmarked at this target.
FP8 hits 1089 tok/s/chip for $0.47 per million tokens at 312 tok/s/user on Qwen 3.5 397B-A17B (GB200 NVL72). No FP4 data at this operating point. (Numbers reflect the default 8k/1k selection for this URL — table and chart below update if you change sequence or model in the controls. Each side uses the best available serving configuration for that precision, which may include speculative decoding such as MTP where recipes exist — the same convention as the other comparison pages.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | FP4:—FP8:6147.0 | FP4:—FP8:2181.8 | FP4:—FP8:1089.4 |
| Cost ($/M tok) | FP4:—FP8:$0.084 | FP4:—FP8:$0.237 | FP4:—FP8:$0.474 |
| tok/s/MW | FP4:—FP8:3287163 | FP4:—FP8:1166737 | FP4:—FP8:582554 |
| Concurrency | FP4:—FP8:~238 | FP4:—FP8:~17 | FP4:—FP8:~4 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.