MiniMax M3 428B · GB200 NVL72 · Precision comparison
GB200 NVL72: FP4 vs FP8 precision comparison
How FP4 and FP8 precision affect MiniMax M3 428B inference on GB200 NVL72 (NVIDIA Blackwell). Throughput, latency, and cost across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
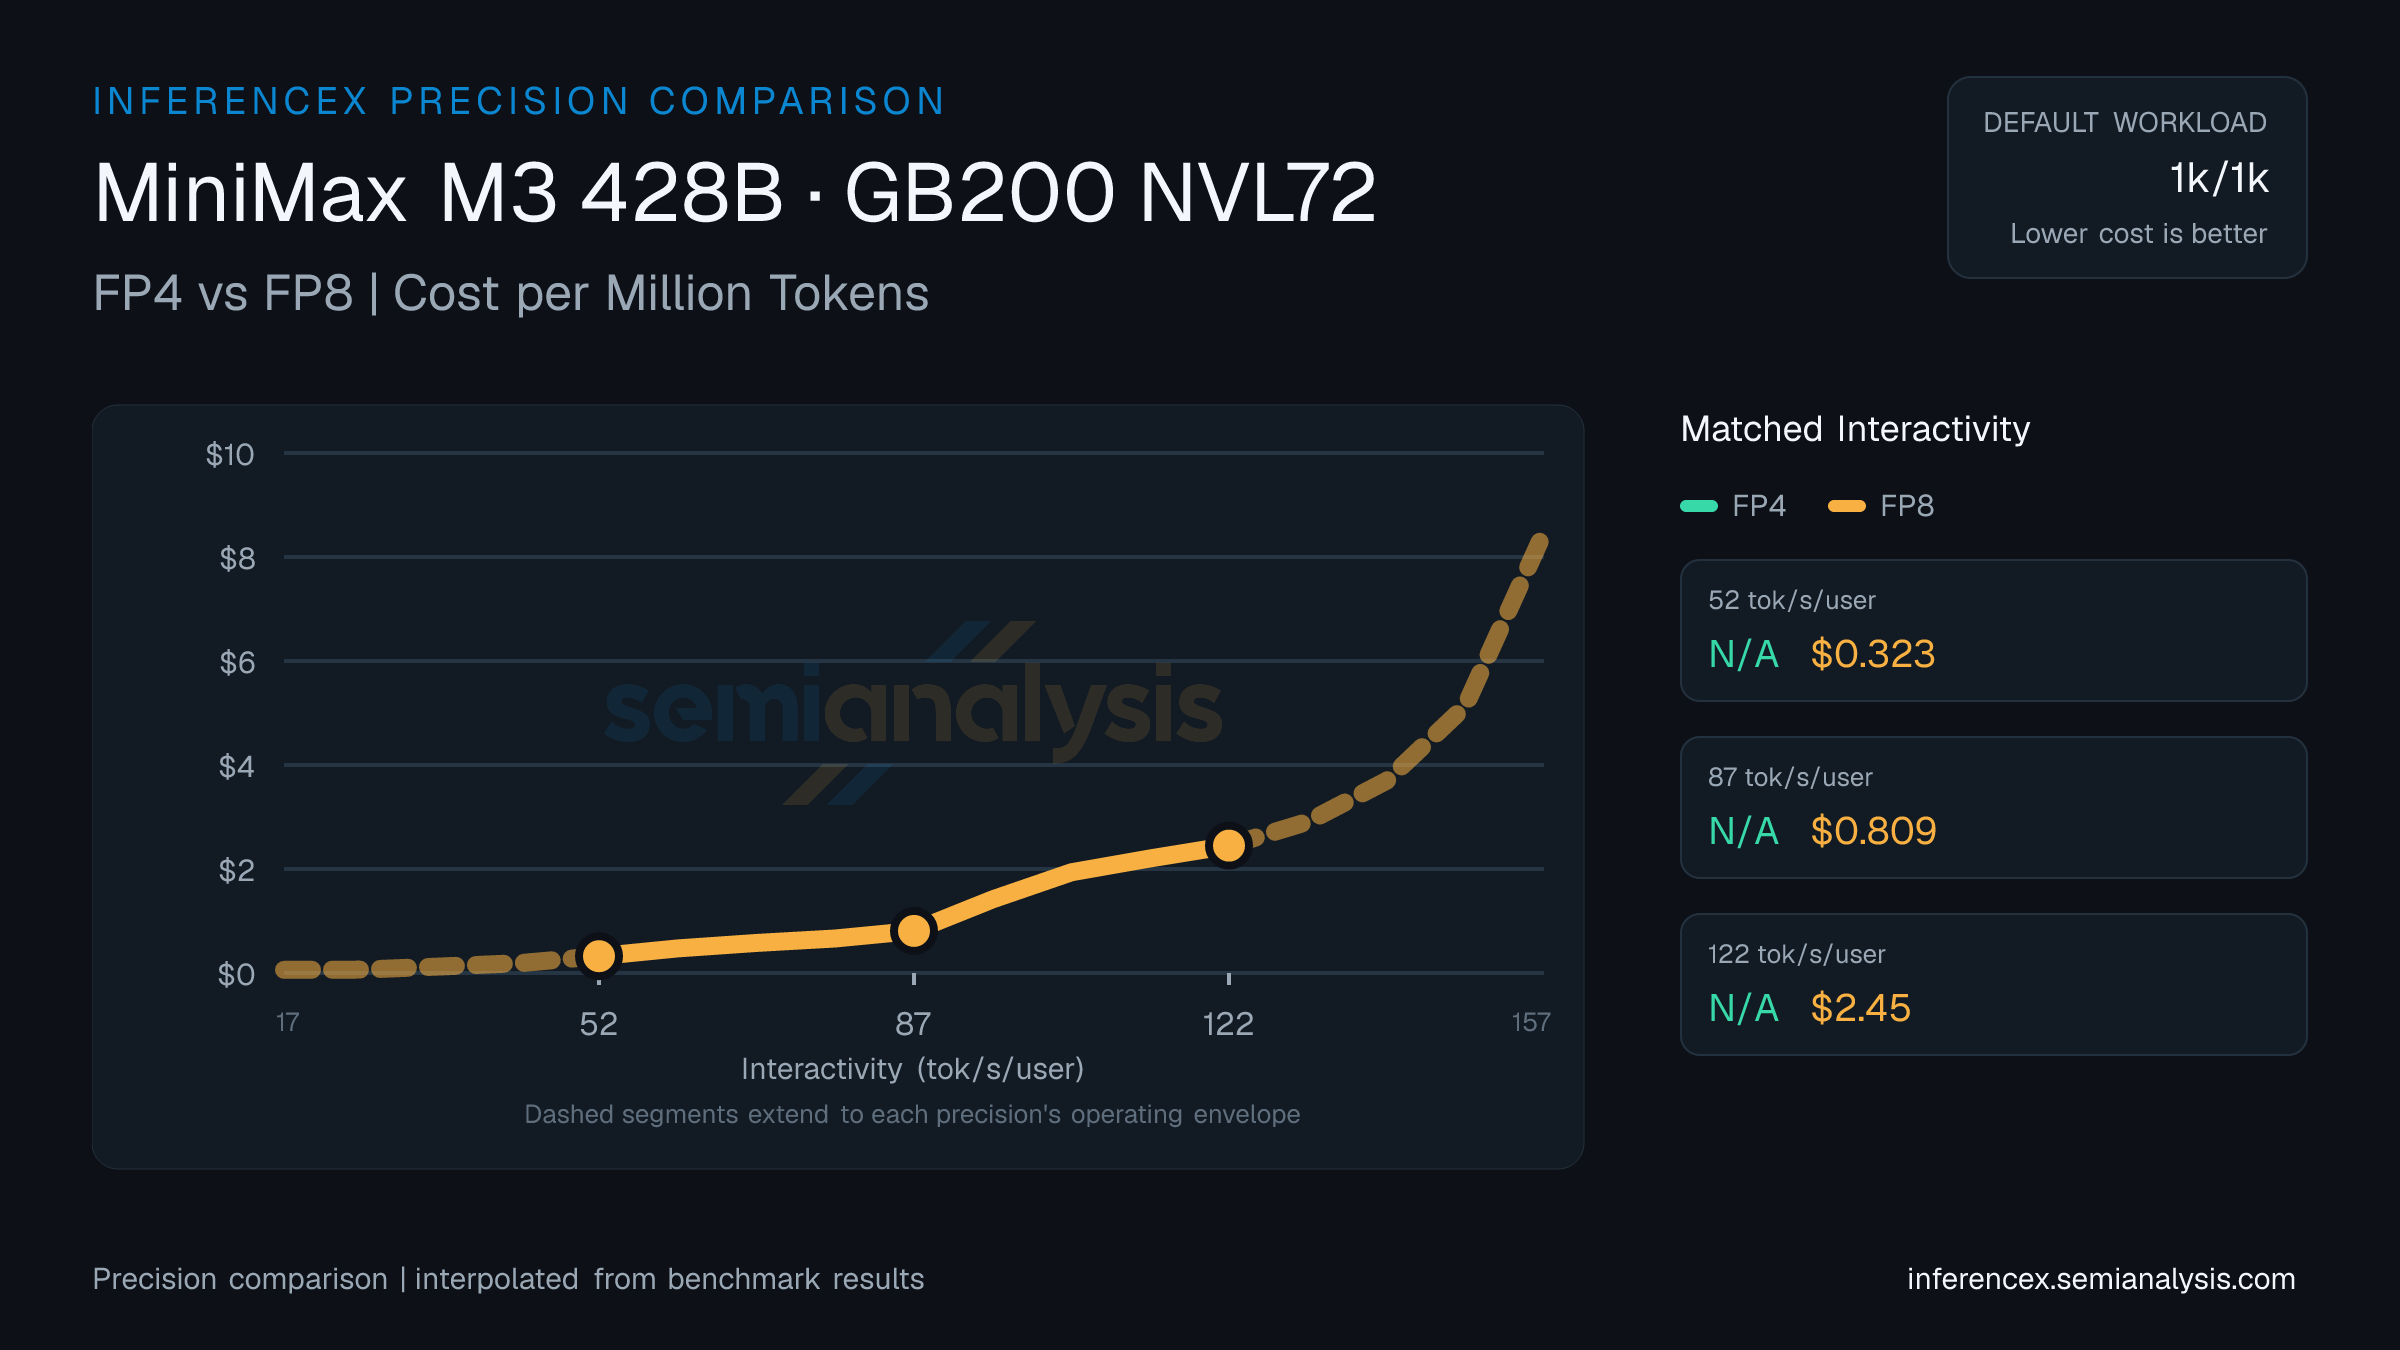
At 52 tok/s/user on MiniMax M3 428B (GB200 NVL72), FP8 delivers 1,598 tok/s/chip at $0.32 per million tokens; FP4 hasn't been benchmarked at this target.
FP8 hits 638 tok/s/chip for $0.81 per million tokens at 87 tok/s/user on MiniMax M3 428B (GB200 NVL72). No FP4 data at this operating point.
FP8: 211 tok/s/chip, $2.45 per million tokens at 122 tok/s/user on MiniMax M3 428B (GB200 NVL72). FP4 is unmeasured here. (Numbers reflect the default 1k/1k selection for this URL — table and chart below update if you change sequence or model in the controls. Each side uses the best available serving configuration for that precision, which may include speculative decoding such as MTP where recipes exist — the same convention as the other comparison pages.)
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | FP4—FP81,598 | FP4—FP8638 | FP4—FP8211 |
| Cost ($/M tok) | FP4—FP8$0.32 | FP4—FP8$0.81 | FP4—FP8$2.45 |
| tok/s/MW | FP4—FP8854,626 | FP4—FP8341,360 | FP4—FP8112,801 |
| Concurrency | FP4—FP8~180 | FP4—FP8~74 | FP4—FP8~18 |