
Qwen 3.5 397B-A17B — GB200 NVL72 vs H200 Performance per Dollar
Cost per million tokens of GB200 NVL72 (NVIDIA Blackwell) versus H200 (NVIDIA Hopper) on Qwen 3.5 397B-A17B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
Push Qwen 3.5 397B-A17B to 81 tok/s/user and GB200 NVL72 lands at $0.05 per million tokens against H200's $0.23 — GB200 NVL72 pulls ahead by 372%.
GB200 NVL72: $0.06 per million tokens. H200: $0.29. Both at 117 tok/s/user on Qwen 3.5 397B-A17B, with GB200 NVL72 420% cheaper.
Toward the upper edge of the 46–187 tok/s/user interactivity band — at 152 tok/s/user — GB200 NVL72 runs $0.12 per million tokens on Qwen 3.5 397B-A17B while H200 runs $0.36. GB200 NVL72 is the cheaper choice by 200%. (Numbers reflect the default 8k/1k · fp8 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): GB200 NVL72 $1.86/chip/hr · H200 $1.22/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
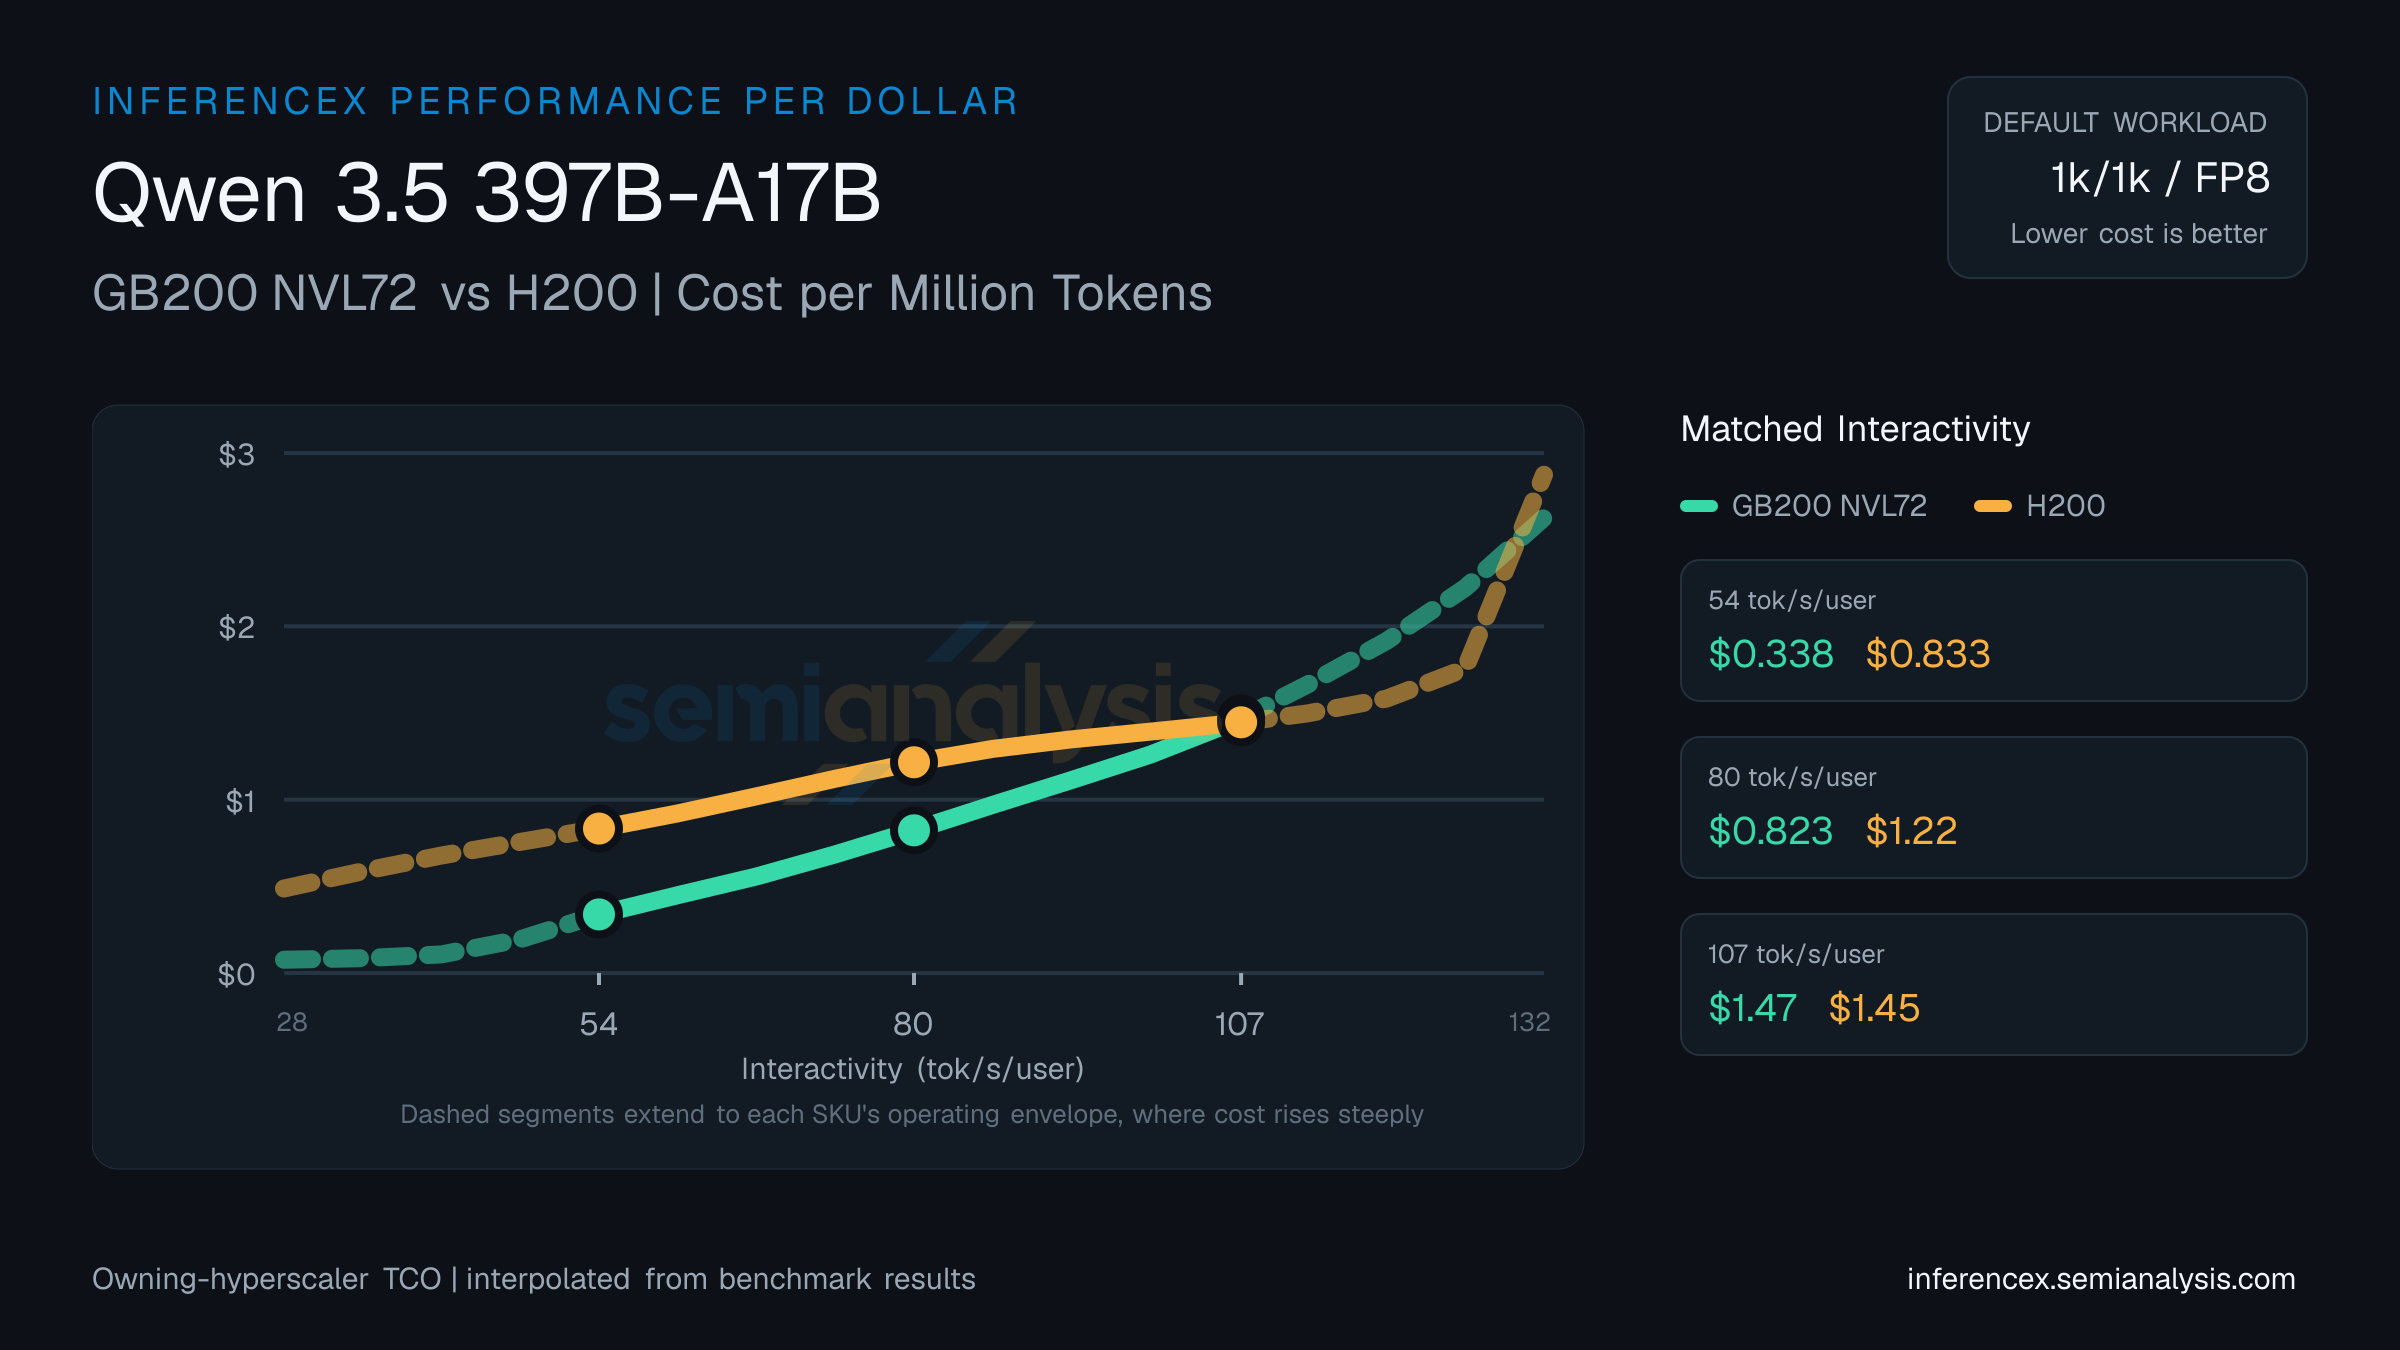
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | GB200 NVL72:$0.049H200:$0.230 | GB200 NVL72:$0.057H200:$0.295 | GB200 NVL72:$0.121H200:$0.364 |
| Concurrency | GB200 NVL72:~1187H200:~17 | GB200 NVL72:~680H200:~9 | GB200 NVL72:~64H200:~6 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
Qwen3.5 397B 8K / 1K Cost per Million Total Tokens vs. Interactivity
 Qwen3.5 397B 8K / 1K Cost per Million Total Tokens vs. Interactivity
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.
Shift+Scroll to zoom • Drag to pan • Double-click to reset • Click a point to pin tooltip