Muse Spark 1.3/Open 816B · Performance per dollar
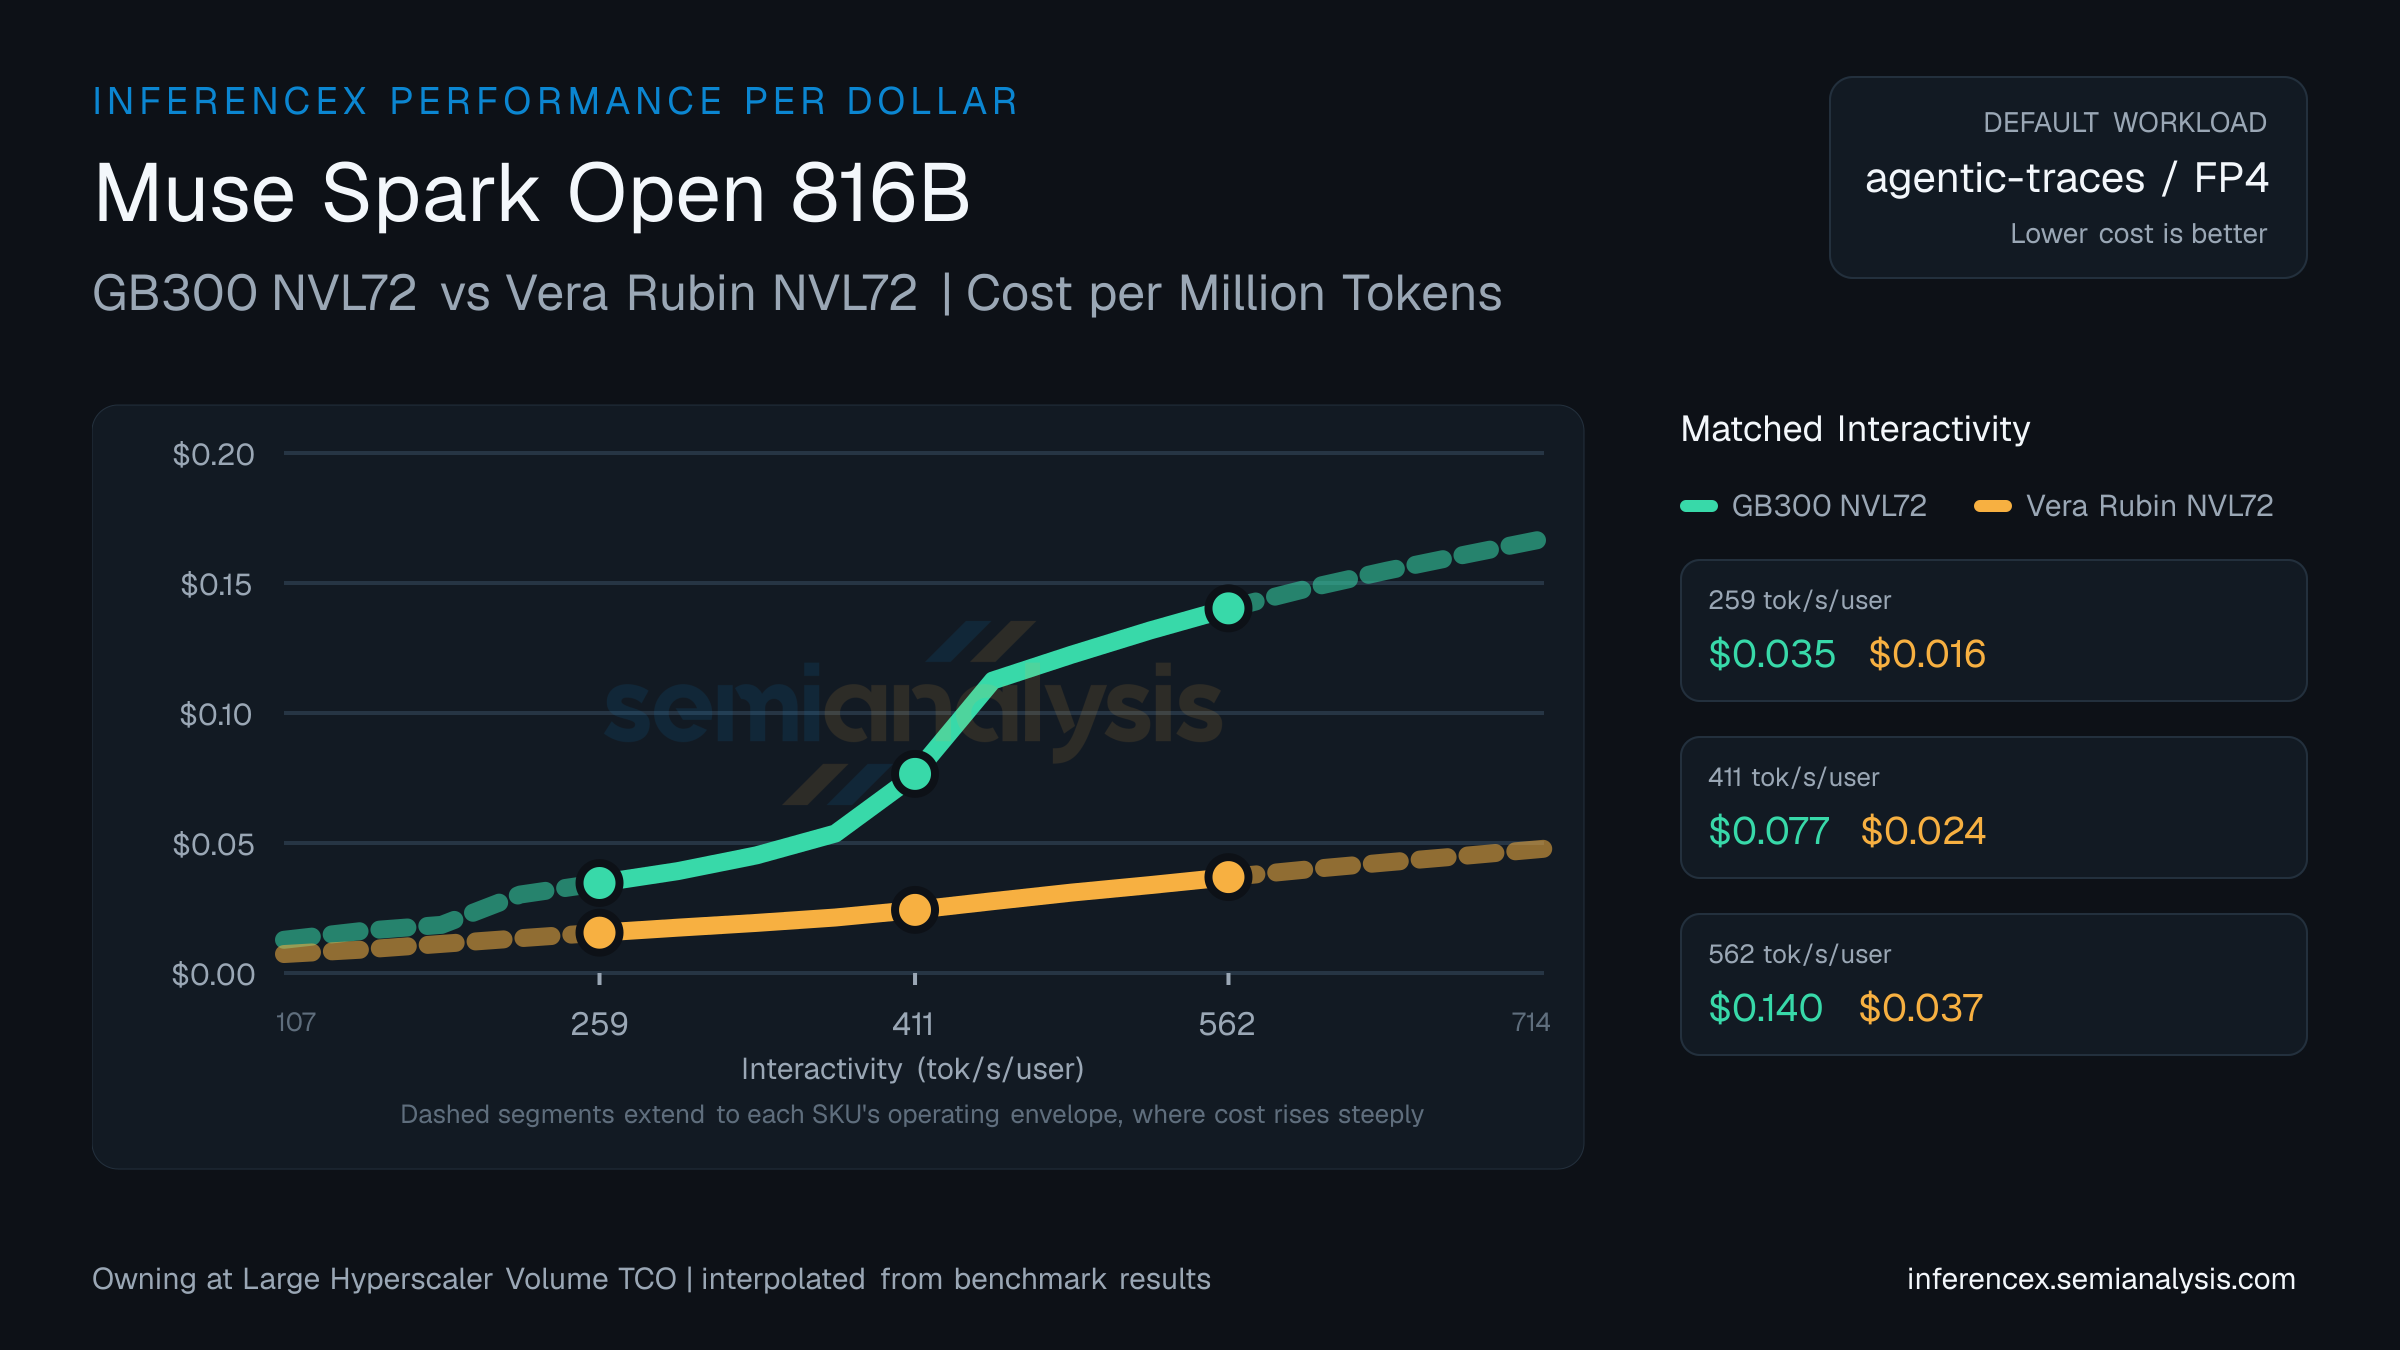
Muse Spark 1.3/Open 816B — GB300 NVL72 vs Vera Rubin NVL72 performance per dollar
Cost per million tokens of GB300 NVL72 (NVIDIA Blackwell) versus Vera Rubin NVL72 (NVIDIA Vera Rubin) on Muse Spark 1.3/Open 816B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
On Muse Spark 1.3/Open 816B at 259 tok/s/user, the per-million math comes out to $0.026 for GB300 NVL72 and $0.016 for Vera Rubin NVL72; Vera Rubin NVL72 delivers 66% more total tokens per dollar.
At 411 tok/s/user on Muse Spark 1.3/Open 816B, GB300 NVL72 costs $0.060 per million tokens; Vera Rubin NVL72 costs $0.024. Vera Rubin NVL72 delivers 148% more tokens per dollar at this operating point.
Vera Rubin NVL72 edges GB300 NVL72 at 562 tok/s/user on Muse Spark 1.3/Open 816B — $0.037 per million tokens versus $0.13, a 72% lower cost per token. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): GB300 NVL72 $2.31/chip/hr · Vera Rubin NVL72 $3.61/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollars per million tokens | GB300 NVL72$0.026Vera Rubin NVL72$0.016 | GB300 NVL72$0.060Vera Rubin NVL72$0.024 | GB300 NVL72$0.13Vera Rubin NVL72$0.037 |
| Concurrency | GB300 NVL72~53Vera Rubin NVL72~35 | GB300 NVL72~54Vera Rubin NVL72~39 | GB300 NVL72~12Vera Rubin NVL72~100 |