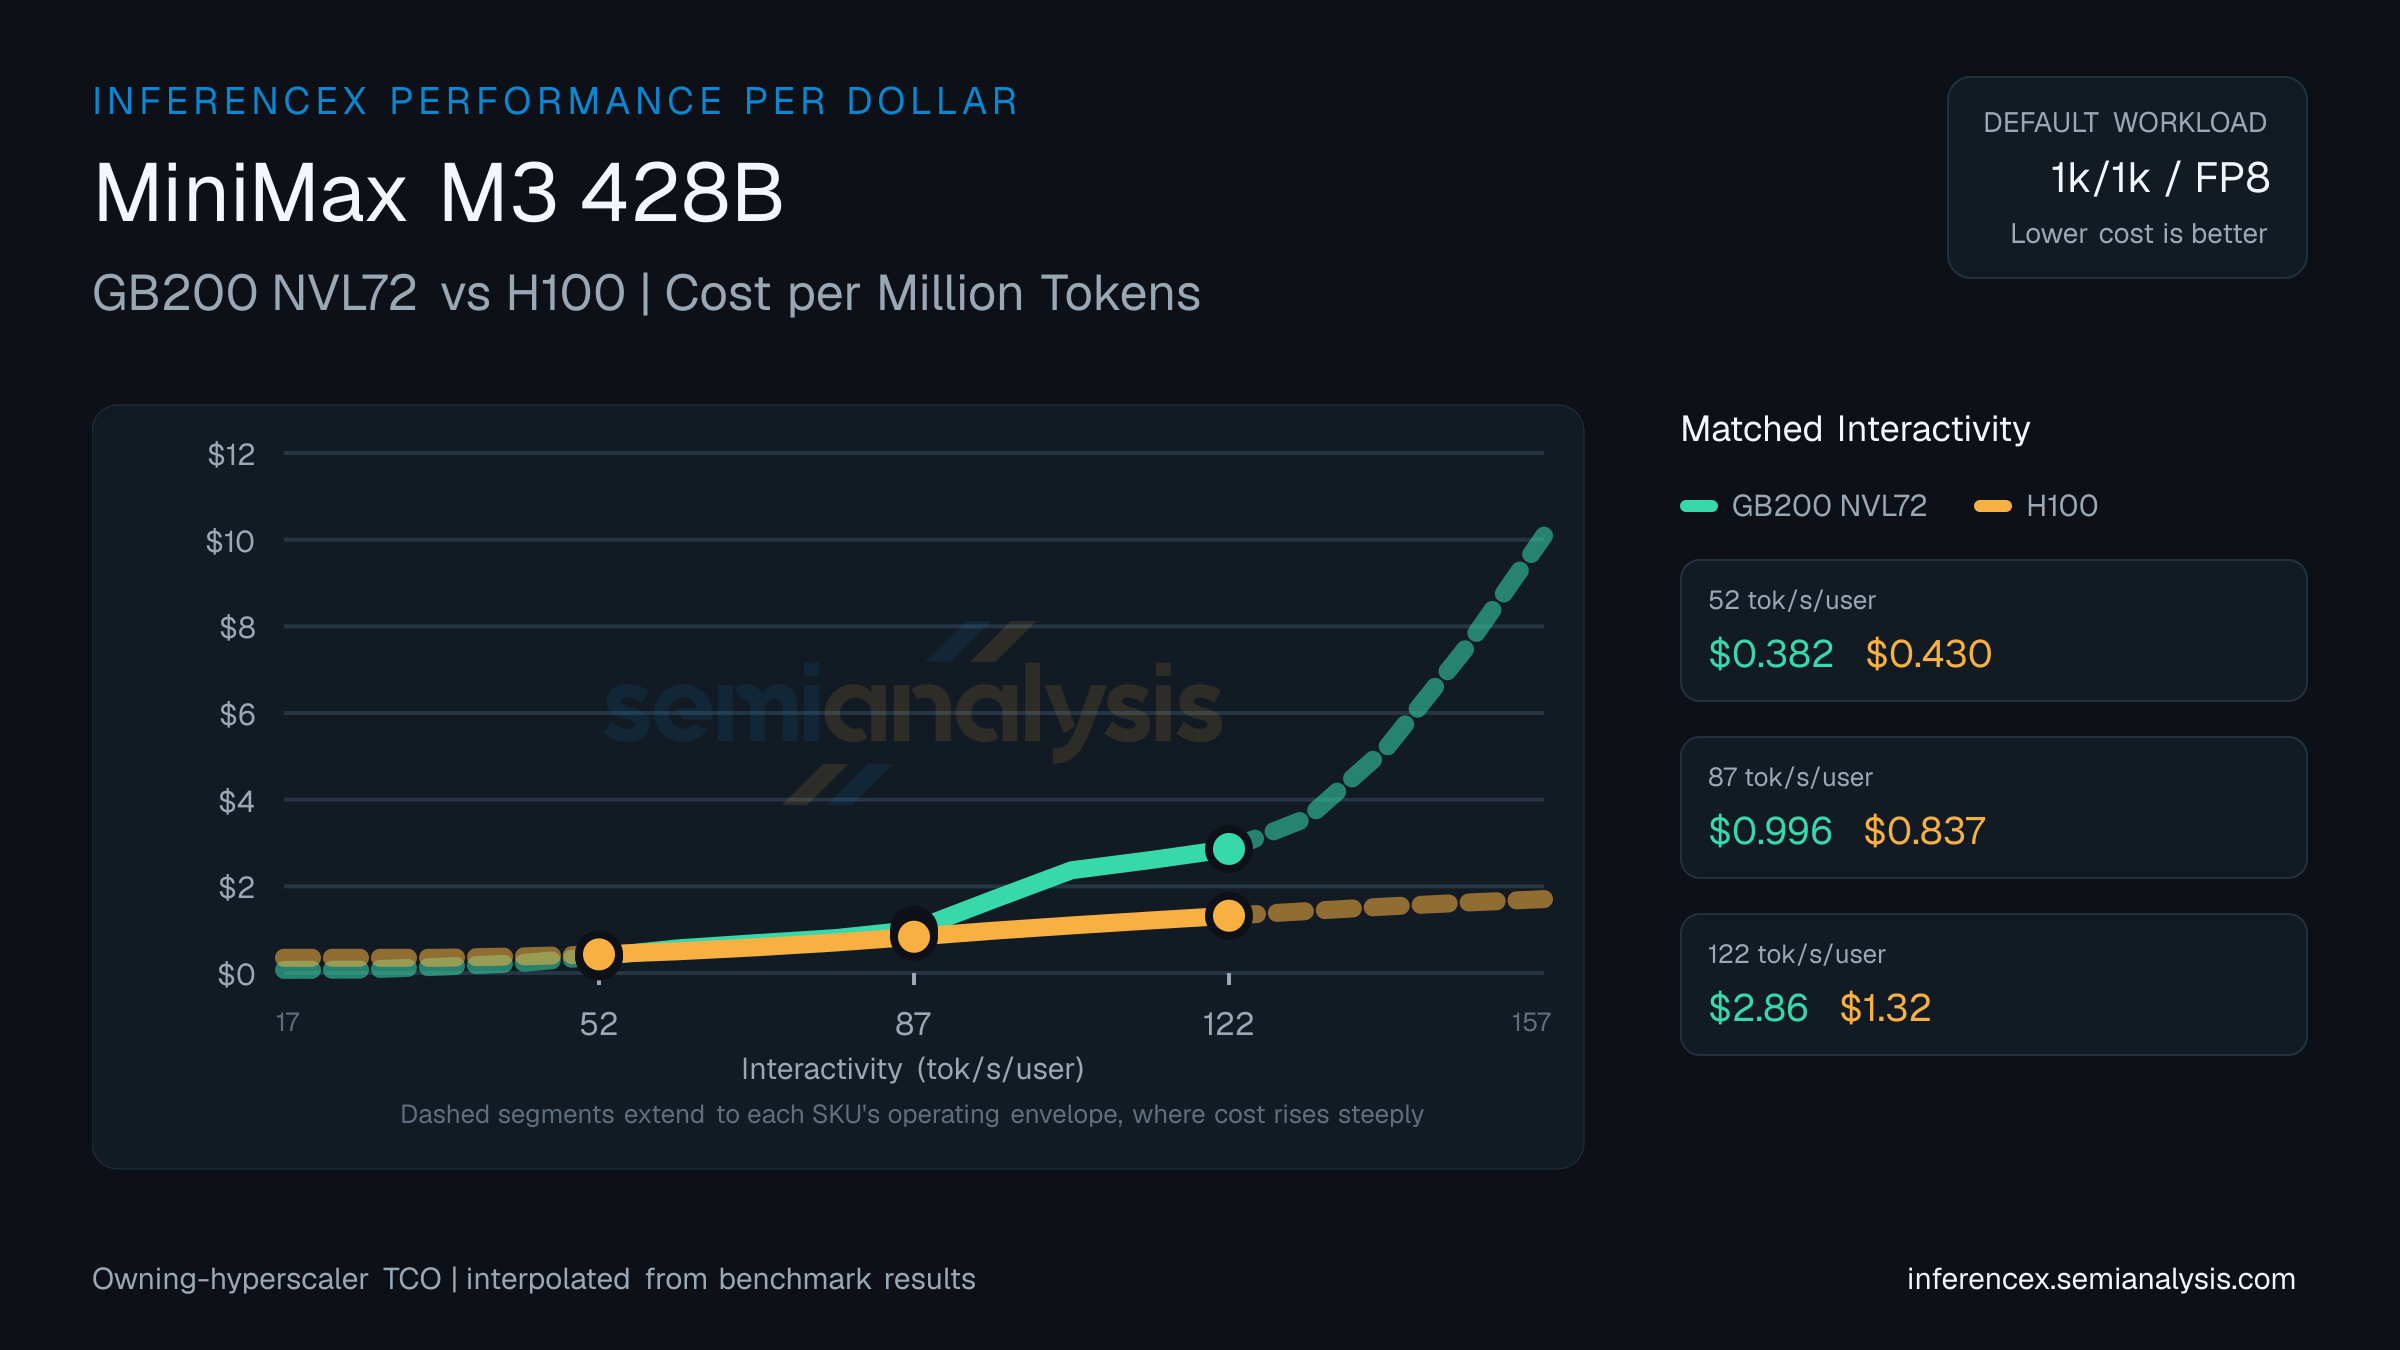
MiniMax M3 428B · Performance per dollar
MiniMax M3 428B — GB200 NVL72 vs H100 performance per dollar
Cost per million tokens of GB200 NVL72 (NVIDIA Blackwell) versus H100 (NVIDIA Hopper) on MiniMax M3 428B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
Only GB200 NVL72 has cost data at 168 tok/s/user on MiniMax M3 428B — $0.015 per million tokens. H100 is unmeasured at this target.
GB200 NVL72 costs $0.032 per million tokens at 253 tok/s/user on MiniMax M3 428B; we have no H100 benchmark data at this exact target.
At 338 tok/s/user on MiniMax M3 428B, GB200 NVL72 comes in at $0.063 per million tokens. H100 hasn't been benchmarked at this operating point. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): GB200 NVL72 $1.86/chip/hr · H100 $1.17/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollars per million tokens | GB200 NVL72$0.015H100— | GB200 NVL72$0.032H100— | GB200 NVL72$0.063H100— |
| Concurrency | GB200 NVL72~19H100— | GB200 NVL72~9H100— | GB200 NVL72~2H100— |