
gpt-oss 120B — H100 vs Jalapeño Performance per Dollar
Cost per million tokens of H100 (NVIDIA Hopper) versus Jalapeño (OpenAI Jalapeño) on gpt-oss 120B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
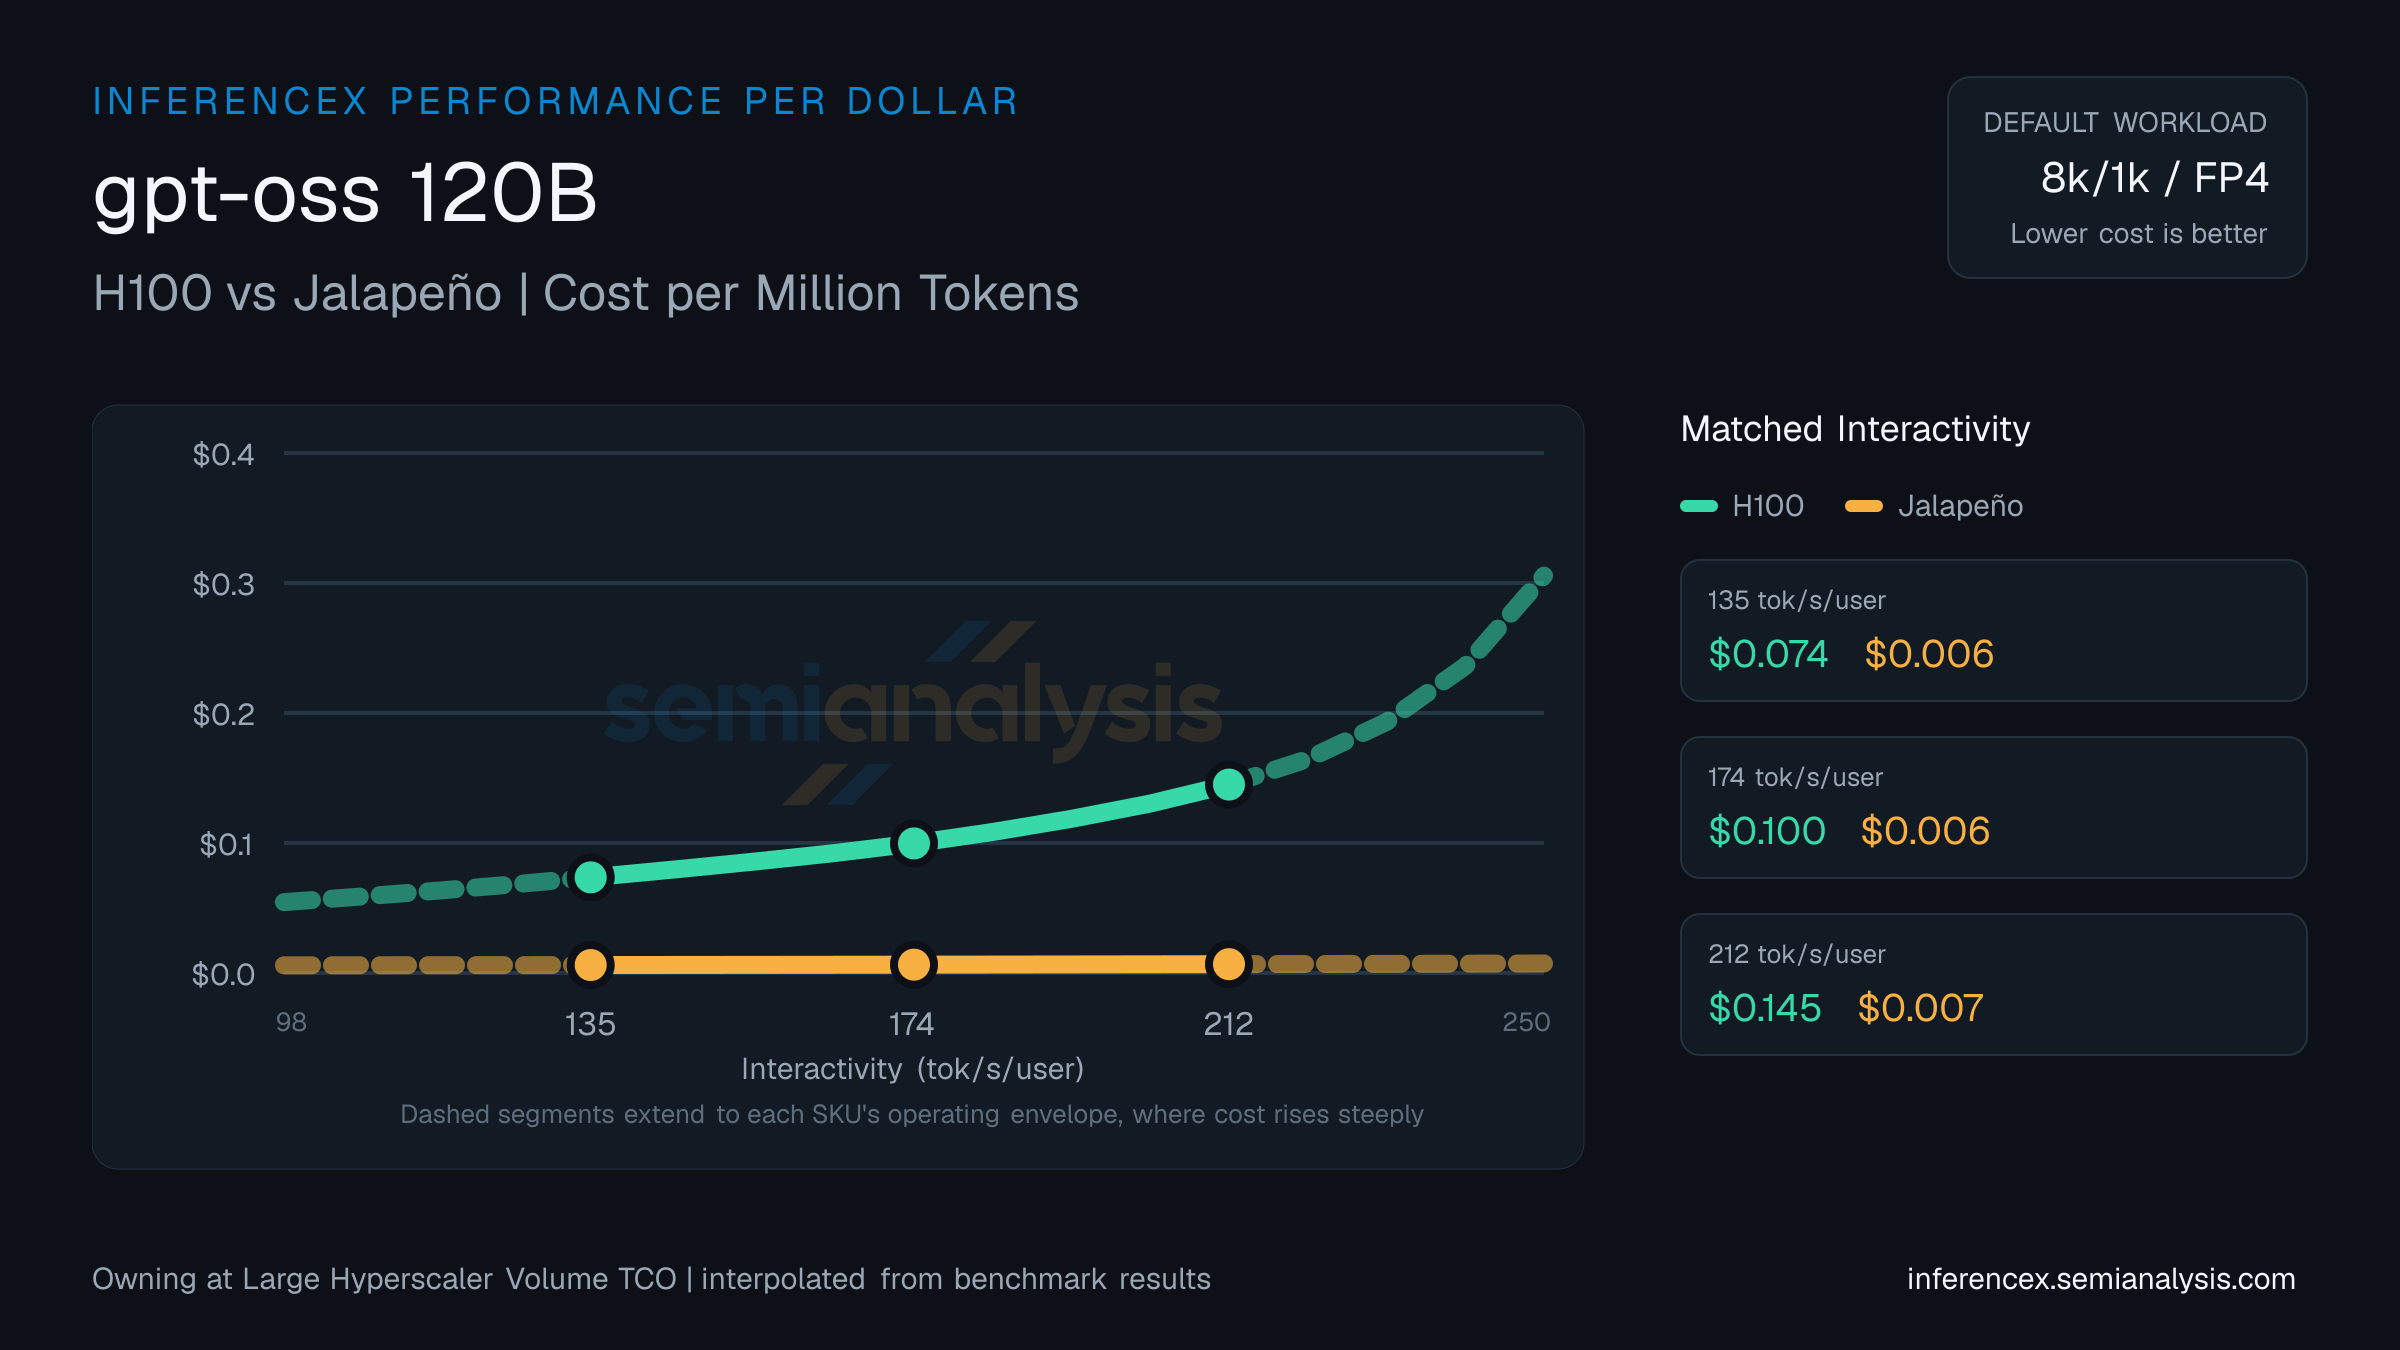
Near the low end of the 98–250 tok/s/user interactivity band — at 135 tok/s/user — H100 runs $0.07 per million tokens on gpt-oss 120B while Jalapeño runs $0.01. Jalapeño is the cheaper choice by 1102%.
On gpt-oss 120B at 174 tok/s/user, the per-million math comes out to $0.10 for H100 and $0.01 for Jalapeño; Jalapeño delivers 1455% more total tokens per dollar.
At 212 tok/s/user on gpt-oss 120B, H100 costs $0.14 per million tokens; Jalapeño costs $0.01. Jalapeño is 2038% more cost-efficient at this operating point. (Numbers reflect the default 8k/1k · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): H100 $1.17/chip/hr · Jalapeño $1.27/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | H100:$0.074Jalapeño:$0.006 | H100:$0.100Jalapeño:$0.006 | H100:$0.145Jalapeño:$0.007 |
| Concurrency | H100:~15Jalapeño:~1349 | H100:~9Jalapeño:~845 | H100:~4Jalapeño:~607 |