
DeepSeek V4.1 Flash 552B — MI300X vs MI355X Performance per Dollar
Cost per million tokens of MI300X (AMD CDNA 3) versus MI355X (AMD CDNA 4) on DeepSeek V4.1 Flash 552B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
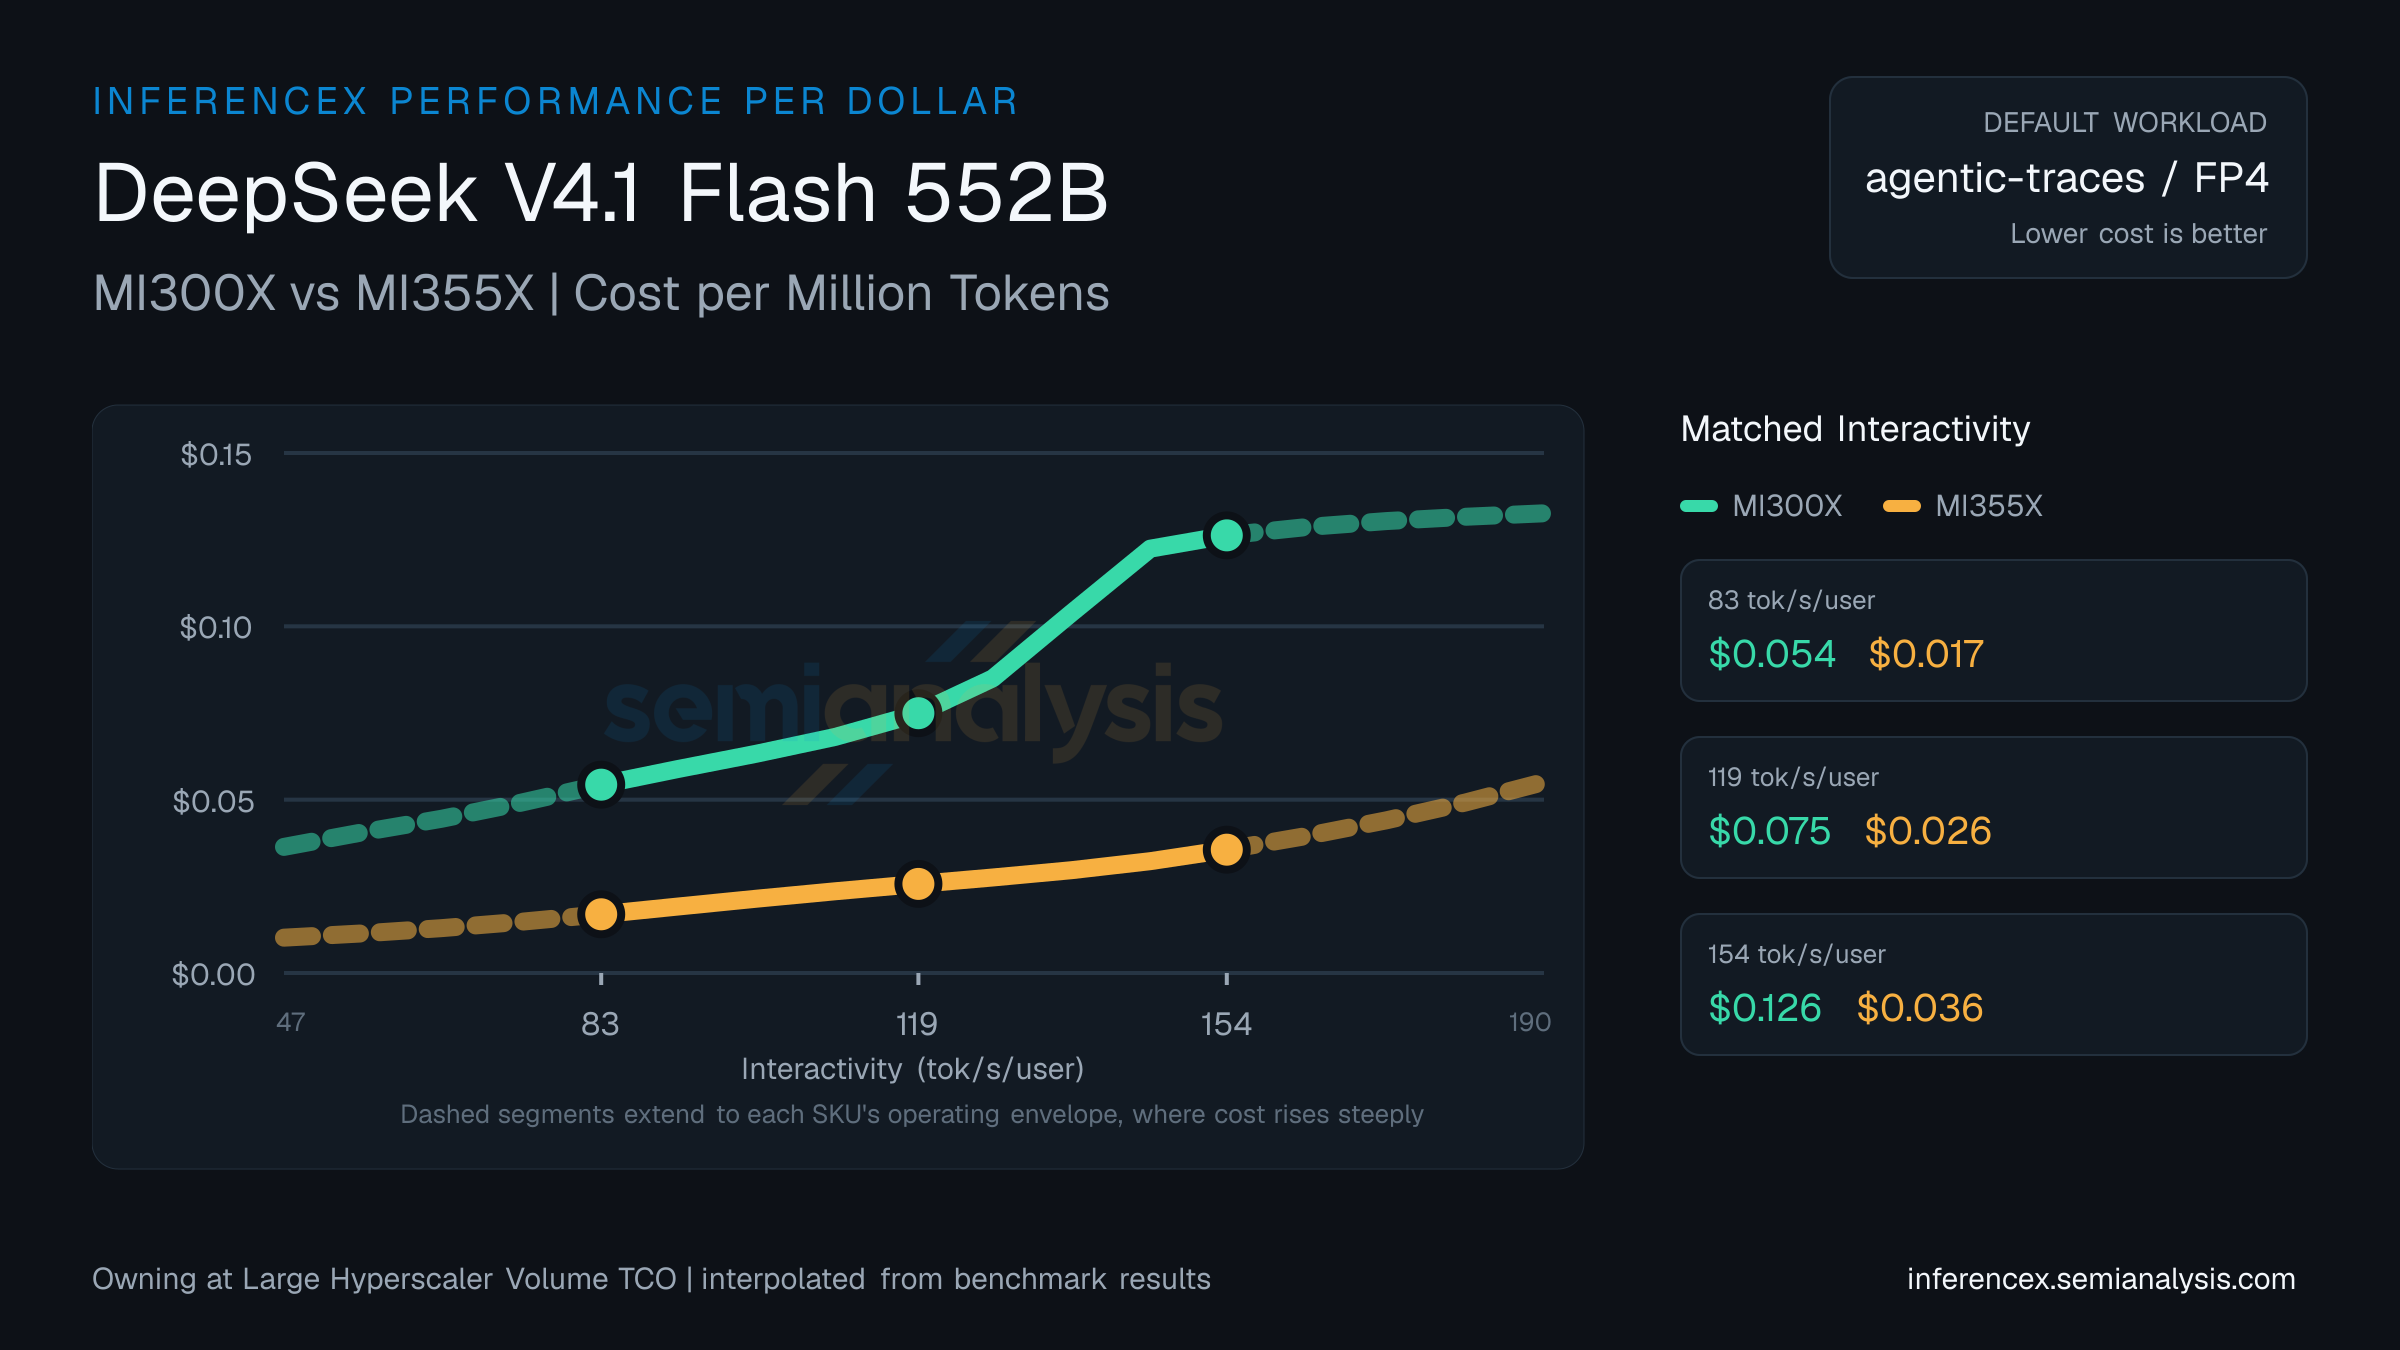
MI355X edges MI300X at 83 tok/s/user on DeepSeek V4.1 Flash 552B — $0.02 per million tokens versus $0.05, a 221% cost-per-token gap.
Push DeepSeek V4.1 Flash 552B to 119 tok/s/user and MI300X lands at $0.07 per million tokens against MI355X's $0.03 — MI355X pulls ahead by 192%.
MI300X: $0.13 per million tokens. MI355X: $0.04. Both at 154 tok/s/user on DeepSeek V4.1 Flash 552B, with MI355X 255% cheaper. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): MI300X $0.95/chip/hr · MI355X $1.50/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | MI300X:$0.054MI355X:$0.017 | MI300X:$0.075MI355X:$0.026 | MI300X:$0.126MI355X:$0.036 |
| Concurrency | MI300X:~7MI355X:~17 | MI300X:~4MI355X:~11 | MI300X:~2MI355X:~7 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.