
DeepSeekv4 Pro 0813 1.6T — MI325X vs Vera Rubin NVL72 Performance per Dollar
Cost per million tokens of MI325X (AMD CDNA 3) versus Vera Rubin NVL72 (NVIDIA Vera Rubin) on DeepSeekv4 Pro 0813 1.6T. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
At 12 tok/s/user on DeepSeekv4 Pro 0813 1.6T, MI325X comes in at $0.79 per million tokens. Vera Rubin NVL72 hasn't been benchmarked at this operating point.
Only MI325X has cost data at 19 tok/s/user on DeepSeekv4 Pro 0813 1.6T — $1.47 per million tokens. Vera Rubin NVL72 is unmeasured at this target.
MI325X costs $2.95 per million tokens at 26 tok/s/user on DeepSeekv4 Pro 0813 1.6T; we have no Vera Rubin NVL72 benchmark data at this exact target. (Numbers reflect the default 1k/1k · fp8 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): MI325X $1.10/chip/hr · Vera Rubin NVL72 $3.61/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
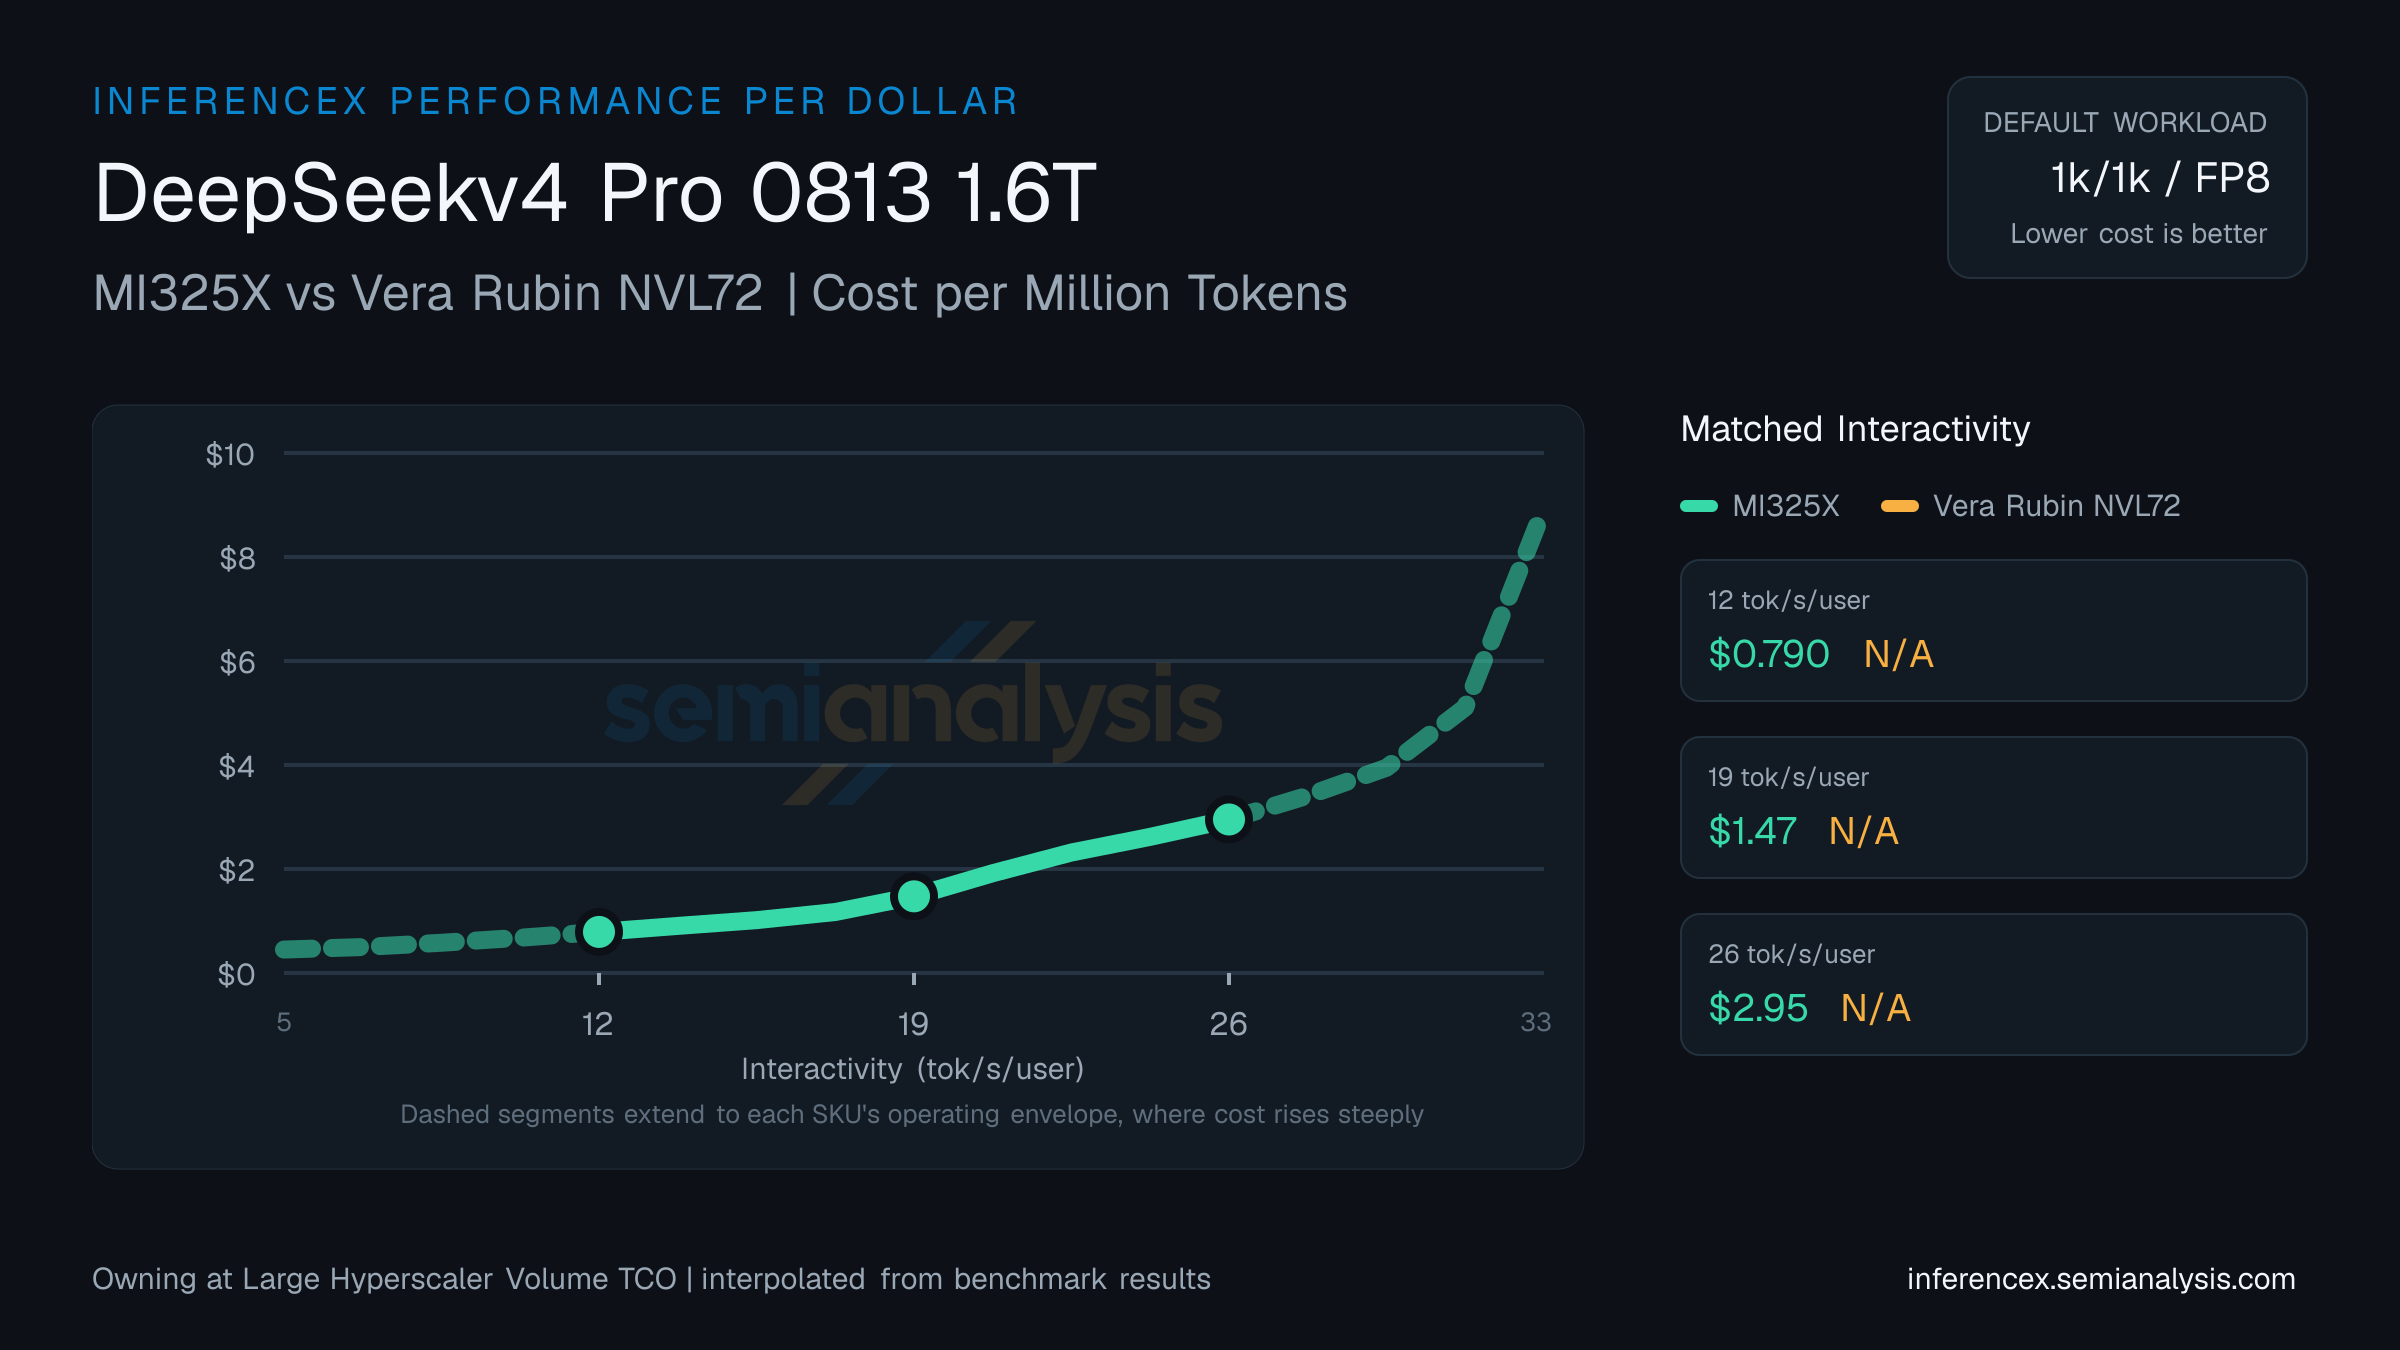
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | MI325X:$0.790Vera Rubin NVL72:— | MI325X:$1.474Vera Rubin NVL72:— | MI325X:$2.952Vera Rubin NVL72:— |
| Concurrency | MI325X:~136Vera Rubin NVL72:— | MI325X:~46Vera Rubin NVL72:— | MI325X:~16Vera Rubin NVL72:— |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
 DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.
Shift+Scroll to zoom • Drag to pan • Double-click to reset • Click a point to pin tooltip