DeepSeekv4 Pro 0813 1.6T — MI300X vs MI325X Performance per Dollar
Cost per million tokens of MI300X (AMD CDNA 3) versus MI325X (AMD CDNA 3) on DeepSeekv4 Pro 0813 1.6T. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
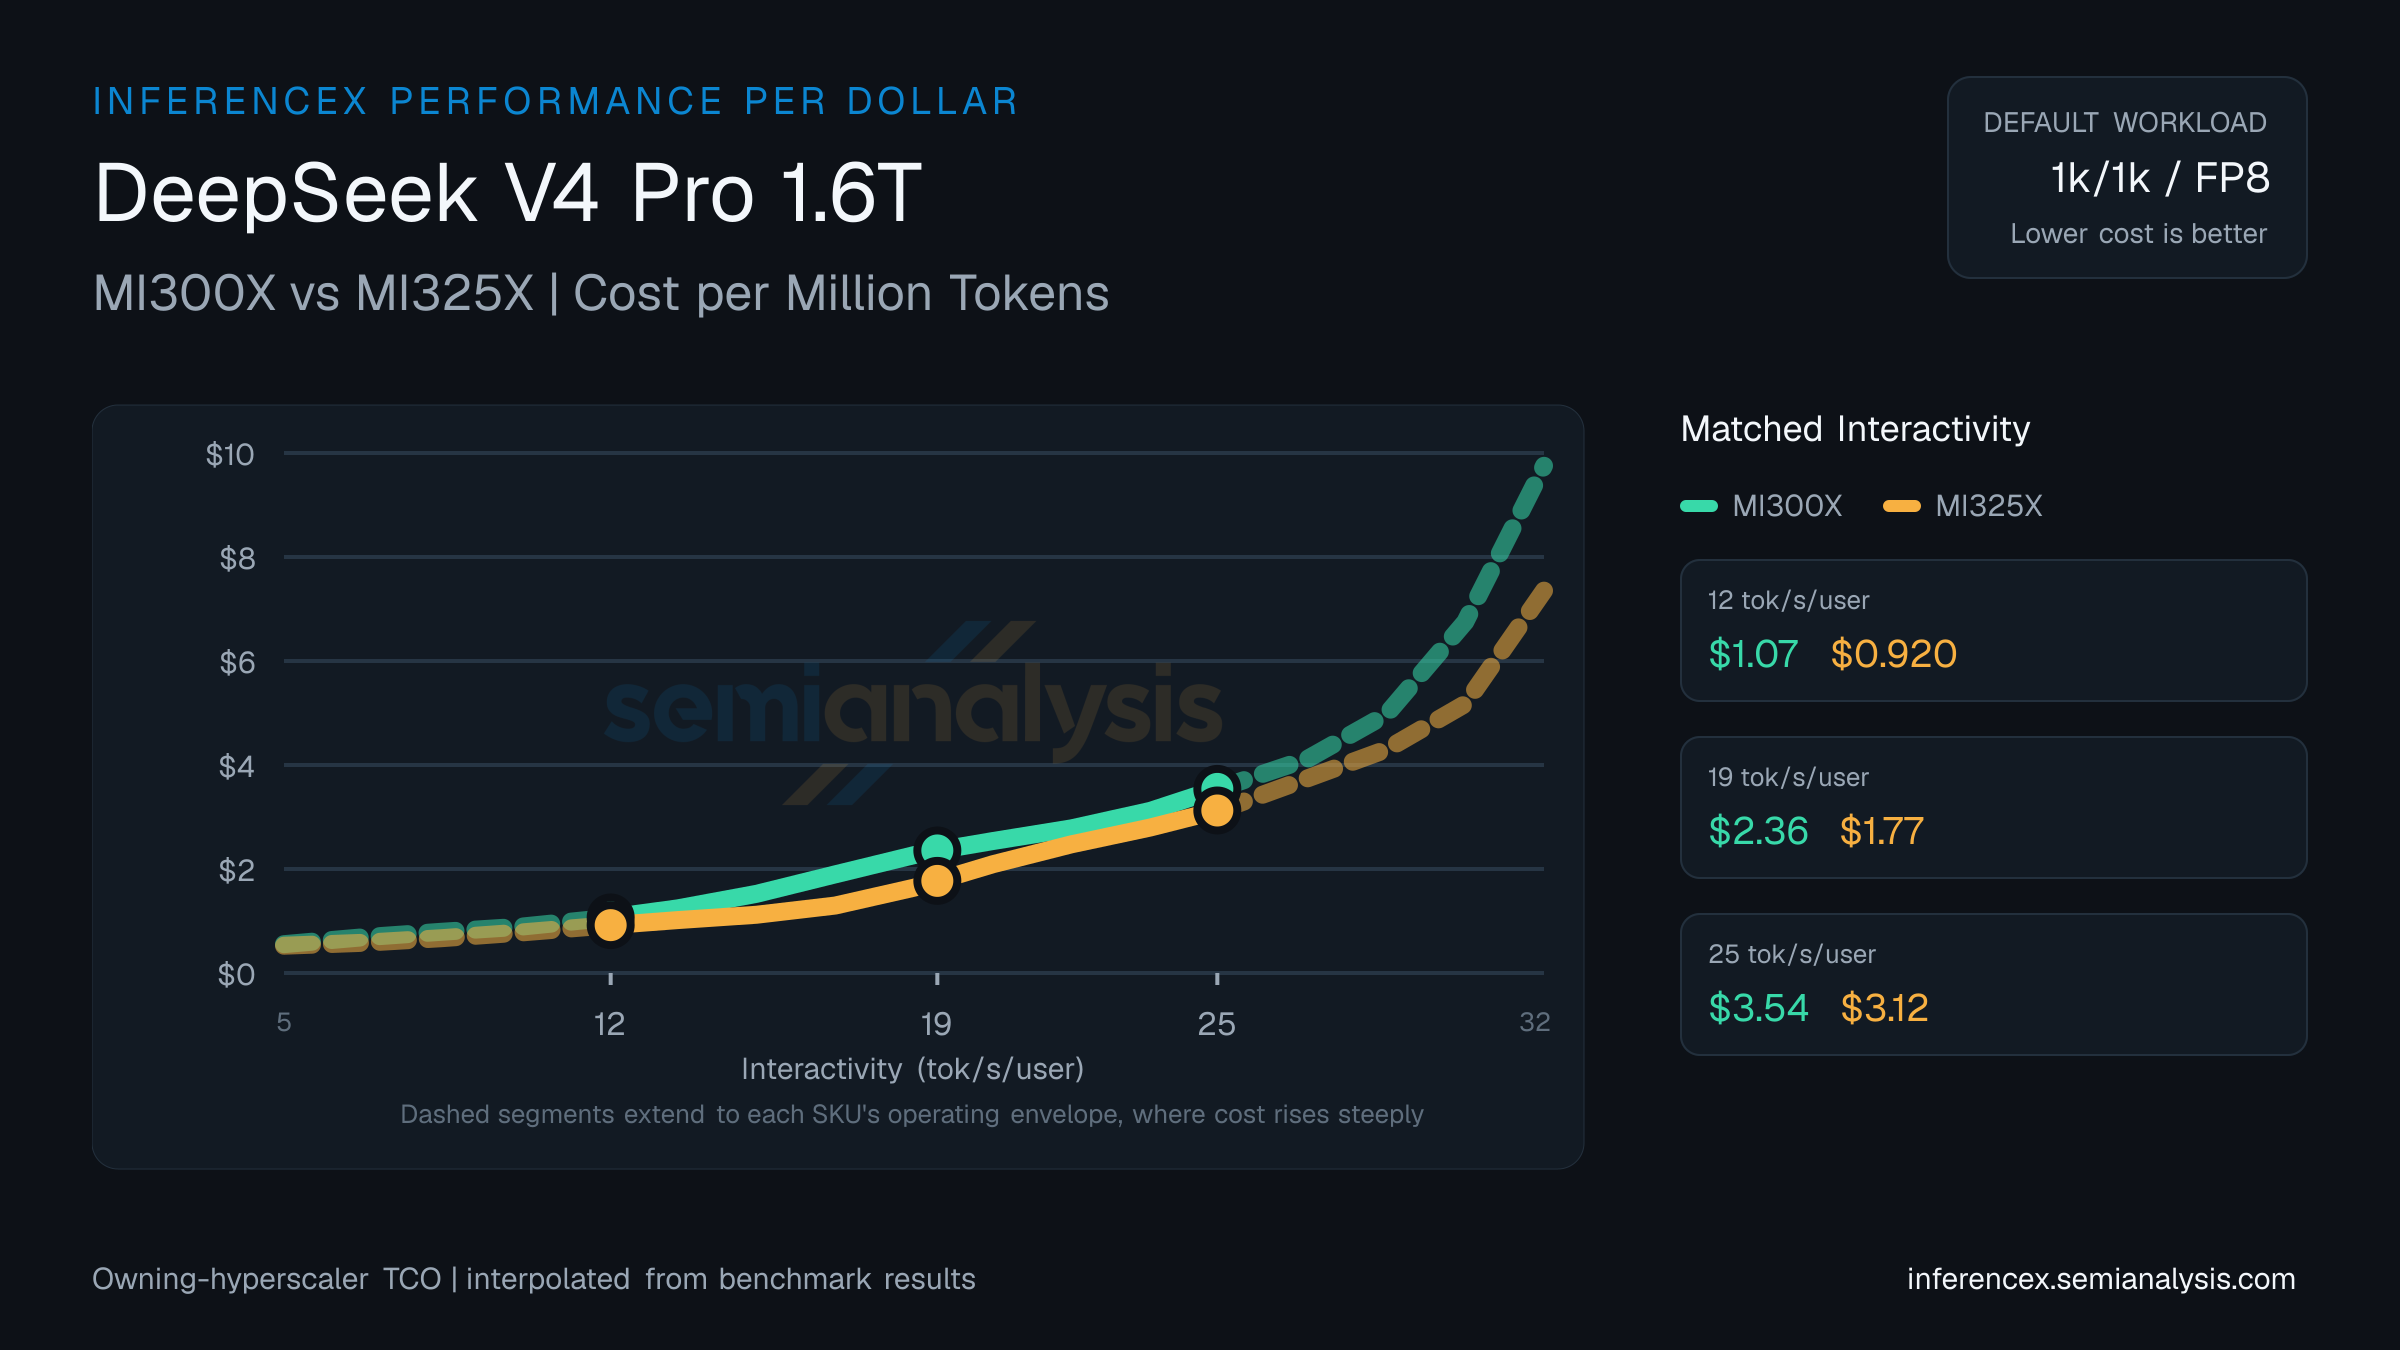
MI300X: $0.90 per million tokens. MI325X: $0.79. Both at 12 tok/s/user on DeepSeekv4 Pro 0813 1.6T, with MI325X 14% cheaper.
Around the middle of the 5–32 tok/s/user interactivity band — at 19 tok/s/user — MI300X runs $2.03 per million tokens on DeepSeekv4 Pro 0813 1.6T while MI325X runs $1.47. MI325X is the cheaper choice by 38%.
On DeepSeekv4 Pro 0813 1.6T at 25 tok/s/user, the per-million math comes out to $2.99 for MI300X and $2.74 for MI325X; MI325X delivers 9% more total tokens per dollar. (Numbers reflect the default 1k/1k · fp8 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): MI300X $0.95/chip/hr · MI325X $1.10/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | MI300X:$0.903MI325X:$0.790 | MI300X:$2.030MI325X:$1.474 | MI300X:$2.992MI325X:$2.743 |
| Concurrency | MI300X:~101MI325X:~136 | MI300X:~29MI325X:~46 | MI300X:~15MI325X:~18 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
 DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.
Shift+Scroll to zoom • Drag to pan • Double-click to reset • Click a point to pin tooltip