DeepSeekv4 Pro 0813 1.6T — B200 vs GB300 NVL72 Performance per Dollar
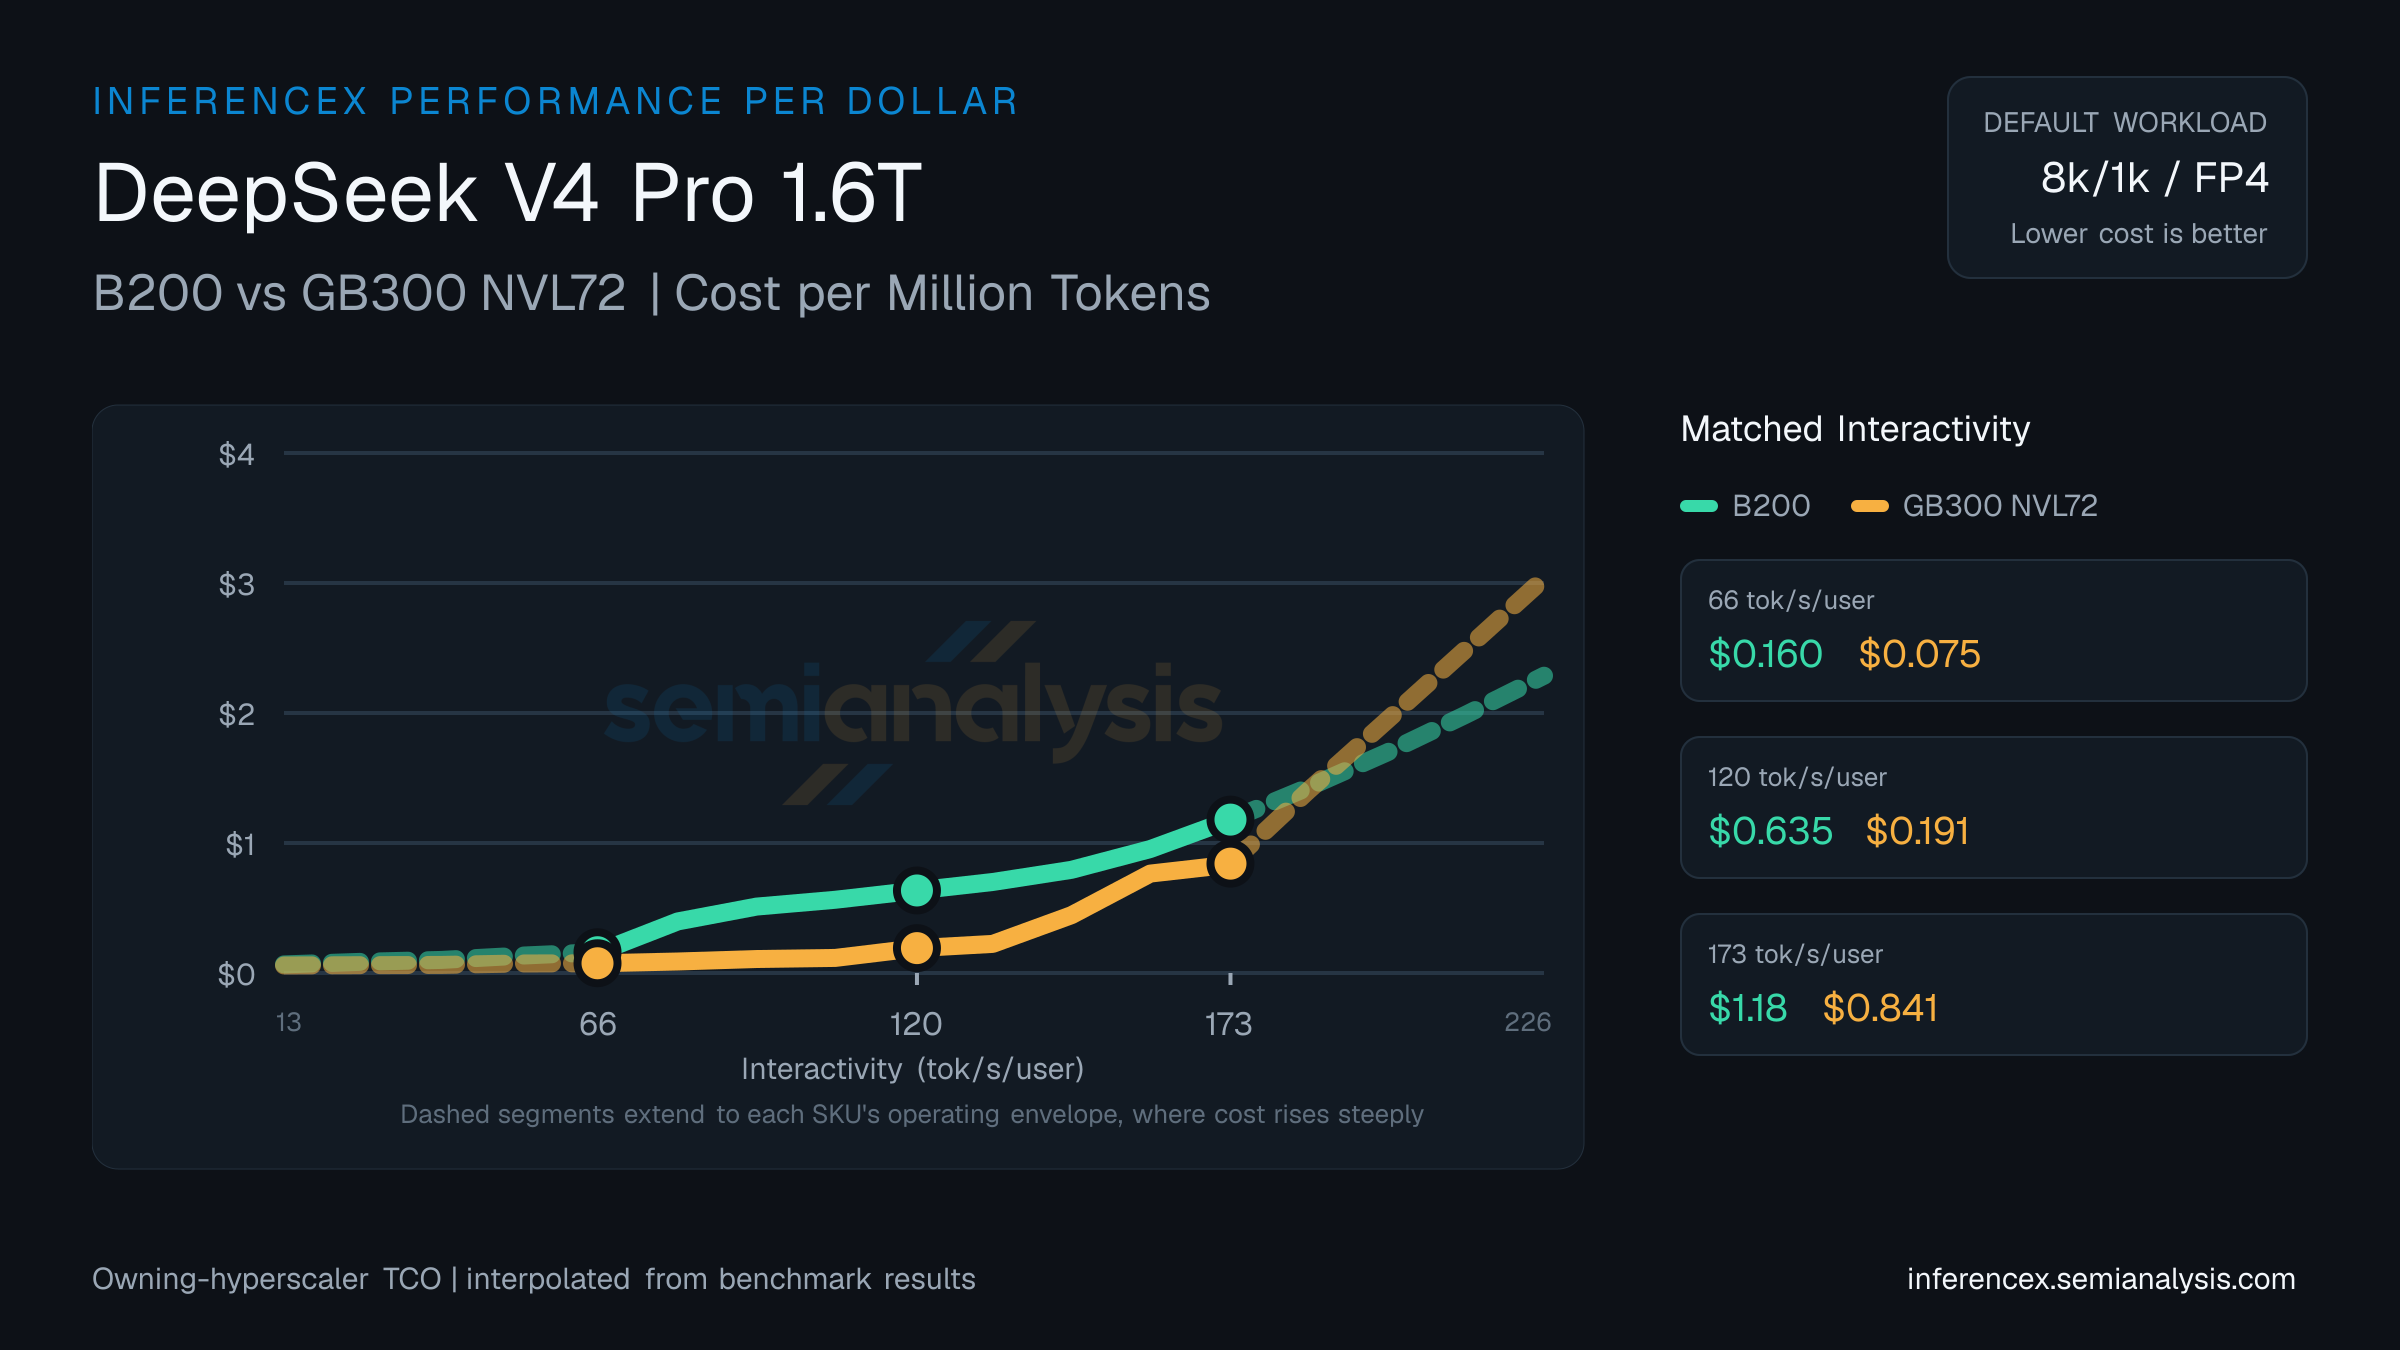
Cost per million tokens of B200 (NVIDIA Blackwell) versus GB300 NVL72 (NVIDIA Blackwell) on DeepSeekv4 Pro 0813 1.6T. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
On DeepSeekv4 Pro 0813 1.6T at 66 tok/s/user, the per-million math comes out to $0.07 for B200 and $0.07 for GB300 NVL72; GB300 NVL72 delivers 12% more total tokens per dollar.
At 120 tok/s/user on DeepSeekv4 Pro 0813 1.6T, B200 costs $0.32 per million tokens; GB300 NVL72 costs $0.16. GB300 NVL72 is 91% more cost-efficient at this operating point.
GB300 NVL72 edges B200 at 173 tok/s/user on DeepSeekv4 Pro 0813 1.6T — $0.72 per million tokens versus $0.79, a 11% cost-per-token gap. (Numbers reflect the default 8k/1k · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): B200 $1.73/chip/hr · GB300 NVL72 $2.31/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | B200:$0.073GB300 NVL72:$0.065 | B200:$0.315GB300 NVL72:$0.165 | B200:$0.795GB300 NVL72:$0.717 |
| Concurrency | B200:~935GB300 NVL72:~1026 | B200:~133GB300 NVL72:~320 | B200:~32GB300 NVL72:~29 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
 DeepSeek V4 Pro 0813 1.6T 8K / 1K Cost per Million Total Tokens vs. Interactivity
- Cost Tier:
- Source:
- SemiAnalysis InferenceX™
TCO $/chip/hr:
Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate cost per million tokens per decode chip or per prefill chip, rather than per total chip count. This makes direct token cost comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate input throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct input throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate output throughput per decode chip or per prefill chip, rather than per total chip count. This makes direct output throughput comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate power per decode chip or per prefill chip, rather than per total chip count. This makes direct power comparison with aggregated configs not an apples-to-apples comparison.
Note: Disaggregated inference configurations (e.g., MoRI SGLang, Dynamo TRTLLM) calculate Joules per decode chip or per prefill chip, rather than per total chip count. This makes direct Joules per token comparison with aggregated configs not an apples-to-apples comparison.
No data available
Matching measurements exist, but their chip series are hidden.
Shift+Scroll to zoom • Drag to pan • Double-click to reset • Click a point to pin tooltip