Qwen 3.5 397B-A17B · Speculative decoding
TPU7x FP8: MTP vs Off speculative decoding
Speculative decoding comparison of MTP versus Off on TPU7x FP8 (Google Ironwood) running Qwen 3.5 397B-A17B. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
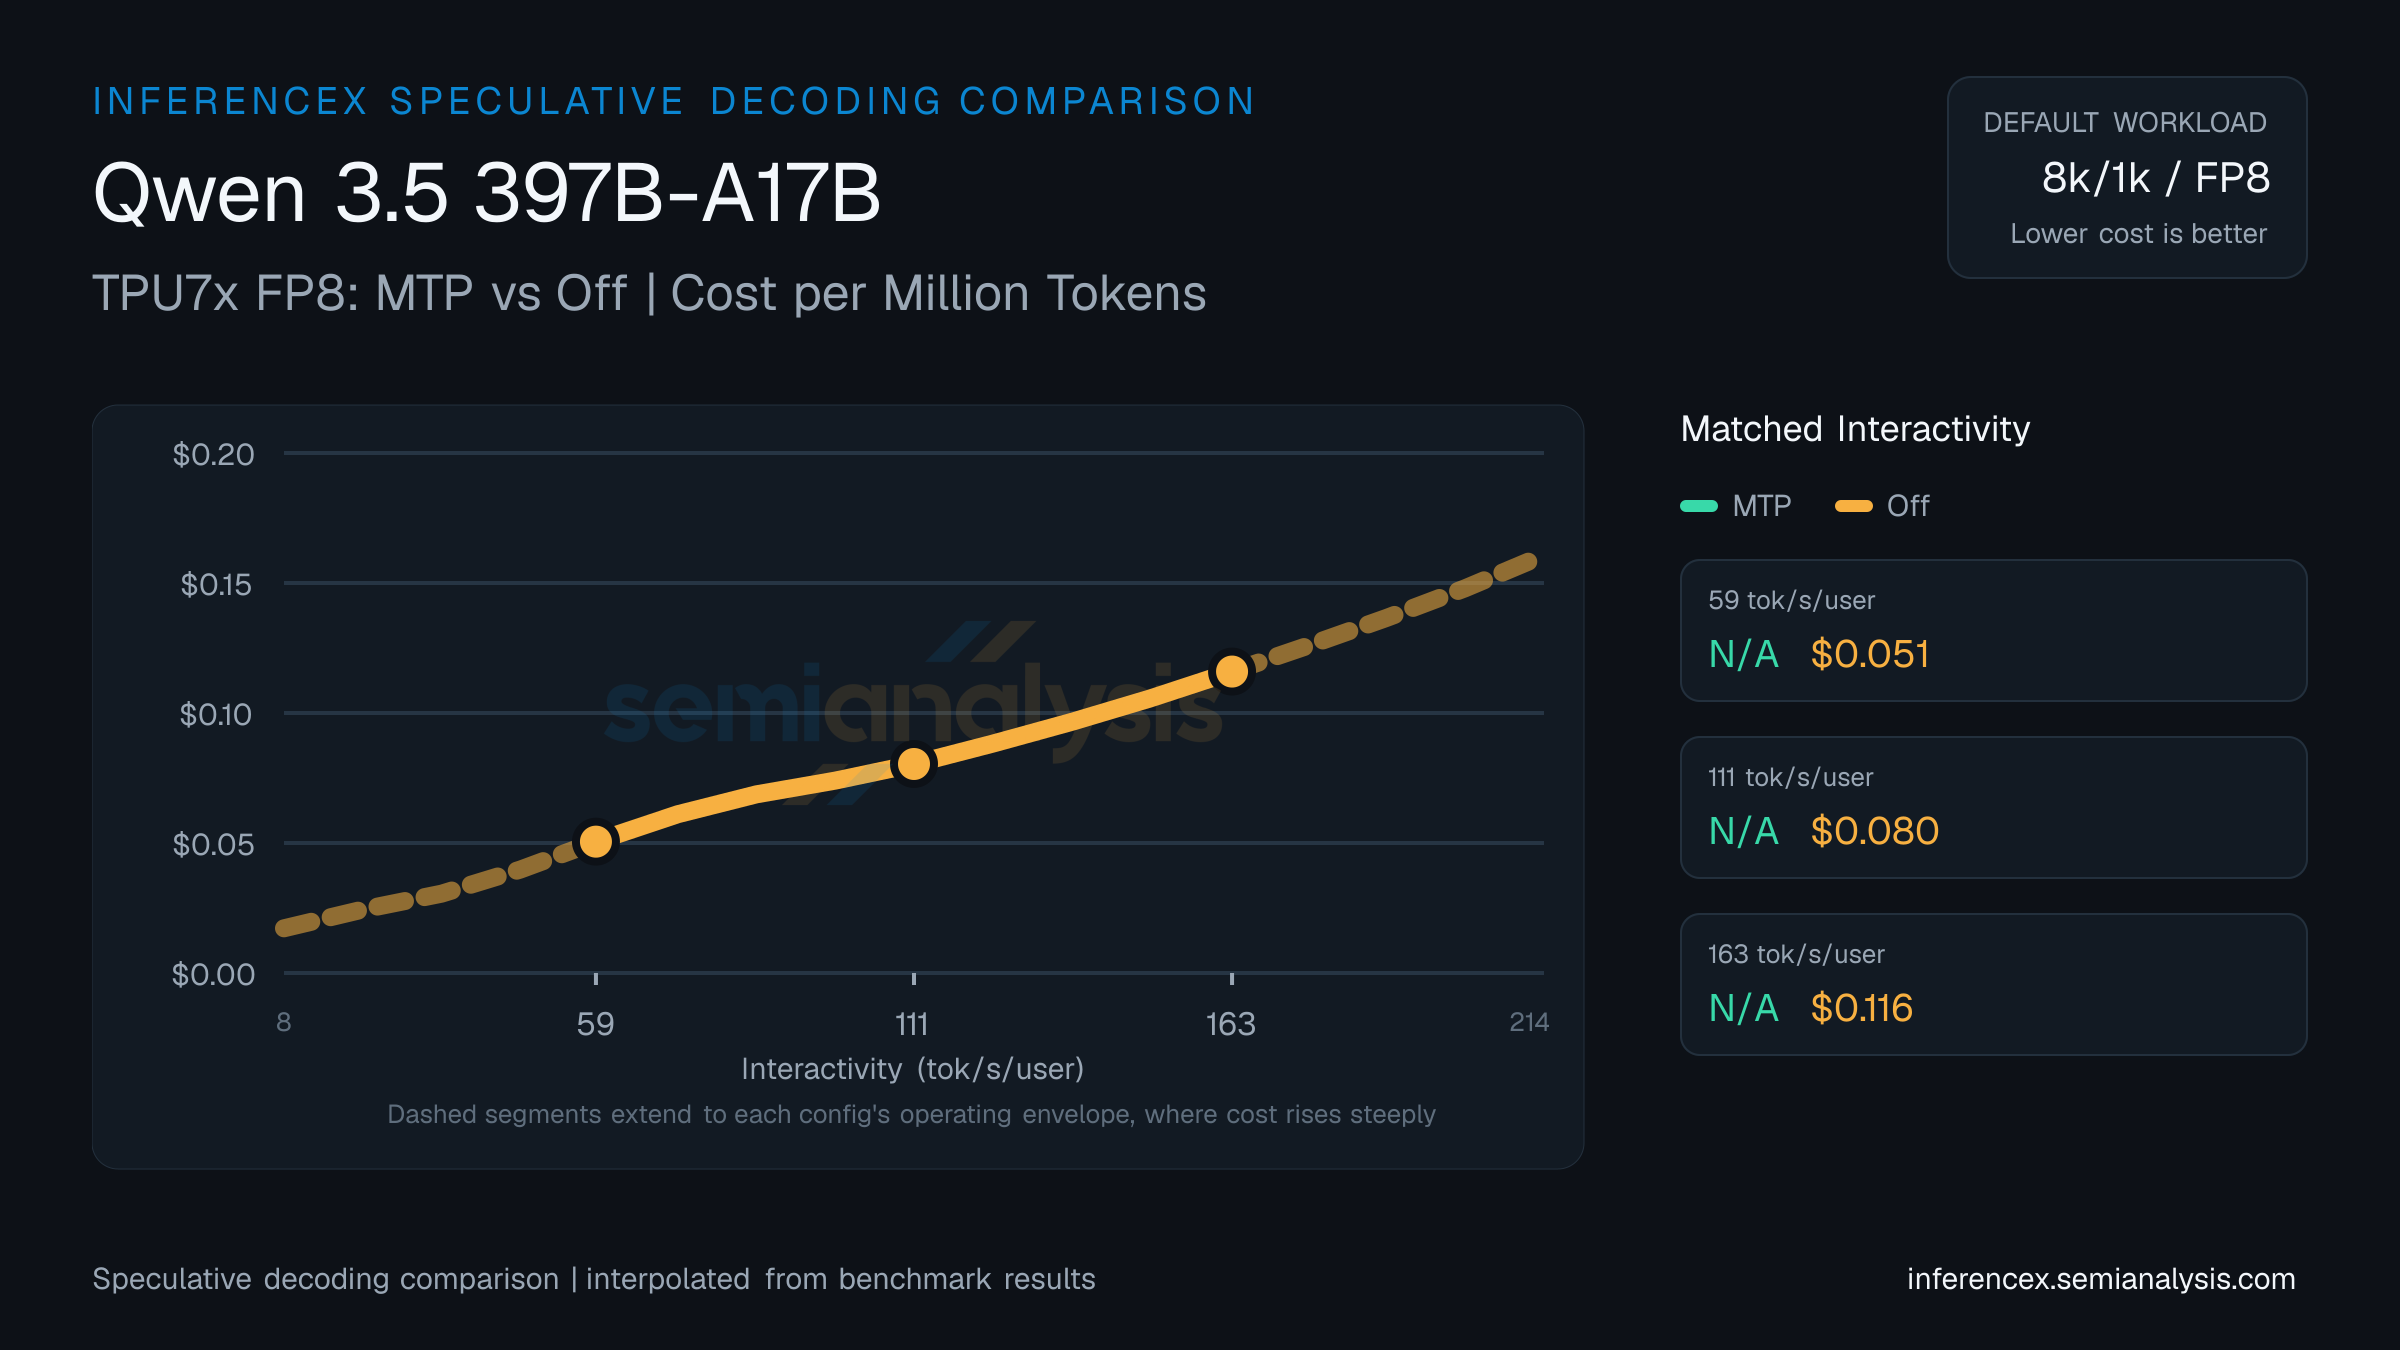
Off: 5,664 tok/s/chip, $0.051 per million tokens at 59 tok/s/user on Qwen 3.5 397B-A17B (TPU7x FP8). MTP is unmeasured here.
At 111 tok/s/user on Qwen 3.5 397B-A17B (TPU7x FP8), Off delivers 3,559 tok/s/chip at $0.080 per million tokens; MTP hasn't been benchmarked at this target.
Off hits 2,468 tok/s/chip for $0.12 per million tokens at 163 tok/s/user on Qwen 3.5 397B-A17B (TPU7x FP8). No MTP data at this operating point. (Numbers reflect this URL's pinned 8k/1k · fp8 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP—Off5,664 | MTP—Off3,559 | MTP—Off2,468 |
| Cost ($/M tok) | MTP—Off$0.051 | MTP—Off$0.080 | MTP—Off$0.12 |
| tok/s/MW | MTP—Off4,692,296 | MTP—Off2,948,752 | MTP—Off2,044,583 |
| Concurrency | MTP—Off~45 | MTP—Off~15 | MTP—Off~7 |