DeepSeek V4 Pro 0813 1.6T · Speculative decoding
B300 FP4: MTP vs Off speculative decoding
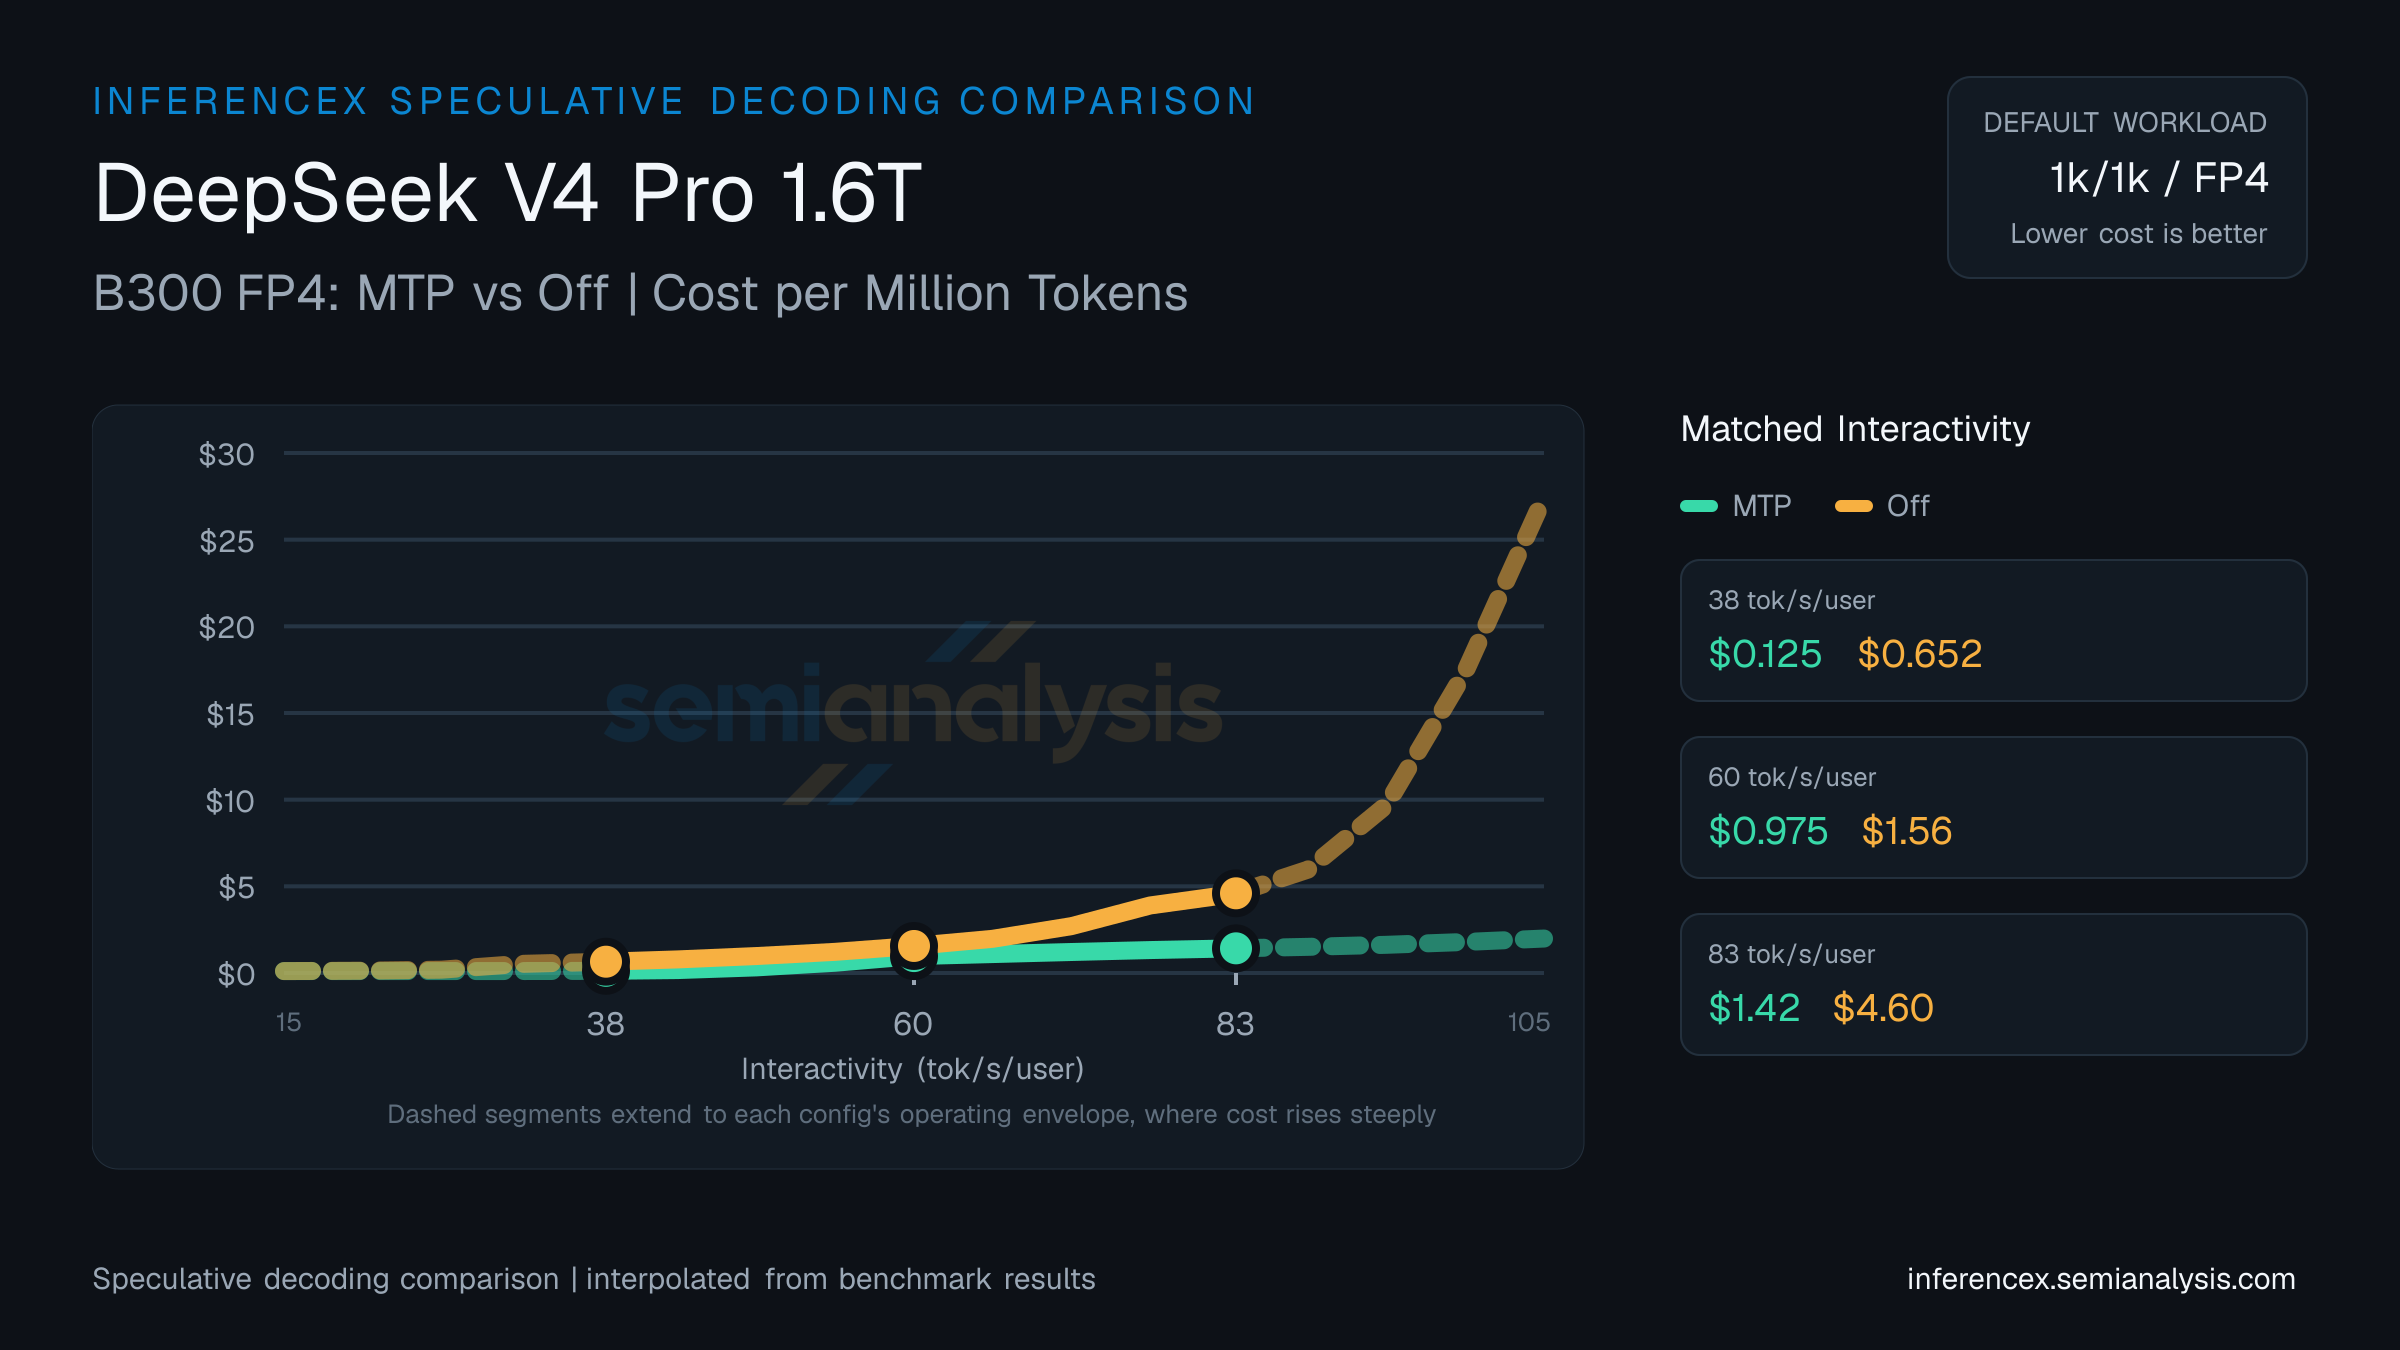
Speculative decoding comparison of MTP versus Off on B300 FP4 (NVIDIA Blackwell) running DeepSeek V4 Pro 0813 1.6T. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
Near the low end of the 13–105 tok/s/user interactivity band, at 36 tok/s/user on DeepSeek V4 Pro 0813 1.6T (B300 FP4): MTP runs 5,480 tok/s/chip at $0.11 per million tokens, Off runs 1,127 at $0.56. MTP delivers 4.9× the tok/s/chip on the same chip, which makes it 79% cheaper per token. Gains from speculative decoding vary by workload; short-output prompts tend to benefit less.
At 59 tok/s/user on DeepSeek V4 Pro 0813 1.6T (B300 FP4), MTP delivers 838 tok/s/chip at $0.75 per million tokens; Off delivers 520 tok/s/chip at $1.21. MTP delivers 61% more tok/s/chip on the same chip, which makes it 38% cheaper per token. Speculative decoding accepts draft tokens to reduce per-token latency — gains vary by workload and prompt distribution.
MTP posts 558 tok/s/chip for $1.13 per million tokens at 82 tok/s/user on DeepSeek V4 Pro 0813 1.6T (B300 FP4); Off posts 154 tok/s/chip for $4.07. MTP delivers 3.6× the tok/s/chip on the same chip, which makes it 72% cheaper per token. Draft-token acceptance rates determine whether speculative decoding helps or hurts at a given concurrency level. (Numbers reflect this URL's pinned 1k/1k · fp4 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP5,480Off1,127 | MTP838Off520 | MTP558Off154 |
| Cost ($/M tok) | MTP$0.11Off$0.56 | MTP$0.75Off$1.21 | MTP$1.13Off$4.07 |
| tok/s/MW | MTP2,884,337Off593,148 | MTP441,311Off273,741 | MTP293,607Off81,113 |
| Concurrency | MTP~907Off~65 | MTP~29Off~18 | MTP~14Off~4 |