
B200 FP4: MTP vs Off Speculative Decoding
Speculative decoding comparison of MTP versus Off on B200 FP4 (NVIDIA Blackwell) running DeepSeekv4 Pro 0813 1.6T. Throughput, cost, and interactivity differences across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
MTP acceptance-rate implementations differ across inference engines. Points from different engines are not directly comparable on the same curve — throughput and cost at matched interactivity may reflect engine-level differences rather than pure speculative decoding gains. Interpret cross-engine comparisons with caution.
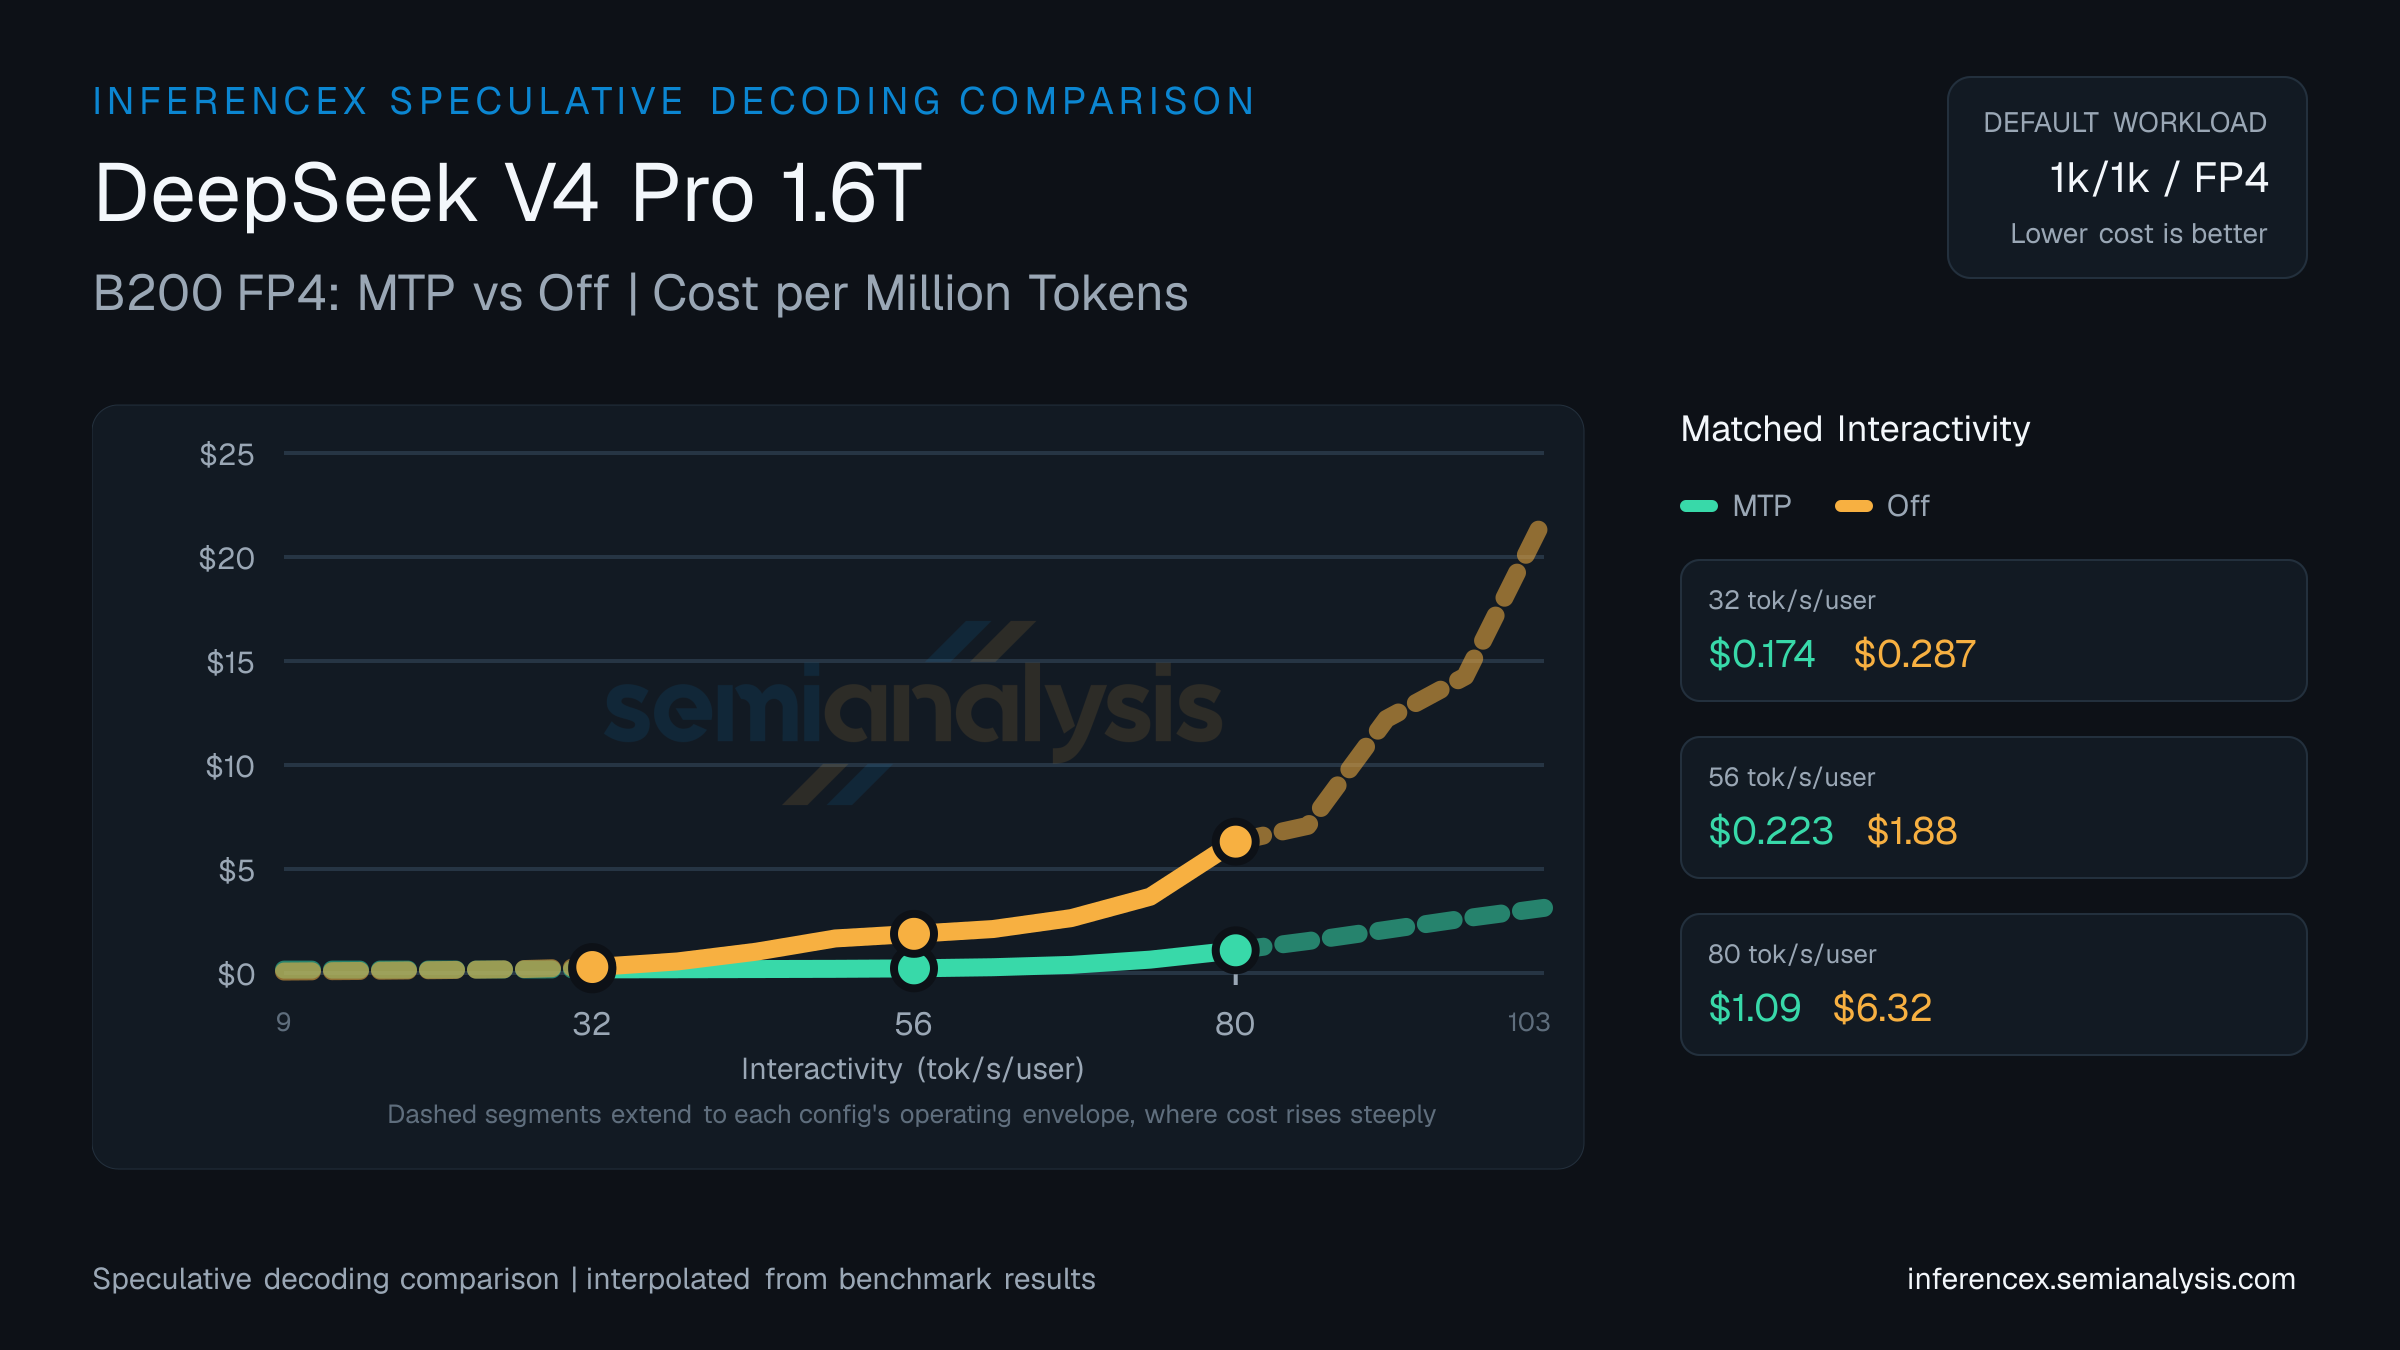
Throughput at 33 tok/s/user on DeepSeekv4 Pro 0813 1.6T (B200 FP4): MTP hits 7983 tok/s/chip, Off hits 7345. Per-million costs land at $0.06 and $0.07 respectively. MTP is 9% cheaper per token; MTP delivers 9% more tok/s/chip. Speculative decoding trades extra compute on draft tokens for fewer decoding steps — the payoff depends on sequence length and batch size.
Around the middle of the 10–103 tok/s/user interactivity band, at 57 tok/s/user on DeepSeekv4 Pro 0813 1.6T (B200 FP4): MTP runs 7698 tok/s/chip at $0.06/M tokens, Off runs 1640 at $0.29/M. MTP is 370% cheaper per token; MTP delivers 370% more tok/s/chip. Gains from speculative decoding vary by workload; short-output prompts tend to benefit less.
At 80 tok/s/user on DeepSeekv4 Pro 0813 1.6T (B200 FP4), MTP delivers 4008 tok/s/chip at $0.12 per million tokens; Off delivers 965 tok/s/chip at $0.50. MTP is 315% cheaper per token; MTP delivers 315% more tok/s/chip. Speculative decoding accepts draft tokens to reduce per-token latency — gains vary by workload and prompt distribution. (Numbers reflect this URL's pinned 8k/1k · fp4 workload — changing sequence or model updates both the table and chart; the table stays pinned to this page's precision, so precision toggles in the controls affect the chart only.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | MTP:7983.1Off:7345.0 | MTP:7697.7Off:1639.5 | MTP:4007.6Off:964.7 |
| Cost ($/M tok) | MTP:$0.060Off:$0.065 | MTP:$0.062Off:$0.293 | MTP:$0.120Off:$0.498 |
| tok/s/MW | MTP:4668477Off:4295314 | MTP:4501550Off:958773 | MTP:2343617Off:564176 |
| Concurrency | MTP:~6144Off:~1299 | MTP:~4202Off:~57 | MTP:~256Off:~60 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.