
B200: FP8 vs BF16 Precision Comparison
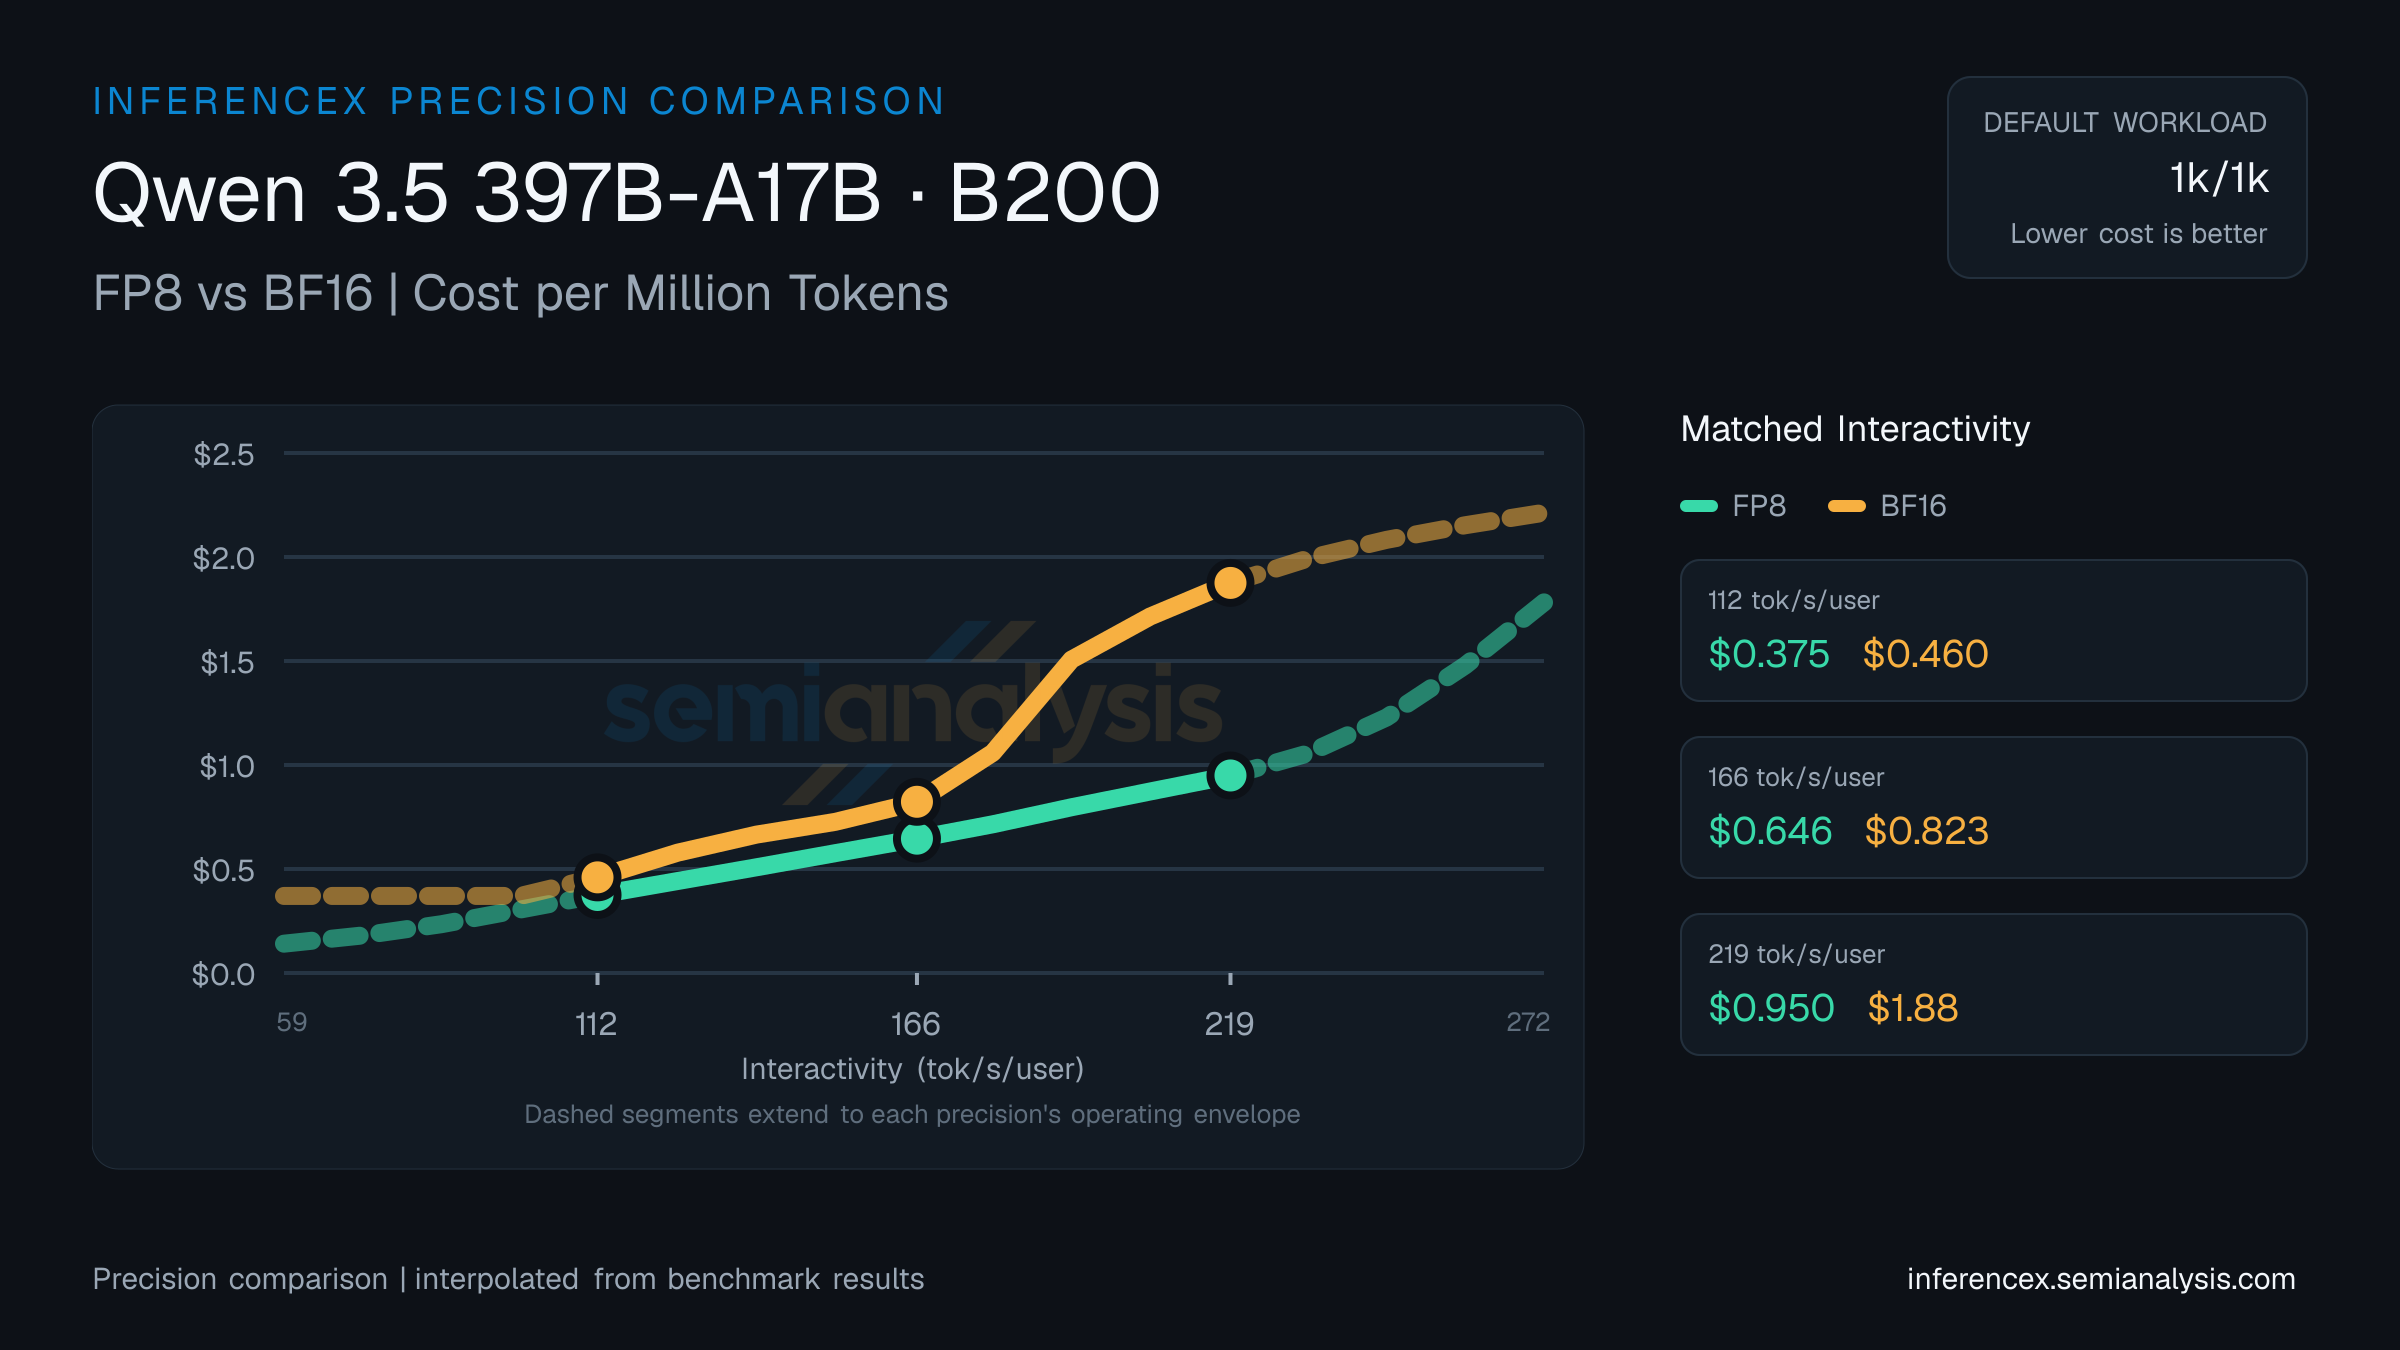
How FP8 and BF16 precision affect Qwen 3.5 397B-A17B inference on B200 (NVIDIA Blackwell). Throughput, latency, and cost across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
FP8 posts 4312 tok/s/chip for $0.11 per million tokens at 101 tok/s/user on Qwen 3.5 397B-A17B (B200); BF16 posts 3116 tok/s/chip for $0.15. FP8 is 38% cheaper per token; FP8 delivers 38% more tok/s/chip. Quantization-level accuracy differences are tracked on the evaluation tab.
Throughput at 157 tok/s/user on Qwen 3.5 397B-A17B (B200): FP8 hits 3050 tok/s/chip, BF16 hits 2011. Per-million costs land at $0.16 and $0.24 respectively. FP8 is 52% cheaper per token; FP8 delivers 52% more tok/s/chip. The cost-throughput tradeoff from lower precision is only part of the picture — see the evaluation page for accuracy data.
Toward the upper edge of the 47–267 tok/s/user interactivity band, at 212 tok/s/user on Qwen 3.5 397B-A17B (B200): FP8 runs 2233 tok/s/chip at $0.22/M tokens, BF16 runs 1296 at $0.37/M. FP8 is 72% cheaper per token; FP8 delivers 72% more tok/s/chip. Precision changes affect both inference speed and model quality — consult the evaluation tab for accuracy benchmarks. (Numbers reflect the default 8k/1k selection for this URL — table and chart below update if you change sequence or model in the controls. Each side uses the best available serving configuration for that precision, which may include speculative decoding such as MTP where recipes exist — the same convention as the other comparison pages.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | FP8:4312.3BF16:3115.8 | FP8:3050.2BF16:2010.9 | FP8:2233.2BF16:1295.7 |
| Cost ($/M tok) | FP8:$0.111BF16:$0.154 | FP8:$0.158BF16:$0.239 | FP8:$0.215BF16:$0.371 |
| tok/s/MW | FP8:2521840BF16:1822092 | FP8:1783766BF16:1175989 | FP8:1305985BF16:757728 |
| Concurrency | FP8:~21BF16:~31 | FP8:~10BF16:~13 | FP8:~5BF16:~6 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.