B200: FP4 vs FP8 Precision Comparison
How FP4 and FP8 precision affect Qwen 3.5 397B-A17B inference on B200 (NVIDIA Blackwell). Throughput, latency, and cost across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
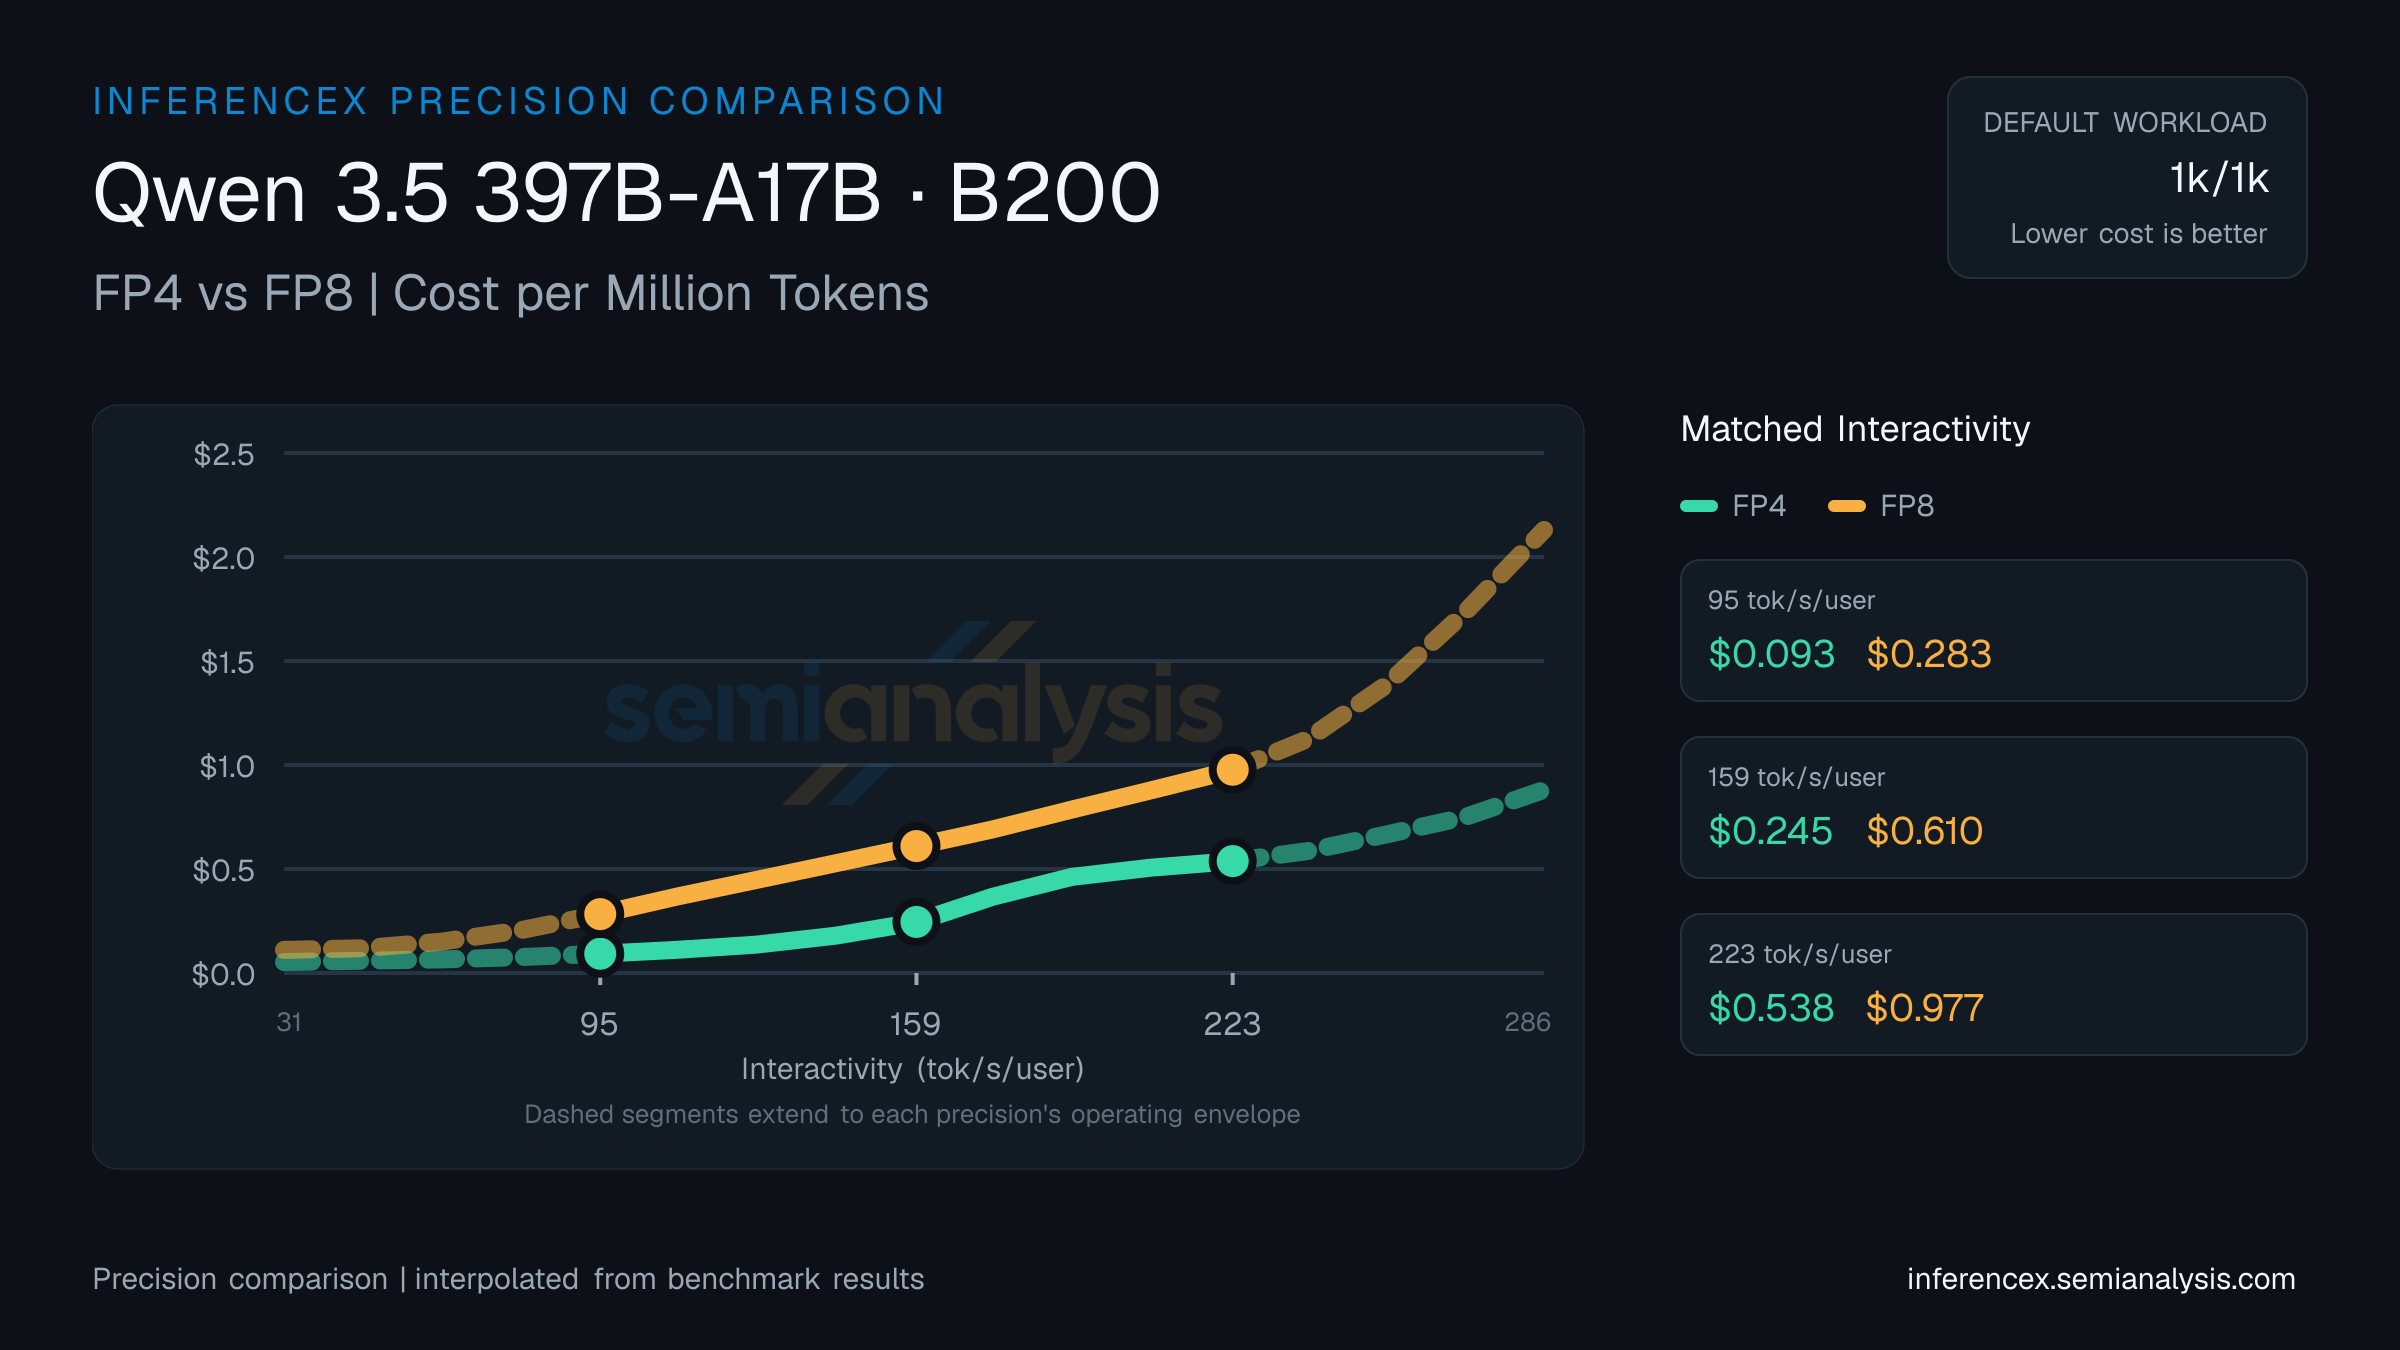
Throughput at 87 tok/s/user on Qwen 3.5 397B-A17B (B200): FP4 hits 9914 tok/s/chip, FP8 hits 7460. Per-million costs land at $0.05 and $0.06 respectively. FP4 is 33% cheaper per token; FP4 delivers 33% more tok/s/chip. The cost-throughput tradeoff from lower precision is only part of the picture — see the evaluation page for accuracy data.
Around the middle of the 10–320 tok/s/user interactivity band, at 165 tok/s/user on Qwen 3.5 397B-A17B (B200): FP4 runs 5654 tok/s/chip at $0.09/M tokens, FP8 runs 4586 at $0.10/M. FP4 is 23% cheaper per token; FP4 delivers 23% more tok/s/chip. Precision changes affect both inference speed and model quality — consult the evaluation tab for accuracy benchmarks.
At 243 tok/s/user on Qwen 3.5 397B-A17B (B200), FP4 delivers 3716 tok/s/chip at $0.13 per million tokens; FP8 delivers 3062 tok/s/chip at $0.16. FP4 is 21% cheaper per token; FP4 delivers 21% more tok/s/chip. Lower-precision quantization trades model accuracy for throughput — check the evaluation page for quality impact. (Numbers reflect the default 8k/1k selection for this URL — table and chart below update if you change sequence or model in the controls. Each side uses the best available serving configuration for that precision, which may include speculative decoding such as MTP where recipes exist — the same convention as the other comparison pages.)
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | FP4:9914.1FP8:7460.3 | FP4:5653.6FP8:4585.8 | FP4:3715.7FP8:3062.5 |
| Cost ($/M tok) | FP4:$0.048FP8:$0.064 | FP4:$0.085FP8:$0.105 | FP4:$0.129FP8:$0.157 |
| tok/s/MW | FP4:5797709FP8:4362757 | FP4:3306176FP8:2681759 | FP4:2172936FP8:1790917 |
| Concurrency | FP4:~128FP8:~41 | FP4:~9FP8:~13 | FP4:~4FP8:~6 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.