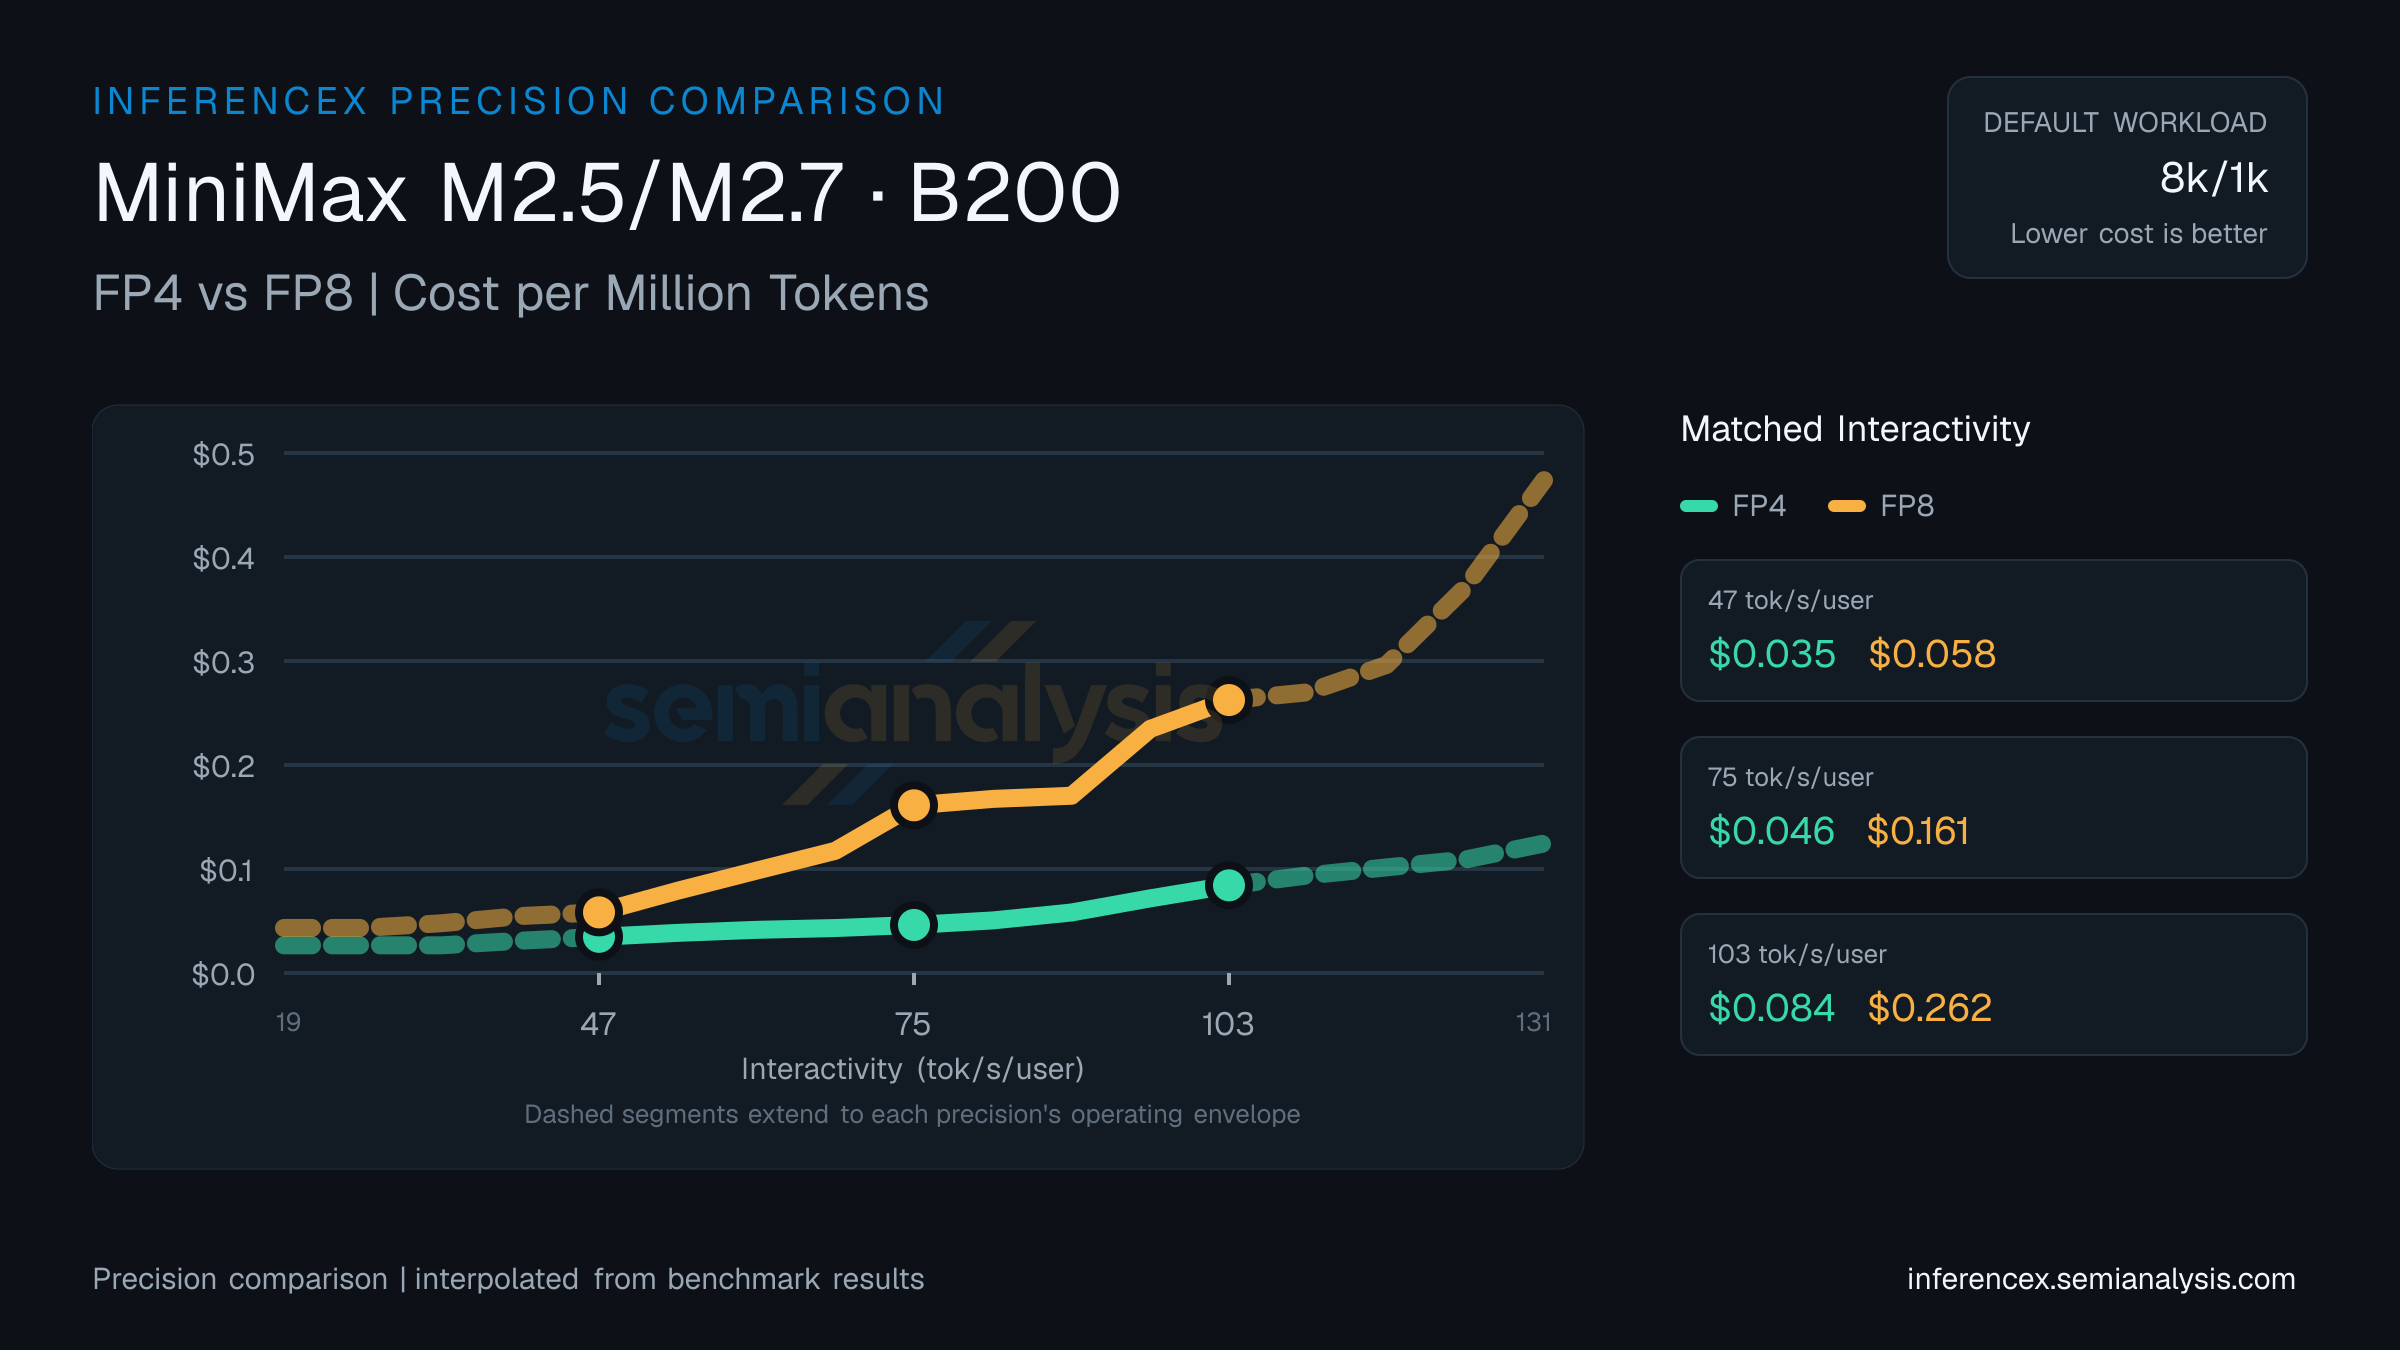
MiniMax M2.5/M2.7 · B200 · Precision comparison
B200: FP4 vs FP8 precision comparison
How FP4 and FP8 precision affect MiniMax M2.5/M2.7 inference on B200 (NVIDIA Blackwell). Throughput, latency, and cost across LLM workloads. Use the chart controls below to switch sequences and metrics — same interactions as the main inference chart.
At 51 tok/s/user on MiniMax M2.5/M2.7 (B200), FP4 delivers 10,989 tok/s/chip at $0.044 per million tokens; FP8 delivers 3,694 tok/s/chip at $0.13. FP4 delivers 197% more tok/s/chip on the same chip, which makes it 66% cheaper per token. Lower-precision quantization trades model accuracy for throughput — check the evaluation page for quality impact.
FP4 posts 6,499 tok/s/chip for $0.074 per million tokens at 81 tok/s/user on MiniMax M2.5/M2.7 (B200); FP8 posts 1,698 tok/s/chip for $0.28. FP4 delivers 3.8× the tok/s/chip on the same chip, which makes it 74% cheaper per token. Quantization-level accuracy differences are tracked on the evaluation tab.
Throughput at 111 tok/s/user on MiniMax M2.5/M2.7 (B200): FP4 hits 2,605 tok/s/chip, FP8 hits 743. Costs per million tokens land at $0.18 and $0.65 respectively. FP4 delivers 3.5× the tok/s/chip on the same chip, which makes it 71% cheaper per token. The cost-throughput tradeoff from lower precision is only part of the picture — see the evaluation page for accuracy data. (Numbers reflect the default 1k/1k selection for this URL — table and chart below update if you change sequence or model in the controls. Each side uses the best available serving configuration for that precision, which may include speculative decoding such as MTP where recipes exist — the same convention as the other comparison pages.)
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Throughput (tok/s/chip) | FP410,989FP83,694 | FP46,499FP81,698 | FP42,605FP8743 |
| Cost ($/M tok) | FP4$0.044FP8$0.13 | FP4$0.074FP8$0.28 | FP4$0.18FP8$0.65 |
| tok/s/MW | FP46,426,102FP82,160,332 | FP43,800,856FP8992,971 | FP41,523,597FP8434,645 |
| Concurrency | FP4~1,024FP8~399 | FP4~1,005FP8~41 | FP4~128FP8~14 |