Qwen 3.8 Flash Next 176B-A6B — B300 vs Vera Rubin NVL72 Performance per Dollar
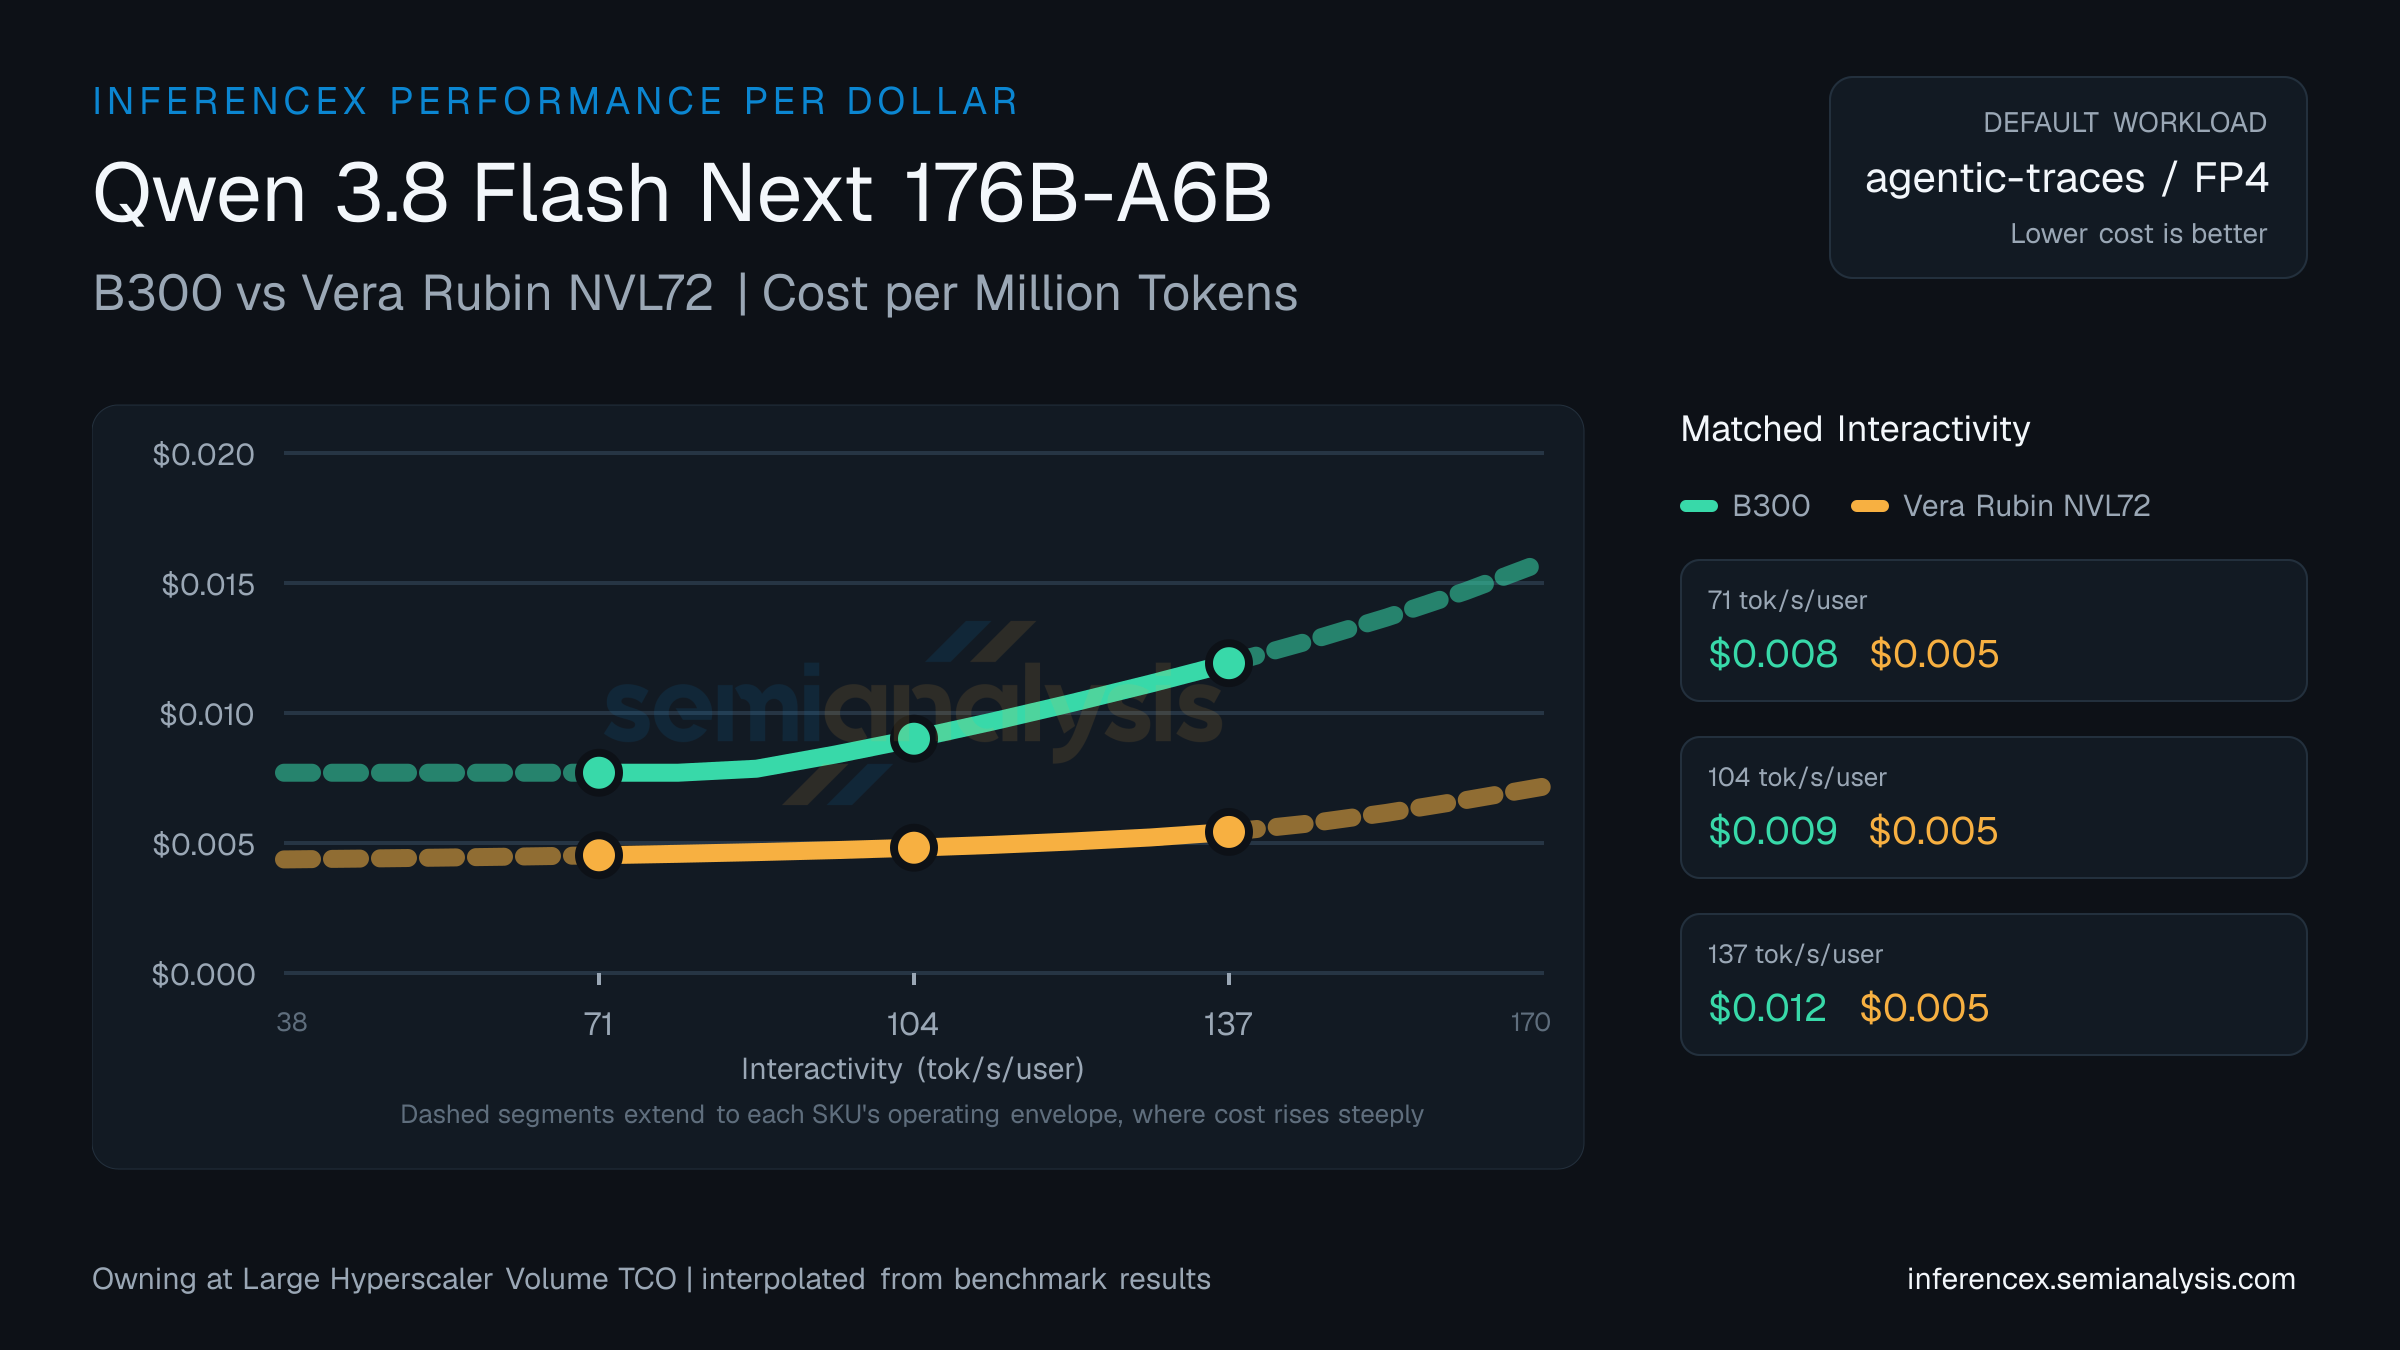
Cost per million tokens of B300 (NVIDIA Blackwell) versus Vera Rubin NVL72 (NVIDIA Vera Rubin) on Qwen 3.8 Flash Next 176B-A6B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
On Qwen 3.8 Flash Next 176B-A6B at 71 tok/s/user, the per-million math comes out to $0.01 for B300 and $0.00 for Vera Rubin NVL72; Vera Rubin NVL72 delivers 70% more total tokens per dollar.
At 104 tok/s/user on Qwen 3.8 Flash Next 176B-A6B, B300 costs $0.01 per million tokens; Vera Rubin NVL72 costs $0.00. Vera Rubin NVL72 is 87% more cost-efficient at this operating point.
Vera Rubin NVL72 edges B300 at 137 tok/s/user on Qwen 3.8 Flash Next 176B-A6B — $0.01 per million tokens versus $0.01, a 120% cost-per-token gap. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): B300 $2.26/chip/hr · Vera Rubin NVL72 $3.61/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | B300:$0.008Vera Rubin NVL72:$0.005 | B300:$0.009Vera Rubin NVL72:$0.005 | B300:$0.012Vera Rubin NVL72:$0.005 |
| Concurrency | B300:~16Vera Rubin NVL72:~216 | B300:~13Vera Rubin NVL72:~272 | B300:~10Vera Rubin NVL72:~286 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.