MiniMax M3.1 Flash 428B — GB200 NVL72 vs H100 Performance per Dollar
Cost per million tokens of GB200 NVL72 (NVIDIA Blackwell) versus H100 (NVIDIA Hopper) on MiniMax M3.1 Flash 428B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
AgentX replays real coding-agent sessions rather than fixed-length prompts, so context grows turn over turn and most of each request is served from cache instead of being recomputed. That turns the comparison into a systems question: KV transfer between nodes, prefix-aware routing, and cache capacity all move the curve alongside raw chip throughput. Fixed-sequence workloads stay the clean baseline for kernel and silicon performance, so the two scenarios answer different questions about the same hardware. Learn more about AgentX →
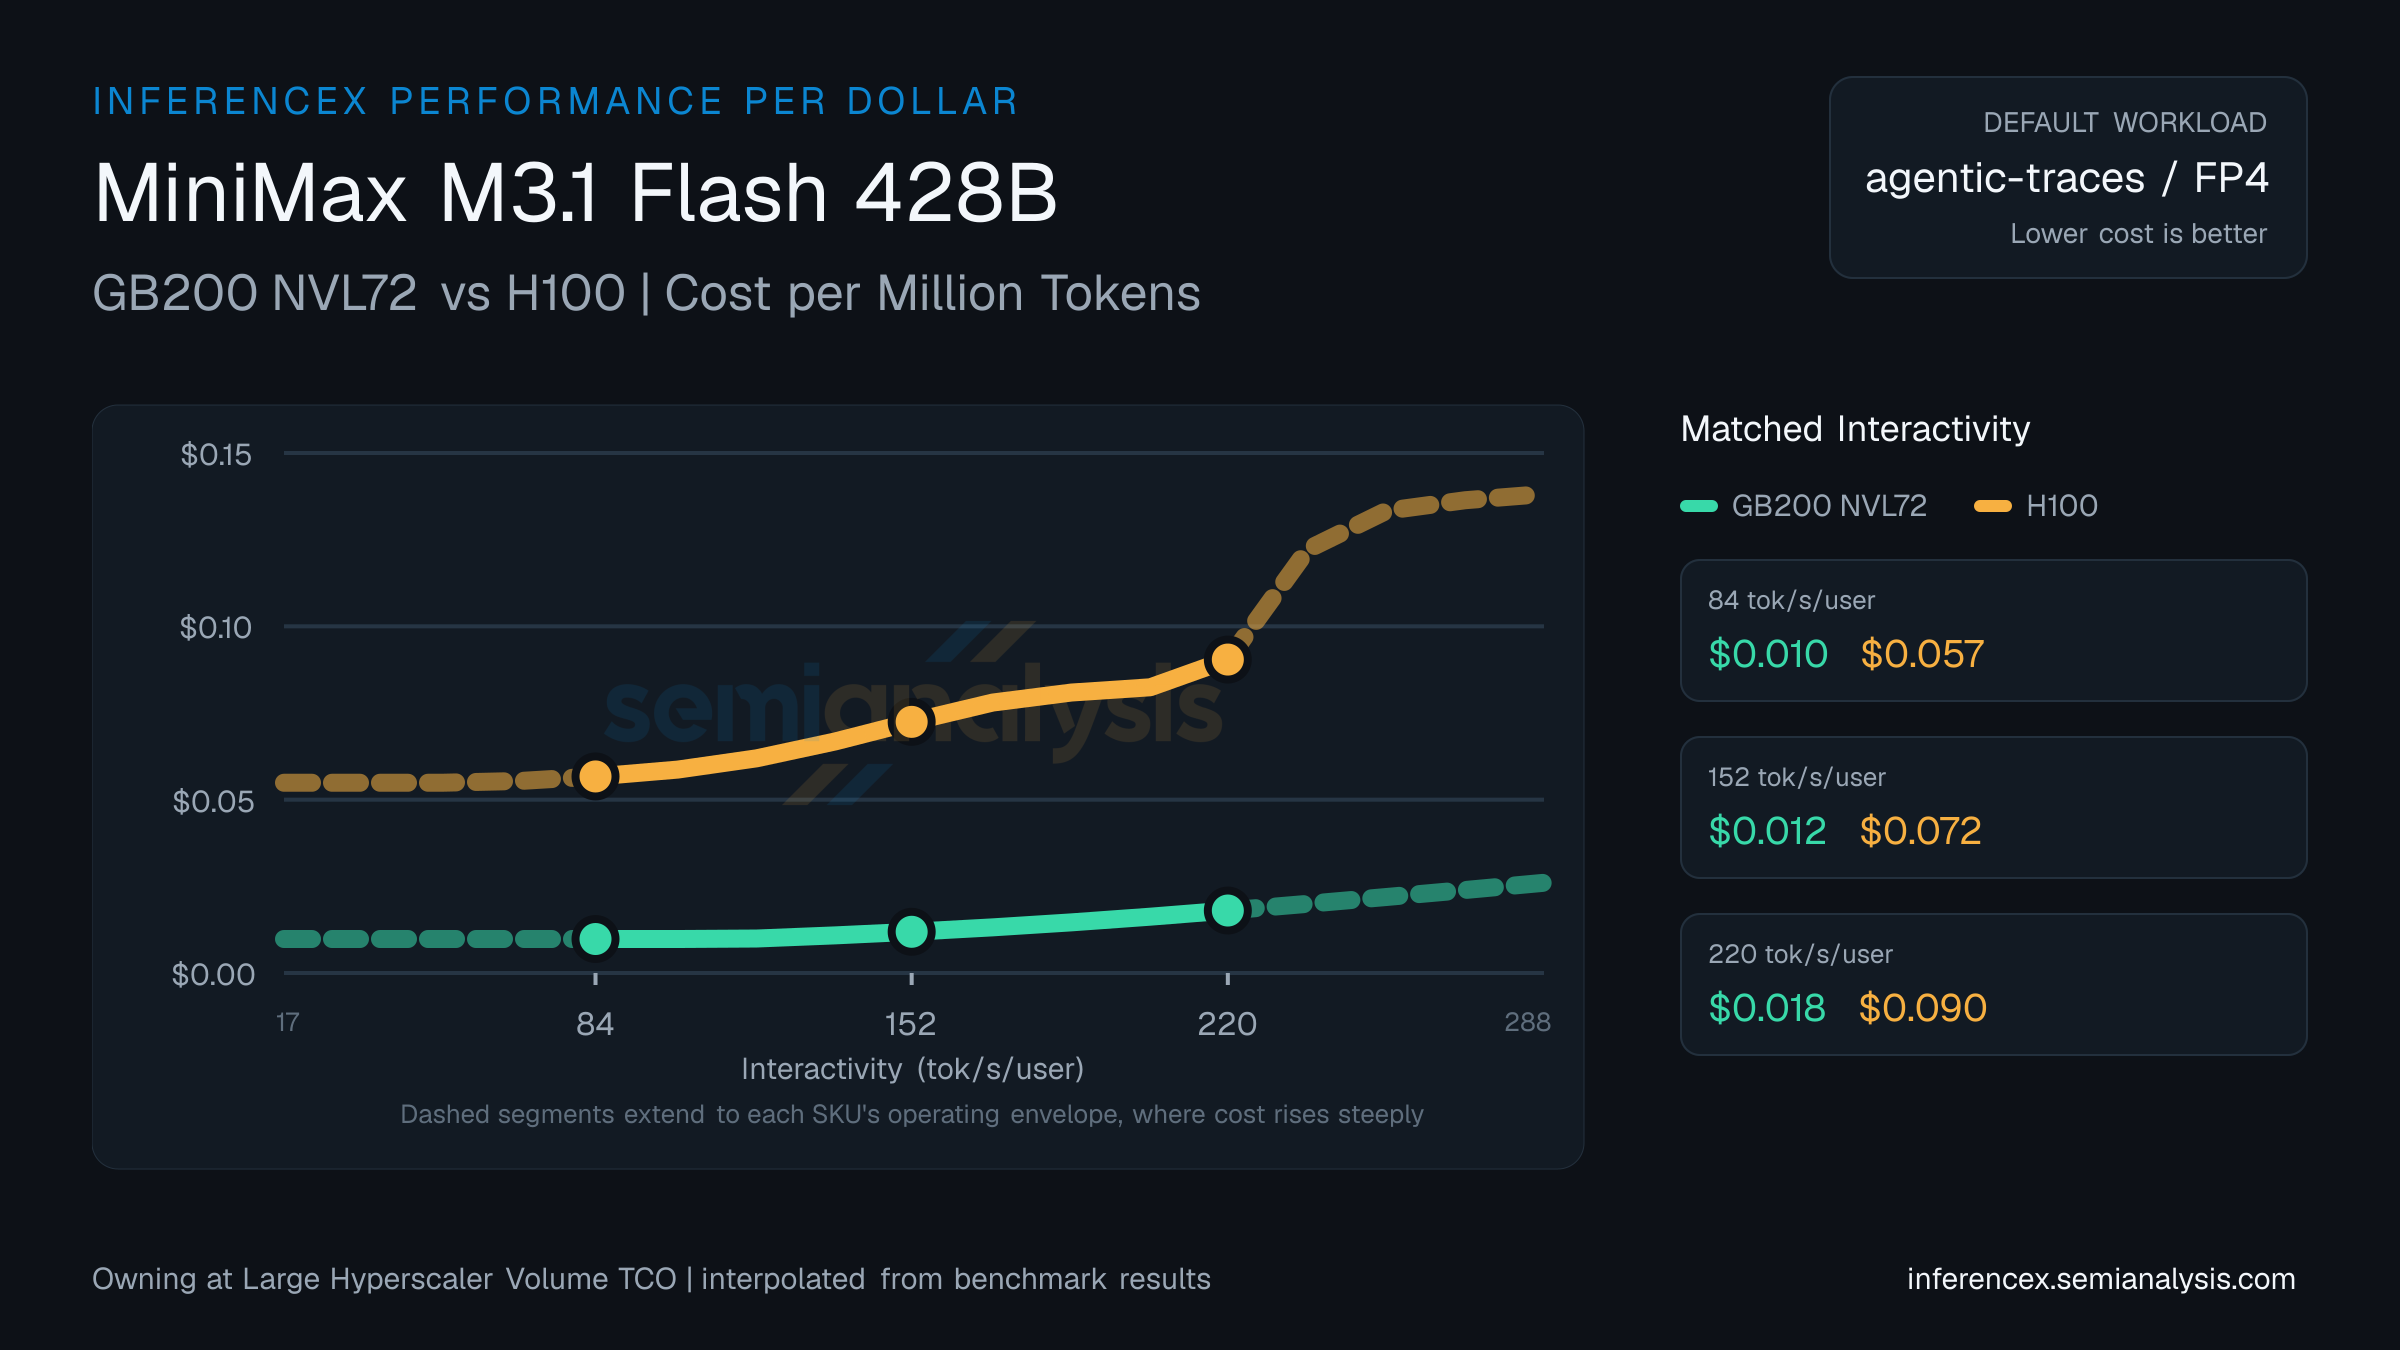
GB200 NVL72: $0.01 per million tokens. H100: $0.06. Both at 84 tok/s/user on MiniMax M3.1 Flash 428B, with GB200 NVL72 478% cheaper.
Around the middle of the 17–288 tok/s/user interactivity band — at 152 tok/s/user — GB200 NVL72 runs $0.01 per million tokens on MiniMax M3.1 Flash 428B while H100 runs $0.07. GB200 NVL72 is the cheaper choice by 509%.
On MiniMax M3.1 Flash 428B at 220 tok/s/user, the per-million math comes out to $0.02 for GB200 NVL72 and $0.09 for H100; GB200 NVL72 delivers 402% more total tokens per dollar. (Numbers reflect the default agentic-traces · fp4 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): GB200 NVL72 $1.86/chip/hr · H100 $1.17/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollar per Million Tokens | GB200 NVL72:$0.010H100:$0.057 | GB200 NVL72:$0.012H100:$0.072 | GB200 NVL72:$0.018H100:$0.090 |
| Concurrency | GB200 NVL72:~32H100:~9 | GB200 NVL72:~26H100:~7 | GB200 NVL72:~16H100:~3 |
Inference Performance
Agentic inference metrics from the AgentX scenario and fixed-sequence inference metrics across models, hardware configurations, and serving parameters.
No data available
No measurements to plot for this selection. Review the benchmark controls above or adjust quick filters.