Llama 3.3 70B · Performance per Dollar
Llama 3.3 70B — H200 vs MI300X Performance per Dollar
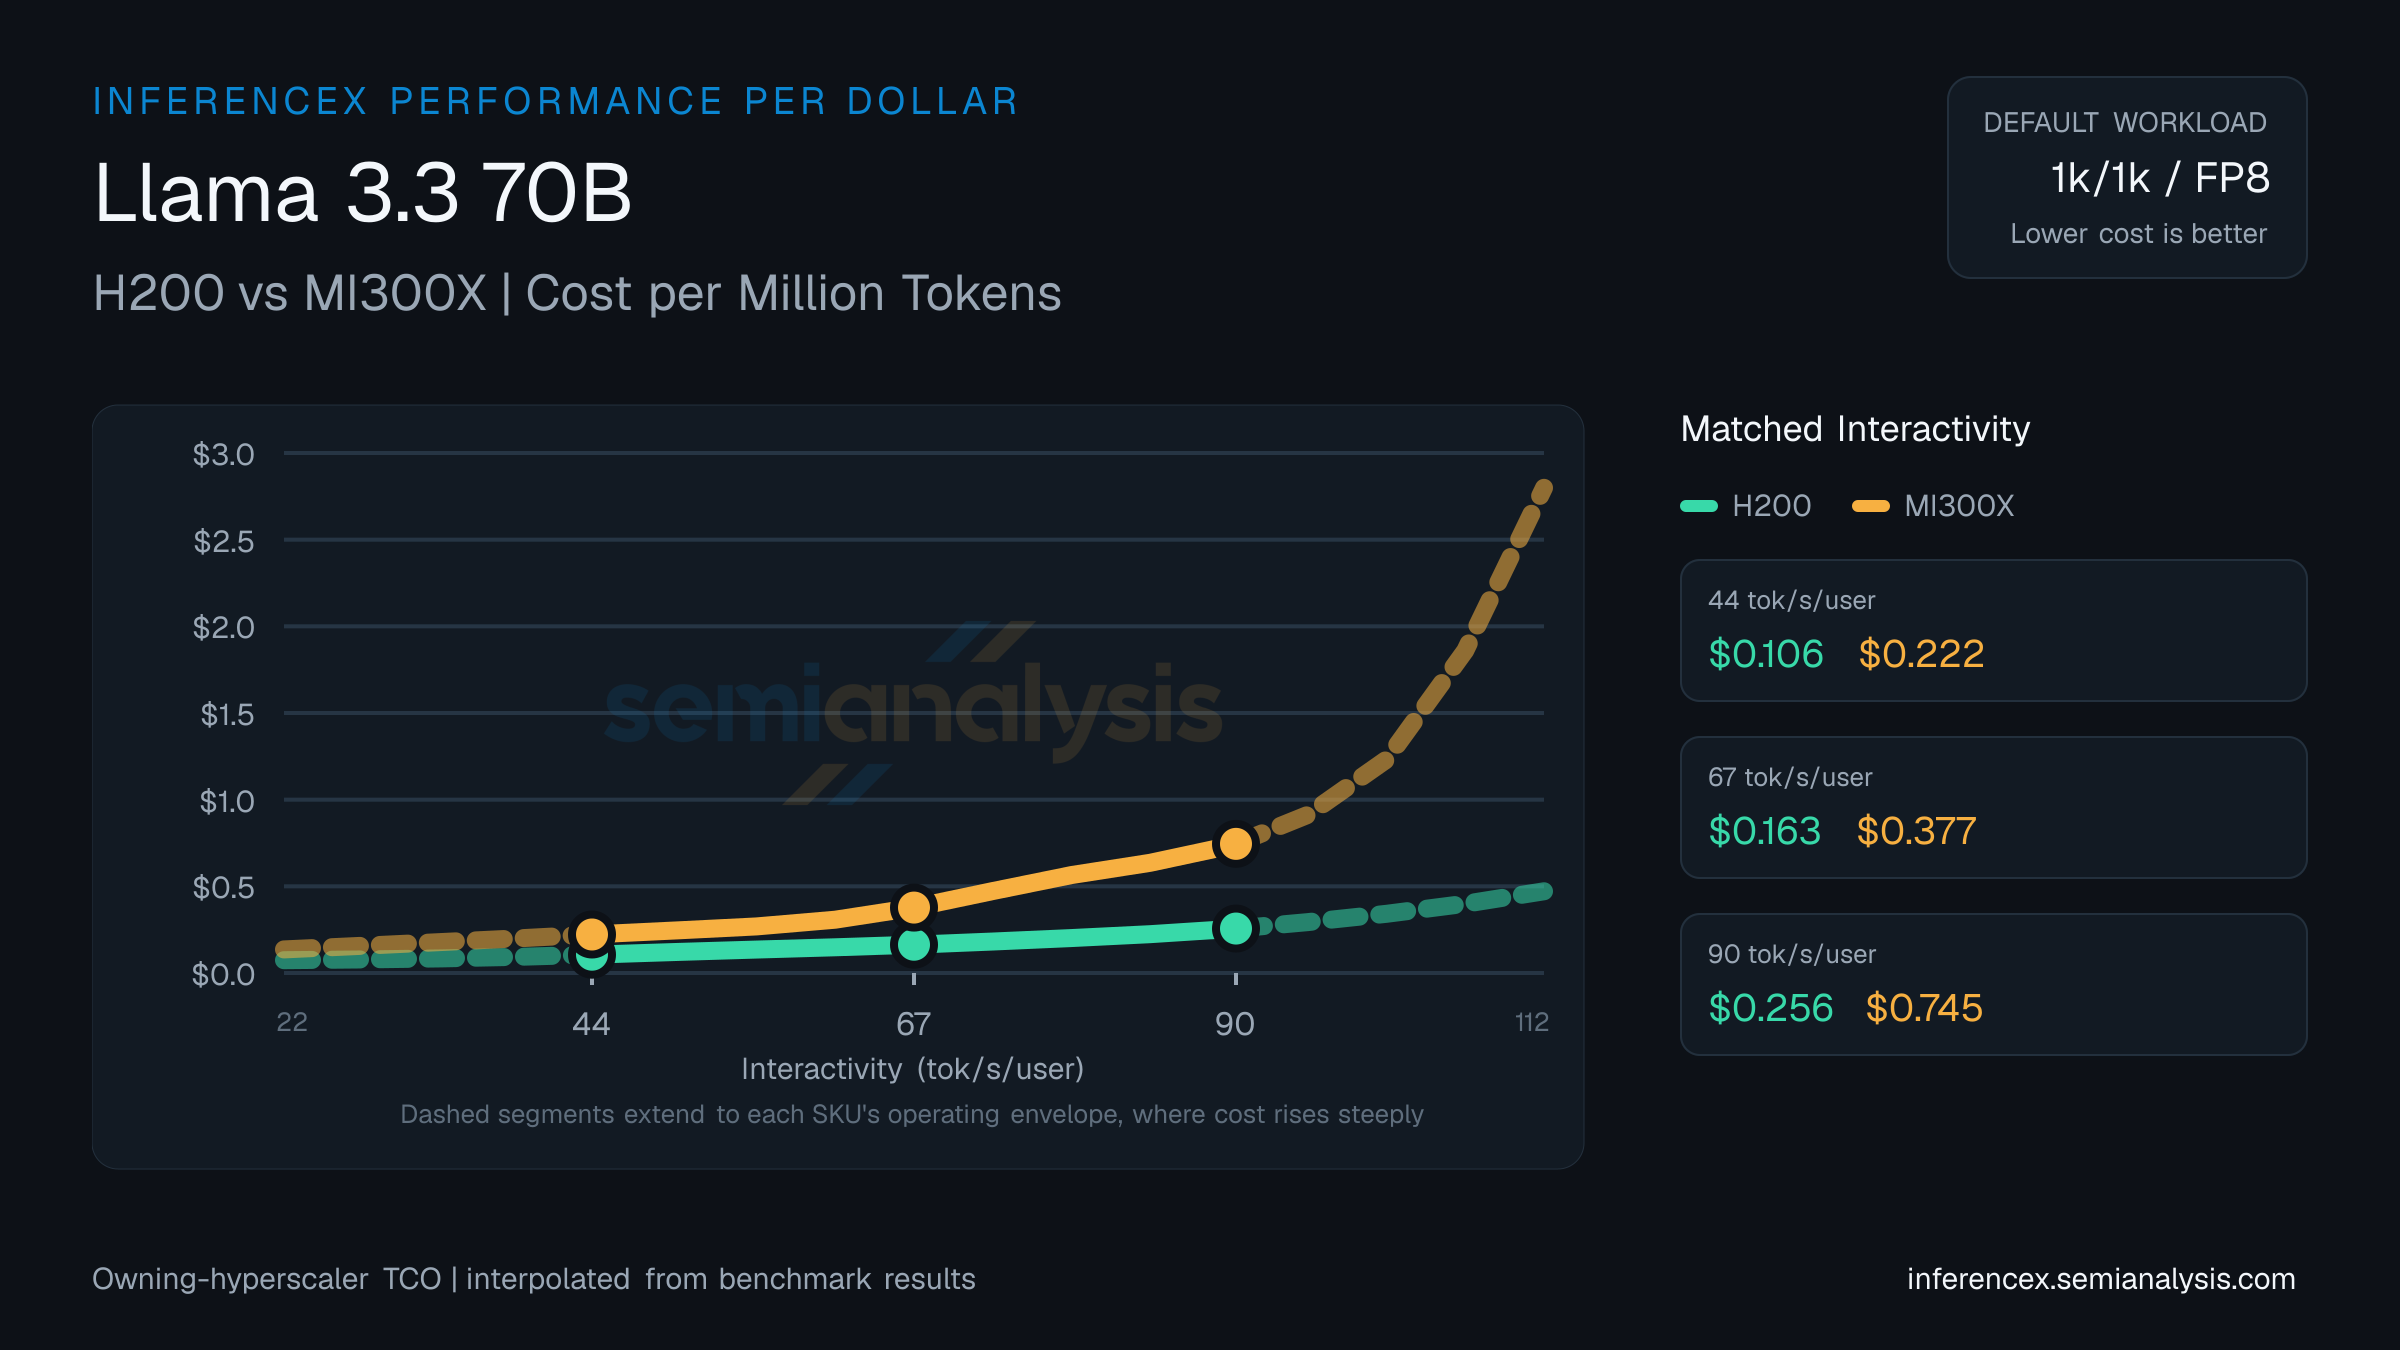
Cost per million tokens of H200 (NVIDIA Hopper) versus MI300X (AMD CDNA 3) on Llama 3.3 70B. Large-hyperscaler-volume ownership TCO normalized by total tokens — performance per dollar across LLM workloads. Pick the more cost-efficient SKU at every target interactivity level. Use the chart controls below to switch sequences, precisions, and metrics — same interactions as the main inference chart.
H200: $0.093 per million tokens. MI300X: $0.14. Both at 32 tok/s/user on Llama 3.3 70B, with H200 32% cheaper.
Around the middle of the 9–101 tok/s/user interactivity band — at 55 tok/s/user — H200 runs $0.13 per million tokens on Llama 3.3 70B while MI300X runs $0.21. H200 is the cheaper choice by 38%.
On Llama 3.3 70B at 78 tok/s/user, the per-million math comes out to $0.18 for H200 and $0.38 for MI300X; H200 delivers 111% more total tokens per dollar. (Numbers reflect the default 8k/1k · fp8 selection for this URL — table and chart below update if you change sequence, precision, or model in the controls.)
Chip pricing (owning hyperscaler): H200 $1.22/chip/hr · MI300X $0.95/chip/hr. Source: SemiAnalysis Market July 2026 Pricing Surveys & AI Cloud TCO Model.
Interpolated from real benchmark data. Edit target interactivity values below to compare at different operating points.
| Metric | Interactivity (tok/s/user) | Interactivity (tok/s/user) | Interactivity (tok/s/user) |
|---|---|---|---|
| Dollars per Million Tokens | H200$0.093MI300X$0.14 | H200$0.13MI300X$0.21 | H200$0.18MI300X$0.38 |
| Concurrency | H200~32MI300X~31 | H200~26MI300X~16 | H200~10MI300X~10 |